Veo 3.1 vs Veo 3
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
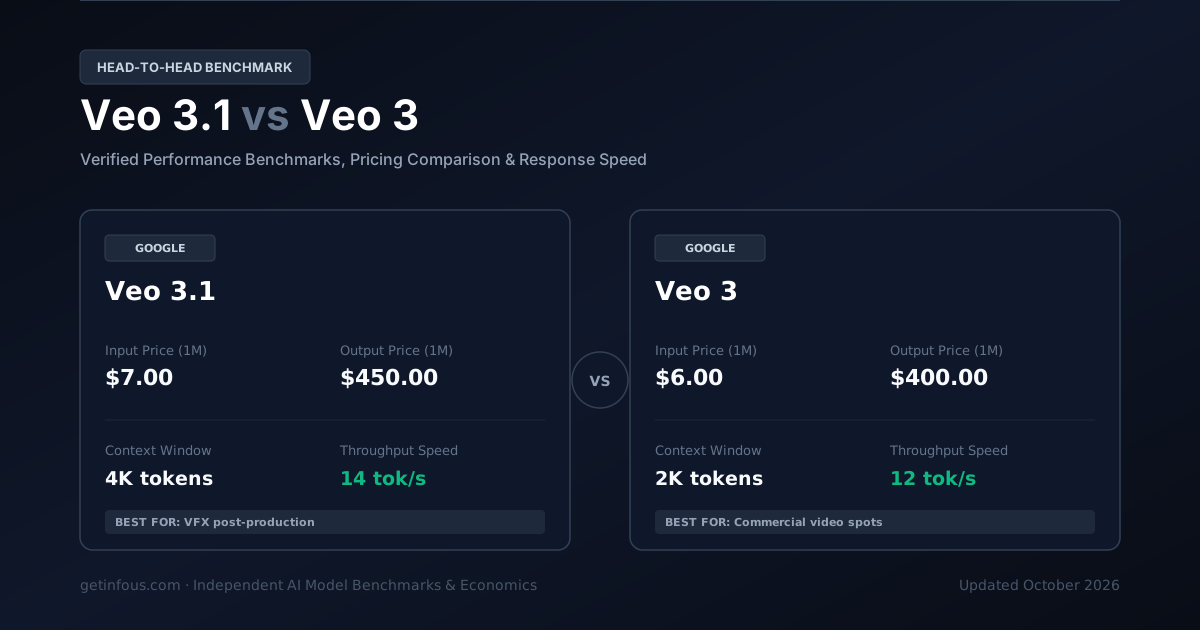
Veo 3.1 by Google and Veo 3 by Google represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Veo 3 holds a notable pricing advantage for token ingestion. On output generation, Veo 3 is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, Veo 3.1 provides an expanded memory horizon with 4K tokens. In latency-sensitive production environments, Veo 3.1 leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Cambia y Compara Cualquier Modelo
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Veo 3.1
Edición de videoAdvanced video generación motor que ofrece timeline-level motion editing, re-lighting, y camera trajectory control.
$7.00 / 1M
$450.00 / 1M
4.1K tokens
N/A
Veo 3
Video + audioBreakthrough generative video modelo producing 4K footage con synchronized nativo audio y sound effects.
$6.00 / 1M
$400.00 / 1M
2K tokens
N/A
Diferencias Clave de un Vistazo
- Veo 3 is 1.1x cheaper for API usage (input + output tokens combined).
- Veo 3.1 has a larger context window (4K vs 2K tokens).
- Veo 3.1 is faster at 14 tok/s vs 12 tok/s.
| Característica | Veo 3.1 | Veo 3 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 88 | 85 |
Provider | ||
Input Price Cost per million input tokens | $7.00 / 1M | $6.00 / 1M |
Output Price Cost per million output tokens | $450.00 / 1M | $400.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $46.40 / 1M | $41.20 / 1M |
Context Window Maximum input + output tokens | 4.1K tokens~6 A4 pages of text | 2K tokens~3 A4 pages of text |
Max Output Tokens Per single request | 4K | 4K |
Throughput Speed Tokens generated per second | 14 tok/s | 12 tok/s |
SWE-bench Verified Real-world software engineering | N/A | N/A |
¿Quién gana en cada área?
At-a-glance decision frameworkEvaluations ongoing
Puntuaciones de Benchmarks Verificadas
Official evaluation metrics verified by independent third-party research labs.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
Latencia y Tiempo de Respuesta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulador Interactivo de Costos de Tokens
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Veo 3.1 · Strengths & Key Advantages
- Keyframe-directed video editing y inpainting
- Manipulación sofisticada de iluminación dinámica
- Enhanced multi-character temporal coherencia
Considerations & Trade-offs
- Gasto computacional costoso
- complejo API controls require prompt engineering
Veo 3 · Strengths & Key Advantages
- Synchronous alto-fidelity environmental audio y voz
- Opción de renderizado cinematográfico en 4K
- Consistencia temporal fluida en generaciones de 30 segundos
Considerations & Trade-offs
- sustancial generación costo ($0.40/second)
- Tiempo de espera de renderizado de varios minutos
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Veo 3.1 | Veo 3 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $3.00 | $2.50 |
Output Tokens / Task Tokens generated per task | 0K | 0K |
Reasoning Tokens / Task Thinking tokens burned per task | 0K | 0K |
Especificaciones Técnicas
Architecture, release timeline, capabilities, and modalities.
| Característica | Veo 3.1 | Veo 3 |
|---|---|---|
| Official API Model ID (SDK) | models/veo-3-1 | models/veo-3 |
| API Protocol | Google Gemini API (generateContent) + OpenAI-Compatible SDK | Google Gemini API (generateContent) + OpenAI-Compatible SDK |
| Release Date | 2025-10 | 2025-05 |
| Knowledge Cutoff | July 2025 | February 2025 |
| Architecture | Controllable audio-video generation and in-context video editor | Joint multimodal audio-video diffusion transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($7/1M in) across full 4K window | Flat rate ($6/1M in) across full 2K window |
| Prompt Cache Policy & TTL | Implicit + Explicit Context Caching at $0/1M with configurable TTL | Implicit + Explicit Context Caching at $0/1M with configurable TTL |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Prompt-based JSON extraction only | Prompt-based JSON extraction only |
| Web Search Grounding & Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox |
| Official Fine-Tuning Support | Vertex AI Supervised Adapter Tuning & Context Distillation | Vertex AI Supervised Adapter Tuning & Context Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Google DeepMind Frontier Safety Framework Verified | Google DeepMind Frontier Safety Framework Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision |
| Output Modalities | video | video |
Veo 3.1 vs Veo 3: Respuestas Rápidas (FAQ)
Which is more intelligent, Veo 3.1 or Veo 3?
Veo 3.1 is more intelligent. It scores 88 compared with 85 on the composite Intelligence Index.
Which model is faster?
Veo 3.1 is faster, generating 14 tokens per second compared with 12 tokens per second.
Which model is cheaper to run?
Veo 3 is cheaper at $41.20 per 1M tokens blended, compared with $46.40 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Veo 3.1 has lower latency, with a time to first token of 4.20s compared with 4.50s.
Which model has a larger context window?
Veo 3.1 has a larger context window, supporting 4.1K tokens compared with 2K tokens.
Veredicto
Verdict & Model Selection Recommendation: Choose Veo 3.1 if your priority is VFX post-production, film editing workflows, and high-end video advertising. Its performance in demanding tasks justifies its operational token cost. Choose Veo 3 if your workflow prioritizes Commercial video spots, music video visualizers, and narrative film production. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Preguntas frecuentes
How does Veo 3.1 compare to Veo 3 in API token pricing and cost per token?+
Veo 3.1 costs $7.00 per 1M input tokens and $450.00 per 1M output tokens, whereas Veo 3 costs $6.00 input and $400.00 output. Overall, Veo 3 is the more cost-effective model for high-volume API pipelines.
Which model has a larger context window: Veo 3.1 or Veo 3?+
Veo 3.1 supports a context window of 4K tokens (~3k words), while Veo 3 supports 2K tokens (~2k words). Therefore, Veo 3.1 can process more textual data and document context in a single prompt.
Which AI model is better for software engineering and coding: Veo 3.1 or Veo 3?+
Veo 3.1 scores at the frontier of coding benchmarks, while Veo 3 scores competitively for software generation. For complex autonomous debugging and agentic engineering, Veo 3.1 provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between Veo 3.1 and Veo 3?+
Veo 3.1 is optimized for low-latency direct generation. In contrast, Veo 3 focuses on standard fast inference.
How does inference speed (tokens per second) compare between Veo 3.1 and Veo 3?+
Veo 3.1 generates approximately 14 tokens per second, while Veo 3 delivers 12 tokens per second. In latency-sensitive production environments, Veo 3.1 provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Veo 3.1 and Veo 3 to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Veo 3 to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Veo 3.1. This tiered routing pattern cuts overall API bills by up to 70%.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Gemini Omni Flash vs Veo 3.1: Benchmarks, Pricing & Speed ComparisonComparar
- Veo 3.1 vs Grok Imagine Video 1.5: Benchmarks, Pricing & Speed ComparisonComparar
- Veo 3 vs Grok Imagine Video 1.5: Benchmarks, Pricing & Speed ComparisonComparar
- Veo 3 vs Veo 2: Benchmarks, Pricing & Speed ComparisonComparar
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed ComparisonComparar
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed ComparisonComparar
Las puntuaciones de benchmarks, precios por token y límites de tasa evolucionan rápidamente. Verifique siempre las especificaciones actuales en la documentación oficial del proveedor.
Fuentes: GetInfoUs Independent AI Benchmarks & Official API Specs