Qwen-VL Plus vs Claude 3 Opus
বেঞ্চমার্ক, এপিআই টোকেন মূল্য, কনটেক্সট উইন্ডো এবং ইনফারেন্স স্পিড তুলনা
Related topics (12)
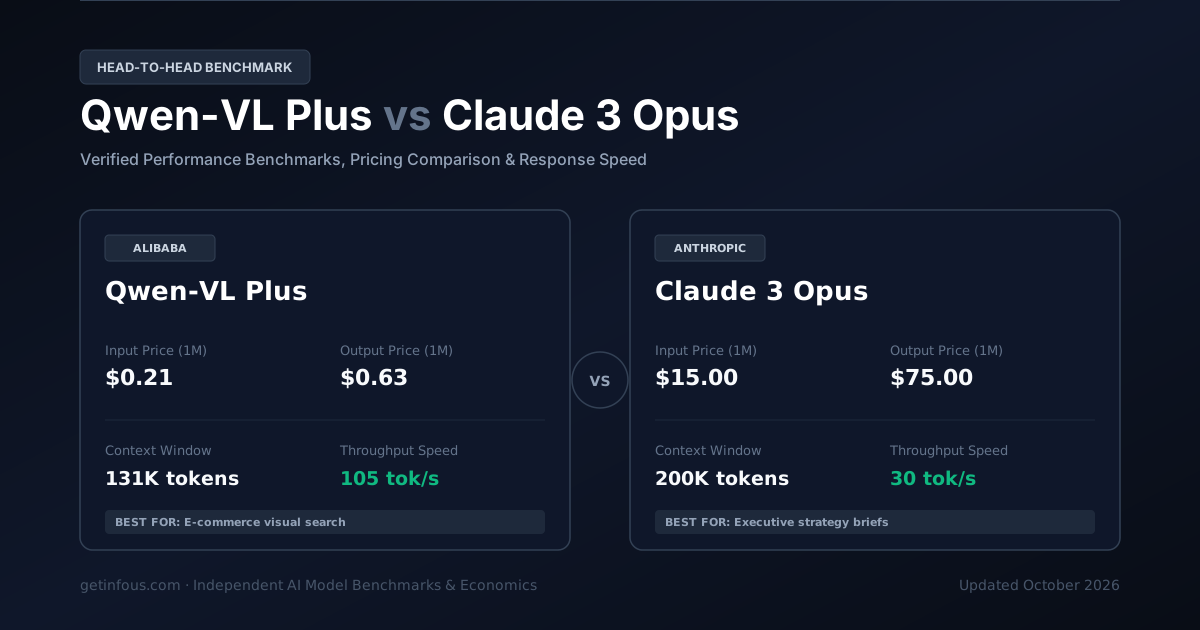
Qwen-VL Plus by Alibaba and Claude 3 Opus by Anthropic represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Qwen-VL Plus holds a notable pricing advantage for token ingestion. On output generation, Qwen-VL Plus is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, Claude 3 Opus provides an expanded memory horizon with 200K tokens. In latency-sensitive production environments, Qwen-VL Plus leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
যেকোনো দুটি এআই মডেল পরিবর্তন ও তুলনা করুন
আমাদের যাচাইকৃত বেঞ্চমার্ক ডাটাবেস থেকে যেকোনো এআই মডেল নির্বাচন করে তাৎক্ষণিক তুলনা দেখুন।
Qwen-VL Plus
ভিশন ব্যালেন্সডখরচ-effective মাল্টিমোডাল ভিশন মডেল এর জন্য সাধারণ ভিজ্যুয়াল অনুধাবন, ছবি captioning, এবং লাইটওয়েট OCR.
$0.21 / 1M
$0.63 / 1M
131.1K tokens
N/A
Claude 3 Opus
অনবদ্য গভীরতা ও প্রজ্ঞাClaude 3 পরিবারের শীর্ষস্থানীয় ফাউন্ডেশনাল ইন্টেলিজেন্স মডেল, যা এর অসাধারণ ভাবপ্রকাশের গভীরতা, সাহিত্যিক প্রকাশভঙ্গি এবং নির্ভুল রিজনিংয়ের জন্য বিশ্বজুড়ে সমাদৃত।
$15.00 / 1M
$75.00 / 1M
200K tokens
32.2%
একনজরে প্রধান পার্থক্যসমূহ
- Qwen-VL Plus is 101.0x cheaper for API usage (input + output tokens combined).
- Claude 3 Opus has a larger context window (200K vs 131K tokens).
- Qwen-VL Plus is faster at 105 tok/s vs 30 tok/s.
| বৈশিষ্ট্য | Qwen-VL Plus | Claude 3 Opus |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 71 | 44 |
Provider | Alibaba | Anthropic |
Input Price Cost per million input tokens | $0.21 / 1M | $15.00 / 1M |
Output Price Cost per million output tokens | $0.63 / 1M | $75.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.12 / 1M | $11.55 / 1M |
Context Window Maximum input + output tokens | 131.1K tokens~197 A4 pages of text | 200K tokens~300 A4 pages of text |
Max Output Tokens Per single request | 8K | 4K |
Throughput Speed Tokens generated per second | 105 tok/s | 30 tok/s |
SWE-bench Verified Real-world software engineering | N/A | 32.2% |
GPQA Diamond Graduate-level reasoning | N/A | 50.4% |
Cached Input Price Prompt caching discount per 1M tokens | $0.02 / 1M | $1.50 / 1M |
কোন ক্ষেত্রে কোন মডেল সেরা?
একনজরে সিদ্ধান্ত নেওয়ার ফ্রেমওয়ার্কEvaluations ongoing
যাচাইকৃত বেঞ্চমার্ক স্কোর তুলনা
স্বাধীন গবেষণা ল্যাব দ্বারা যাচাইকৃত অফিশিয়াল ইভ্যালুয়েশন মেট্রিক্স।
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
লেটেন্সি ও রেসপন্স টাইম
প্রথম টোকেন আসার সময় (TTFT) এবং ৫০০ টোকেনের রেসপন্স জেনারেট করতে আনুমানিক সময়।
রিয়েল-টাইম টোকেন খরচ সিমুলেটর
প্রম্পট ক্যাশিং ডিসকাউন্টসহ মাসিক ক্লাউড API খরচ হিসাব করতে স্লাইডার পরিবর্তন করুন।
Qwen-VL Plus · শক্তি ও প্রধান সুবিধাসমূহ
- অত্যন্ত সাশ্রয়ী মাল্টিমোডাল ভিজ্যুয়াল ইনফারেন্স ($0.21/1M টোকেন)
- দ্রুত ছবি বিশ্লেষণ এবং response প্রজন্ম
- ভালো baseline পারফরম্যান্স এর ওপর photo descriptions এবং ভিজ্যুয়াল ট্যাগিং
বিবেচ্য বিষয় ও সীমাবদ্ধতা
- কম সঠিকতা চেয়ে Qwen-VL Max এর ওপর intricate উচ্চ-density financial tables
- Struggles সহ ছোট font টেক্সট মধ্যে স্বল্প-রেজোলিউশন ছবিগুলো
Claude 3 Opus · শক্তি ও প্রধান সুবিধাসমূহ
- Deepest textual সূক্ষ্ম ভাবপ্রকাশ, philosophical রিজনিং, এবং literary flair মধ্যে industry
- প্রথম মডেল প্রতি dethrone GPT-4 এর ওপর LMSYS Chatbot Arena leaderboard মধ্যে early 2024
- ব্যতিক্রমী ভিশন অনুধাবন এর charts, handwritten diagrams, এবং schematics
বিবেচ্য বিষয় ও সীমাবদ্ধতা
- Premium মূল্য টিয়ার ($15/$75 প্রতি 1M টোকেন)
- কম প্রজন্ম গতি (30 tok/s) এর তুলনায় Claude 3.5 Sonnet
টোকেন ব্যবহার ও টাস্ক ইকোনমিক্স
একটি স্ট্যান্ডার্ড এজেন্টিক টাস্ক সম্পন্ন করতে আনুমানিক খরচ এবং টোকেন ব্যবহার।
| Metric | Qwen-VL Plus | Claude 3 Opus |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.05 | $0.20 |
Output Tokens / Task Tokens generated per task | 14K | 24K |
Reasoning Tokens / Task Thinking tokens burned per task | 2K | 0K |
টেকনিক্যাল স্পেসিফিকেশন
অফিশিয়াল প্রোভাইডার রিলিজ স্পেক্স, API মডেল আইডি, রেট লিমিট, লং-কনটেক্সট প্রাইসিং ও এজেন্টিক সক্ষমতা
| বৈশিষ্ট্য | Qwen-VL Plus | Claude 3 Opus |
|---|---|---|
| অফিশিয়াল API মডেল আইডি (SDK) | qwen-vl-plus-instruct | claude-3-opus-20240301 |
| API প্রোটোকল | Alibaba REST API (OpenAI-Compatible) | Anthropic Messages API + AWS Bedrock + Vertex AI |
| রিলিজ তারিখ | 2024-01 | 2024-03 |
| নলেজ কাটঅফ | December 2023 | August 2023 |
| আর্কিটেকচার | Efficient Multimodal Vision-Language Transformer | Frontier Dense Multimodal Transformer |
| প্যারামিটার স্কেল | Confidential | Confidential |
| এন্টারপ্রাইজ রেট লিমিট (RPM / TPM) | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM | 4,000 – 10,000 RPM (Tier 4 + Priority Tier) · 800,000 – 2,000,000 TPM |
| লং-কনটেক্সট প্রাইসিং (>128K/200K) | পূর্ণ 131K কনটেক্সট জুড়ে একই ফ্ল্যাট রেট ($0.21/1M) | ২০০K টোকেন পর্যন্ত সাধারণ রেট; ২০০K-এর ওপরে ২ গুণ প্রাইসিং টিয়ার প্রযোজ্য |
| প্রম্পট ক্যাশিং ও TTL | ক্যাশড ইনপুট রেট $0.021/1M টোকেন | $1.5/1M ক্যাশড রিড (৯০% সাশ্রয়); ৫ মিনিট ডিফল্ট ও ১ ঘণ্টা এক্সটেন্ডেড TTL |
| কম্পিউটার ইউজ / GUI এজেন্ট | সমর্থিত (স্ক্রিন কোঅর্ডিনেট গ্রাউন্ডিং, ব্রাউজার ও ডেস্কটপ GUI অটোমেশন) | সমর্থিত (স্ক্রিন কোঅর্ডিনেট গ্রাউন্ডিং, ব্রাউজার ও ডেস্কটপ GUI অটোমেশন) |
| MCP ও প্যারালাল টুল কলিং | নেটিভ MCP সাপোর্ট · প্যারালাল ফাংশন কলিং · ১০০% স্ট্রিক্ট JSON স্কিমা | নেটিভ MCP সাপোর্ট · প্যারালাল ফাংশন কলিং · ১০০% স্ট্রিক্ট JSON স্কিমা |
| ওয়েব সার্চ ও কোড স্যান্ডবক্স | এক্সটার্নাল সার্চ (Tavily/Exa) ও ডকার স্যান্ডবক্সের মাধ্যমে সমর্থিত | নেটিভ ওয়েব সার্চ সাইটেশন + কোড এক্সিকিউশন টুল ও MCP কানেক্টর |
| অফিশিয়াল ফাইন-টিউনিং (SFT/LoRA/RFT) | API প্রম্পট অপ্টিমাইজেশন ও RAG ইন্টিগ্রেশন | AWS Bedrock কাস্টম টিউনিং ও প্রম্পট ডিস্টিলেশন |
| মাল্টিমোডাল টোকেন বিলিং | টেক্সট BPE (~৪ অক্ষর/টোকেন) · ইমেজ (~২৫৮–৭৬৫ টোকেন/ছবি) | টেক্সট BPE (~৪ অক্ষর/টোকেন) · ইমেজ (~২৫৮–৭৬৫ টোকেন/ছবি) |
| কোয়ান্টাইজেশন ও মিনিমাম VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · লোকাল জিপিইউ প্রয়োজন নেই (১০০% ক্লাউড API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · লোকাল জিপিইউ প্রয়োজন নেই (১০০% ক্লাউড API) |
| সেফটি ও ফ্রন্টিয়ার ক্লাসিফিকেশন | Alibaba Production Safety & Alignment Verified | Anthropic RSP ASL-2 / ASL-3 Constitutional Safety Evaluated |
| এন্টারপ্রাইজ কমপ্লায়েন্স (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · এন্টারপ্রাইজ টিয়ারে Zero Data Retention (ZDR) ও HIPAA BAA সুবিধা | SOC2 Type II · GDPR · এন্টারপ্রাইজ টিয়ারে Zero Data Retention (ZDR) ও HIPAA BAA সুবিধা |
| ইনপুট মডালিটি | text, vision | text, vision |
| আউটপুট মডালিটি | text | text |
Qwen-VL Plus vs Claude 3 Opus: সংক্ষিপ্ত প্রশ্নোত্তর (FAQ)
Which is more intelligent, Qwen-VL Plus or Claude 3 Opus?
Qwen-VL Plus is more intelligent. It scores 71 compared with 44 on the composite Intelligence Index.
Which model is faster?
Qwen-VL Plus is faster, generating 105 tokens per second compared with 30 tokens per second.
Which model is cheaper to run?
Qwen-VL Plus is cheaper at $0.12 per 1M tokens blended, compared with $11.55 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Qwen-VL Plus has lower latency, with a time to first token of 0.48s compared with 1.20s.
Which model has a larger context window?
Claude 3 Opus has a larger context window, supporting 200K tokens compared with 131.1K tokens.
চূড়ান্ত মতামত
Verdict & Model Selection Recommendation: Choose Qwen-VL Plus if your priority is E-commerce visual search, social image captioning, and everyday visual QA. Its performance in demanding tasks justifies its operational token cost. Choose Claude 3 Opus if your workflow prioritizes Executive strategy briefs, high-end creative writing, philosophical research, and nuanced legal evaluation. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
সাধারণ জিজ্ঞাসা (FAQ)
How does Qwen-VL Plus compare to Claude 3 Opus in API token pricing and cost per token?+
Qwen-VL Plus costs $0.21 per 1M input tokens and $0.63 per 1M output tokens, whereas Claude 3 Opus costs $15.00 input and $75.00 output. Overall, Qwen-VL Plus is the more cost-effective model for high-volume API pipelines. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: Qwen-VL Plus or Claude 3 Opus?+
Qwen-VL Plus supports a context window of 131K tokens (~98k words), while Claude 3 Opus supports 200K tokens (~150k words). Therefore, Claude 3 Opus can process more textual data and document context in a single prompt.
Which AI model is better for software engineering and coding: Qwen-VL Plus or Claude 3 Opus?+
Qwen-VL Plus scores at the frontier of coding benchmarks, while Claude 3 Opus scores 32.2%. For complex autonomous debugging and agentic engineering, Claude 3 Opus provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between Qwen-VL Plus and Claude 3 Opus?+
Qwen-VL Plus is optimized for low-latency direct generation. In contrast, Claude 3 Opus focuses on standard fast inference.
How does inference speed (tokens per second) compare between Qwen-VL Plus and Claude 3 Opus?+
Qwen-VL Plus generates approximately 105 tokens per second, while Claude 3 Opus delivers 30 tokens per second. In latency-sensitive production environments, Qwen-VL Plus provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Qwen-VL Plus and Claude 3 Opus to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Qwen-VL Plus to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Claude 3 Opus. This tiered routing pattern cuts overall API bills by up to 70%.
মডেলের বিভিন্ন পরিমাপক যেমন কনটেক্সট উইন্ডো, টোকেন প্রাইজ এবং রিজনিং স্কোর সম্পর্কে বিস্তারিত জানতে আমাদের এআই গ্লোসারি দেখুন।
Related reading
- Claude 3.5 Sonnet vs Claude 3 Opus: Benchmarks, Pricing & Speed Comparisonতুলনা
- Claude 3 Opus vs GPT-4: Benchmarks, Pricing & Speed Comparisonতুলনা
- Gemini 1.5 Pro vs Claude 3 Opus: Benchmarks, Pricing & Speed Comparisonতুলনা
- Qwen-VL Plus vs Yi-Large: Benchmarks, Pricing & Speed Comparisonতুলনা
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed Comparisonতুলনা
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed Comparisonতুলনা
এআই ল্যাবগুলোর নতুন রিলিজের সাথে সাথে বেঞ্চমার্ক স্কোর, টোকেন প্রাইসিং এবং রেট লিমিট নিয়মিত পরিবর্তিত হয়। প্রোডাকশনে ব্যবহারের পূর্বে সর্বদা অফিশিয়াল প্রোভাইডার ডকুমেন্টেশন যাচাই করুন।
তথ্যসূত্র: GetInfoUs Independent AI Benchmarks & Official API Specs