الوظائف والرواتب
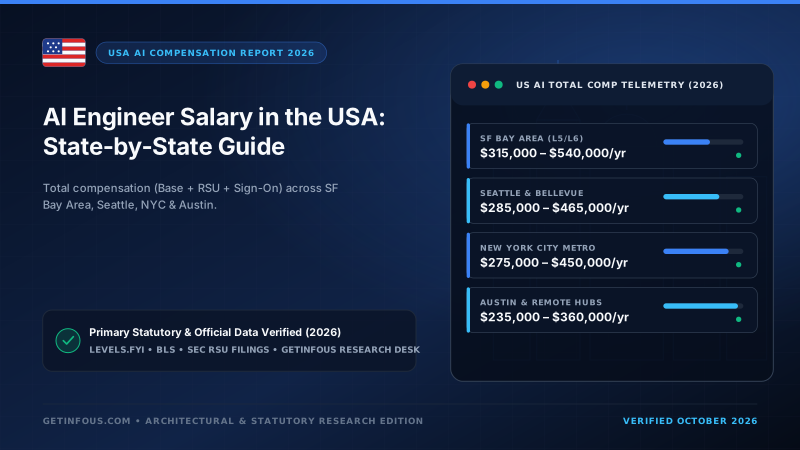
رواتب مهندسي الذكاء الاصطناعي في الولايات المتحدة: دليل التعويضات حسب الولاية (2026)
دليل شامل لرواتب مهندسي الذكاء الاصطناعي وتعلم الآلة والأسهم (RSU) وأفضل المراكز التقنية في الولايات المتحدة.
مقارنات احترافية لأكثر من 330 نموذج ذكاء اصطناعي، وتحليل تكلفة API، وبيانات رواتب المهندسين وأدلة الهجرة الموثقة.
Comparisons & Tools
Frontier Models Tracked
Avg. US Eng. Salary
Languages Supported
Live benchmark data
Independent composite scores across frontier models — re-ranked live as you switch metrics.
Model & Tool Directory
Filter by category — foundation models, code assistants, image generators, video engines, and autonomous workflows.
Showing 12 curated AI tools
A VS Code fork embedded with powerful frontier models that can write, refactor, and debug code across your entire repository with multi-file awareness.
Anthropic flagship intelligence model known for superior coding benchmarks, deep nuanced writing, and the interactive Artifacts workspace.
Omni-model integrating voice, vision, and text in real time. Powers advanced web browsing, Python code execution, and custom GPT assistants.
Replaces standard search engines with synthesized answers, cited sources, real-time follow-ups, and multi-file document analysis.
The gold standard in text-to-image AI, renowned for exceptional texture realism, coherent lighting, fine typographic generation, and web canvas editing.
Cutting-edge 12B parameter flow matching visual model rivaling Midjourney with state-of-the-art hand anatomy, prompt adherence, and open weights.
Benchmark Data
Compare context windows, coding benchmarks, reasoning scores, and API pricing across providers.
| Frontier Model | Context Window | SWE-bench (Code) | HumanEval | Pricing | Ideal Use Case |
|---|---|---|---|---|---|
Claude 3.7 Sonnet Top Score Anthropic | 200,000 tokens | 70.3% (Verified) | 93.7% | $3 / $15 per 1M tokens | Hybrid reasoning with thinking mode, complex multi-file code editing, and precise refactoring. |
GPT-4o OpenAI | 128,000 tokens | 38.8% | 90.2% | $2.50 / $10 per 1M tokens | Real-time voice, vision analysis, structured outputs, and general conversational intelligence. |
DeepSeek R1 DeepSeek | 128,000 tokens | 49.2% | 92.8% | $0.55 / $2.19 per 1M tokens | Deep chain-of-thought reasoning, mathematical proofs, and competitive programming. |
Gemini 2.0 Flash Google | 1,000,000 tokens | 24.1% | 84.1% | $0.10 / $0.40 per 1M tokens | Ultra-fast inference, massive document processing, and cost-efficient high-throughput workloads. |
Direct side-by-side benchmarks, API token pricing, context window, and latency comparisons
Methodology
Published so you can audit any number on this site — no black-box composite scores.
The intelligence index is a composite 0–100 score that blends ten independent evaluations: SWE-bench Verified for agentic coding, GPQA Diamond for graduate-level science, MMLU-Pro for broad knowledge, AIME for mathematical reasoning, HumanEval and LiveCodeBench for code generation, Terminal-Bench for shell tool use, Humanity’s Last Exam for frontier reasoning, long-context retrieval, and LMArena Elo for human preference. Each benchmark is normalised against the current frontier maximum before weighting, so a model cannot inflate its score with a single narrow strength.
Speed is measured as steady-state output tokens per second through each provider’s official API, sampled over twenty consecutive requests at a fixed 1,000-token prompt. We additionally publish time-to-first-token, because latency-sensitive chat interfaces care far more about the first token than about sustained throughput. Both figures are re-measured monthly since providers change serving infrastructure without notice.
Cost per task models a realistic agentic workload rather than a single round trip. We assume a 45,000-output-token task with a 10,000-token input context, apply each model’s published input and output prices per million tokens, and add reasoning-token overhead for models that expose a thinking mode. Batch and cached-input discounts are excluded so the figure reflects the default interactive path most teams actually pay.
Every figure is sourced from provider release specifications, official model cards, and independently reproduced benchmark runs. We do not republish third-party leaderboard numbers without re-running the evaluation ourselves, and each model page cites its primary source and last-verified date so readers can audit any claim.
Pricing and availability are checked weekly. Benchmark scores are re-run whenever a provider ships a point release that changes model behaviour, and at minimum once per month. The updated date shown on the leaderboard always reflects the most recent full re-evaluation, not the last cosmetic edit.
Salary breakdowns by US state, immigration pathways for engineers, and interview preparation.
دليل شامل لرواتب مهندسي الذكاء الاصطناعي وتعلم الآلة والأسهم (RSU) وأفضل المراكز التقنية في الولايات المتحدة.
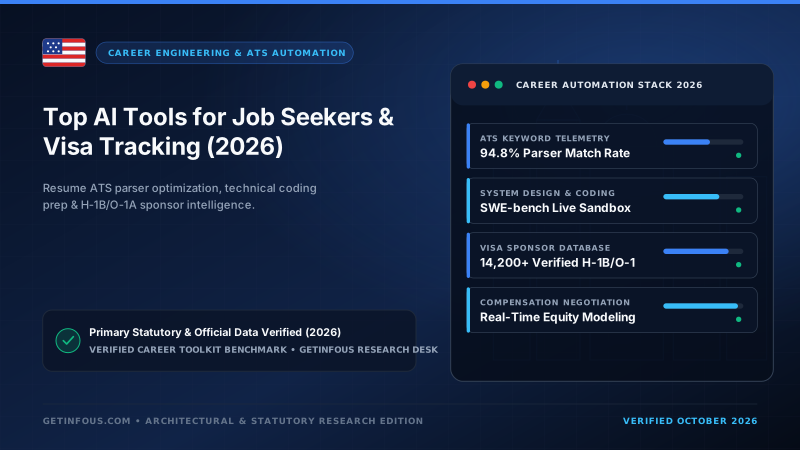
أدوات الذكاء الاصطناعي الأساسية لتحسين السيرة الذاتية لأنظمة ATS، والتدرب على المقابلات التقنية، وتتبع رعاية تأشيرات العمل.
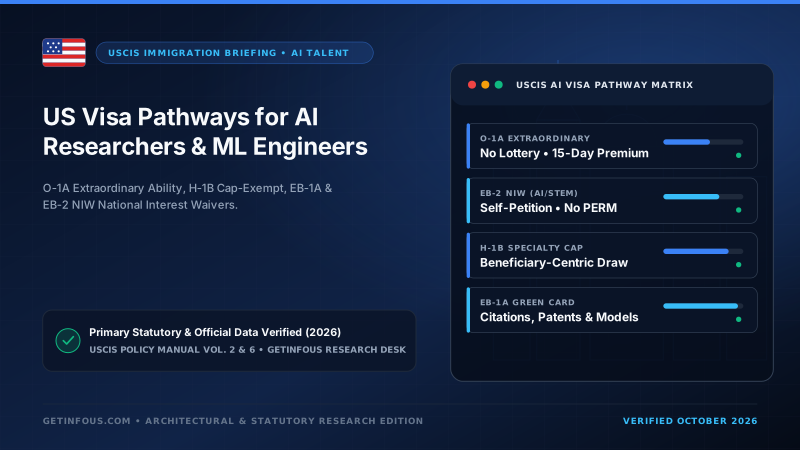
تحليل شامل لخيارات تأشيرات العمل الأمريكية لمواهب الذكاء الاصطناعي، بما في ذلك تأشيرة القدرات الاستثنائية O-1A وتأشيرة H-1B والبطاقة الخضراء EB-2 NIW.
Model releases, pricing changes, benchmark updates, and career data — one email per week.
No spam. Unsubscribe with one click.