Qwen Max vs Qwen-VL Max
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
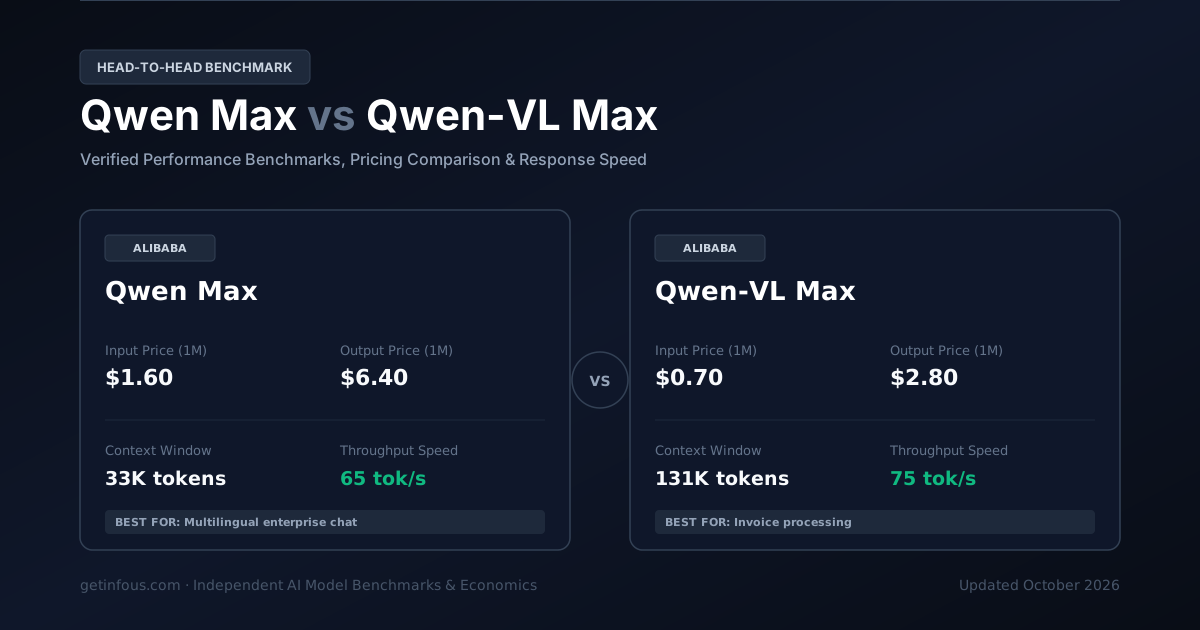
Qwen Max by Alibaba and Qwen-VL Max by Alibaba represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Qwen-VL Max holds a notable pricing advantage for token ingestion. On output generation, Qwen-VL Max is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, Qwen-VL Max provides an expanded memory horizon with 131K tokens. In latency-sensitive production environments, Qwen-VL Max leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Cambia y Compara Cualquier Modelo
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Qwen Max
Buque insignia inicialde Alibaba foundational insignia modelo de lenguaje desarrollado para empresarial razonamiento, multilingüe procesamiento, y estructurado agentes.
$1.60 / 1M
$6.40 / 1M
32.8K tokens
32.5%
Qwen-VL Max
Buque insignia de visiónlíder visión-idioma modelo fundacional specializing en alto-resolución visual razonamiento, OCR, gráfico parsing, y documento QA.
$0.70 / 1M
$2.80 / 1M
131.1K tokens
N/A
Diferencias Clave de un Vistazo
- Qwen-VL Max is 2.3x cheaper for API usage (input + output tokens combined).
- Qwen-VL Max has a larger context window (131K vs 33K tokens).
- Qwen-VL Max is faster at 75 tok/s vs 65 tok/s.
| Característica | Qwen Max | Qwen-VL Max |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 78 | 76 |
Provider | Alibaba | Alibaba |
Input Price Cost per million input tokens | $1.60 / 1M | $0.70 / 1M |
Output Price Cost per million output tokens | $6.40 / 1M | $2.80 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $1.07 / 1M | $0.47 / 1M |
Context Window Maximum input + output tokens | 32.8K tokens~49 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 8K | 8K |
Throughput Speed Tokens generated per second | 65 tok/s | 75 tok/s |
SWE-bench Verified Real-world software engineering | 32.5% | N/A |
GPQA Diamond Graduate-level reasoning | 48% | 46.5% |
Cached Input Price Prompt caching discount per 1M tokens | $0.16 / 1M | $0.07 / 1M |
¿Quién gana en cada área?
At-a-glance decision frameworkEvaluations ongoing
Puntuaciones de Benchmarks Verificadas
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
Latencia y Tiempo de Respuesta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulador Interactivo de Costos de Tokens
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Qwen Max · Strengths & Key Advantages
- excepcional chino y multilingüe comprensión un través de Asian idiomas
- alto instrucción-following reliability en empresarial API environments
- sólido estructurado JSON salida extracción
Considerations & Trade-offs
- Relatively compacto 32K ventana de contexto en comparación con newer millones-token releases
- Superseded por newer Qwen 2.5 y Qwen 3 Max variants para complejo codificación tareas
Qwen-VL Max · Strengths & Key Advantages
- de vanguardia OCR un través de scanned chino y English paperwork
- de grano fino visual fundamentación y UI coordinate extracción
- alto precisión en complejo charts, diagrams, y financial tables
Considerations & Trade-offs
- mayor latencia que pure texto Qwen endpoints
- ventana de contexto limitado un 131K tokens en comparación con texto 1M modelos
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Qwen Max | Qwen-VL Max |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.18 | $0.15 |
Output Tokens / Task Tokens generated per task | 18K | 16K |
Reasoning Tokens / Task Thinking tokens burned per task | 6K | 5K |
Especificaciones Técnicas
Architecture, release timeline, capabilities, and modalities.
| Característica | Qwen Max | Qwen-VL Max |
|---|---|---|
| Official API Model ID (SDK) | qwen-max-instruct | qwen-vl-max-instruct |
| API Protocol | Alibaba REST API (OpenAI-Compatible) | Alibaba REST API (OpenAI-Compatible) |
| Release Date | 2024-04 | 2024-04 |
| Knowledge Cutoff | September 2023 | December 2023 |
| Architecture | Dense Autoregressive Transformer with Multi-Head Attention | Multimodal Vision-Language Transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($1.6/1M in) across full 33K window | Flat rate ($0.7/1M in) across full 131K window |
| Prompt Cache Policy & TTL | Cached input at $0.16/1M tokens | Cached input at $0.07/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | API Prompt Engineering & RAG Distillation | API Prompt Engineering & RAG Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Alibaba Production Safety & Alignment Verified | Alibaba Production Safety & Alignment Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text | text, vision |
| Output Modalities | text | text |
Qwen Max vs Qwen-VL Max: Respuestas Rápidas (FAQ)
Which is more intelligent, Qwen Max or Qwen-VL Max?
Qwen Max is more intelligent. It scores 78 compared with 76 on the composite Intelligence Index.
Which model is faster?
Qwen-VL Max is faster, generating 75 tokens per second compared with 65 tokens per second.
Which model is cheaper to run?
Qwen-VL Max is cheaper at $0.47 per 1M tokens blended, compared with $1.07 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Qwen Max has lower latency, with a time to first token of 0.58s compared with 0.65s.
Which model has a larger context window?
Qwen-VL Max has a larger context window, supporting 131.1K tokens compared with 32.8K tokens.
Veredicto
Verdict & Model Selection Recommendation: Choose Qwen Max if your priority is Multilingual enterprise chat, customer support, and general NLP automation. Its performance in demanding tasks justifies its operational token cost. Choose Qwen-VL Max if your workflow prioritizes Invoice processing, complex document intelligence, visual inspection, and diagram QA. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Preguntas frecuentes
How does Qwen Max compare to Qwen-VL Max in API token pricing and cost per token?+
Qwen Max costs $1.60 per 1M input tokens and $6.40 per 1M output tokens, whereas Qwen-VL Max costs $0.70 input and $2.80 output. Overall, Qwen-VL Max is the more cost-effective model for high-volume API pipelines. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: Qwen Max or Qwen-VL Max?+
Qwen Max supports a context window of 33K tokens (~25k words), while Qwen-VL Max supports 131K tokens (~98k words). Therefore, Qwen-VL Max can process more textual data and document context in a single prompt.
Which AI model is better for software engineering and coding: Qwen Max or Qwen-VL Max?+
Qwen Max scores 32.5% on SWE-bench Verified, while Qwen-VL Max scores competitively for software generation. For complex autonomous debugging and agentic engineering, Qwen Max provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between Qwen Max and Qwen-VL Max?+
Qwen Max features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, Qwen-VL Max provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between Qwen Max and Qwen-VL Max?+
Qwen Max generates approximately 65 tokens per second, while Qwen-VL Max delivers 75 tokens per second. In latency-sensitive production environments, Qwen-VL Max provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Qwen Max and Qwen-VL Max to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Qwen-VL Max to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Qwen Max. This tiered routing pattern cuts overall API bills by up to 70%.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Qwen Max vs Reka Core: Benchmarks, Pricing & Speed ComparisonComparar
- Qwen-VL Max vs Qwen Plus: Benchmarks, Pricing & Speed ComparisonComparar
- Qwen-VL Max vs Reka Core: Benchmarks, Pricing & Speed ComparisonComparar
- QwQ Plus vs Qwen Max: Benchmarks, Pricing & Speed ComparisonComparar
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed ComparisonComparar
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed ComparisonComparar
Las puntuaciones de benchmarks, precios por token y límites de tasa evolucionan rápidamente. Verifique siempre las especificaciones actuales en la documentación oficial del proveedor.
Fuentes: GetInfoUs Independent AI Benchmarks & Official API Specs