GLM-5-Turbo vs MiniMax-M2.7-highspeed
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
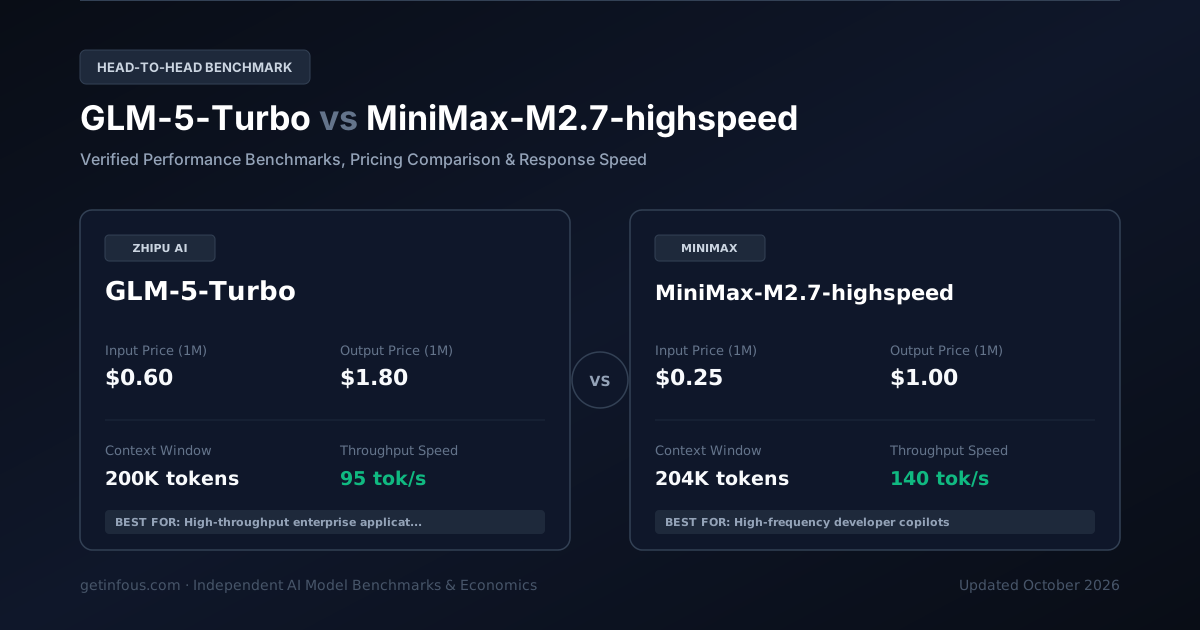
GLM-5-Turbo de Zhipu AI y MiniMax-M2.7-highspeed de MiniMax compiten directamente en el ecosistema actual de IA. GLM-5-Turbo ofrece una ventana de contexto de 200K tokens a $0.60/$1.80 por millón de tokens (entrada/salida), mientras que MiniMax-M2.7-highspeed ofrece 204K tokens de contexto a $0.25/$1.00 por millón de tokens. Analizamos sus benchmarks, latencia y costos reales.
Cambia y Compara Cualquier Modelo
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
GLM-5-Turbo
Inferencia UltrarrápidaGLM-5-Turbo de Zhipu AI es un modelo de IA diseñado para interacción en tiempo real, baja latencia y enrutamiento de alto volumen, con ventana de contexto de 200K, velocidad de 95 tokens/s, índice de inteligencia de 86/100 y tarifa de $0.6/
$0.60 / 1M
$1.80 / 1M
200K tokens
55%
MiniMax-M2.7-highspeed
Inferencia UltrarrápidaMiniMax-M2.7-highspeed de MiniMax es un modelo de IA diseñado para interacción en tiempo real, baja latencia y enrutamiento de alto volumen, con ventana de contexto de 204K, velocidad de 140 tokens/s, índice de inteligencia de 82/100 y tari
$0.25 / 1M
$1.00 / 1M
204K tokens
N/A
Diferencias Clave de un Vistazo
- MiniMax-M2.7-highspeed is 2.0x cheaper for API usage (input + output tokens combined).
- MiniMax-M2.7-highspeed has a larger context window (204K vs 200K tokens).
- MiniMax-M2.7-highspeed is faster at 140 tok/s vs 95 tok/s.
| Característica | GLM-5-Turbo | MiniMax-M2.7-highspeed |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 86 | 82 |
Provider | Zhipu AI | MiniMax |
Input Price Cost per million input tokens | $0.60 / 1M | $0.25 / 1M |
Output Price Cost per million output tokens | $1.80 / 1M | $1.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.34 / 1M | $0.17 / 1M |
Context Window Maximum input + output tokens | 200K tokens~300 A4 pages of text | 204K tokens~306 A4 pages of text |
Max Output Tokens Per single request | 16K | 8K |
Throughput Speed Tokens generated per second | 95 tok/s | 140 tok/s |
SWE-bench Verified Real-world software engineering | 55% | N/A |
GPQA Diamond Graduate-level reasoning | 65% | 63% |
Cached Input Price Prompt caching discount per 1M tokens | $0.06 / 1M | $0.03 / 1M |
¿Quién gana en cada área?
At-a-glance decision frameworkEvaluations ongoing
Puntuaciones de Benchmarks Verificadas
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
Latencia y Tiempo de Respuesta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulador Interactivo de Costos de Tokens
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
GLM-5-Turbo · Strengths & Key Advantages
- Ventana de contexto de 200K con hasta 16K tokens de salida máxima (SWE-bench Verified 55% · GPQA Diamond 65%)
- Rendimiento ágil de 95 tokens/segundo con latencia inicial (TTFT) de solo 420 ms
- Economía de API competitiva ($0.6/$1.8 por 1M de tokens) con soporte para caché de prompts y salidas JSON estructuradas
Considerations & Trade-offs
- Modelo propietario en la nube; no permite descargar los pesos para ejecución local sin conexión
- En demostraciones científicas extremas, los modelos de razonamiento pesado de gama alta ofrecen mayor profundidad
MiniMax-M2.7-highspeed · Strengths & Key Advantages
- Ventana de contexto de 204K con hasta 8K tokens de salida máxima (GPQA Diamond 63% · MMLU-Pro 78%)
- Rendimiento ágil de 140 tokens/segundo con latencia inicial (TTFT) de solo 290 ms
- Economía de API competitiva ($0.25/$1 por 1M de tokens) con soporte para caché de prompts y salidas JSON estructuradas
Considerations & Trade-offs
- Modelo propietario en la nube; no permite descargar los pesos para ejecución local sin conexión
- En demostraciones científicas extremas, los modelos de razonamiento pesado de gama alta ofrecen mayor profundidad
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | GLM-5-Turbo | MiniMax-M2.7-highspeed |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.16 | $0.06 |
Output Tokens / Task Tokens generated per task | 22K | 15K |
Reasoning Tokens / Task Thinking tokens burned per task | 7K | 2K |
Especificaciones Técnicas
Architecture, release timeline, capabilities, and modalities.
| Característica | GLM-5-Turbo | MiniMax-M2.7-highspeed |
|---|---|---|
| Official API Model ID (SDK) | glm-5-turbo | minimax-m2-7-highspeed |
| API Protocol | Zhipu AI REST API (OpenAI-Compatible) | MiniMax REST API (OpenAI-Compatible) |
| Release Date | 2026-03 | 2026-03 |
| Knowledge Cutoff | January 2026 | January 2026 |
| Architecture | Hosted Accelerated Frontier Transformer | High-Throughput Hosted Cloud Accelerator |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($0.6/1M in) across full 200K window | Flat rate ($0.25/1M in) across full 204K window |
| Prompt Cache Policy & TTL | Cached input at $0.06/1M tokens | Cached input at $0.025/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | API Prompt Engineering & RAG Distillation | API Prompt Engineering & RAG Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Zhipu AI Production Safety & Alignment Verified | MiniMax Production Safety & Alignment Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text | text |
| Output Modalities | text | text |
GLM-5-Turbo vs MiniMax-M2.7-highspeed: Respuestas Rápidas (FAQ)
Which is more intelligent, GLM-5-Turbo or MiniMax-M2.7-highspeed?
GLM-5-Turbo is more intelligent. It scores 86 compared with 82 on the composite Intelligence Index.
Which model is faster?
MiniMax-M2.7-highspeed is faster, generating 140 tokens per second compared with 95 tokens per second.
Which model is cheaper to run?
MiniMax-M2.7-highspeed is cheaper at $0.17 per 1M tokens blended, compared with $0.34 (7:2:1 cache:input:output ratio).
Which model has lower latency?
MiniMax-M2.7-highspeed has lower latency, with a time to first token of 0.29s compared with 0.42s.
Which model has a larger context window?
MiniMax-M2.7-highspeed has a larger context window, supporting 204K tokens compared with 200K tokens.
Veredicto
Tanto GLM-5-Turbo (Ideal para interacción en tiempo real, baja latencia y enrutamiento de alto volumen, sistemas RAG empresariales y automatización mediante API.) como MiniMax-M2.7-highspeed (Ideal para interacción en tiempo real, baja latencia y enrutamiento de alto volumen, sistemas RAG empresariales y automatización mediante API.) destacan en producción: GLM-5-Turbo lidera en inteligencia general y programación, MiniMax-M2.7-highspeed ofrece mayor velocidad de generación de tokens y MiniMax-M2.7-highspeed resulta más rentable para cargas de trabajo API de alto volumen.
Preguntas frecuentes
¿Cuál es mejor para programación y razonamiento, GLM-5-Turbo o MiniMax-M2.7-highspeed?+
En las pruebas de inteligencia compuesta y resolución de código, GLM-5-Turbo obtiene la ventaja. Puedes revisar la tabla SWE-bench y GPQA arriba para comparar cada métrica.
¿Cuánto cuesta la API de GLM-5-Turbo frente a MiniMax-M2.7-highspeed?+
GLM-5-Turbo cuesta $0.60 / $1.80 por millón de tokens de entrada/salida, mientras que MiniMax-M2.7-highspeed cuesta $0.25 / $1.00. En costo combinado, MiniMax-M2.7-highspeed es la opción más económica.
¿Qué modelo tiene mayor ventana de contexto y menor latencia?+
GLM-5-Turbo cuenta con 200K tokens de contexto frente a 204K tokens de MiniMax-M2.7-highspeed. En velocidad de inferencia, MiniMax-M2.7-highspeed ofrece un rendimiento superior.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- GLM-5-Turbo vs. GLM-4.5-Flash: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- GLM-5V-Turbo vs. GLM-5-Turbo: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- MiniMax-M2.7-highspeed vs. MiniMax-M2.5-highspeed: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- Aion-3.0 vs. Aion-Mini: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- Aion-3.0 vs. Gemini 3.6 Flash: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- Aion-Mini vs. Laguna XS 2.1: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
Las puntuaciones de benchmarks, precios por token y límites de tasa evolucionan rápidamente. Verifique siempre las especificaciones actuales en la documentación oficial del proveedor.
Fuentes: Documentación oficial de API de Zhipu AI y MiniMax, tarjetas de sistema y benchmarks independientes (2026).