Claude Opus 4 vs Claude Sonnet 4
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
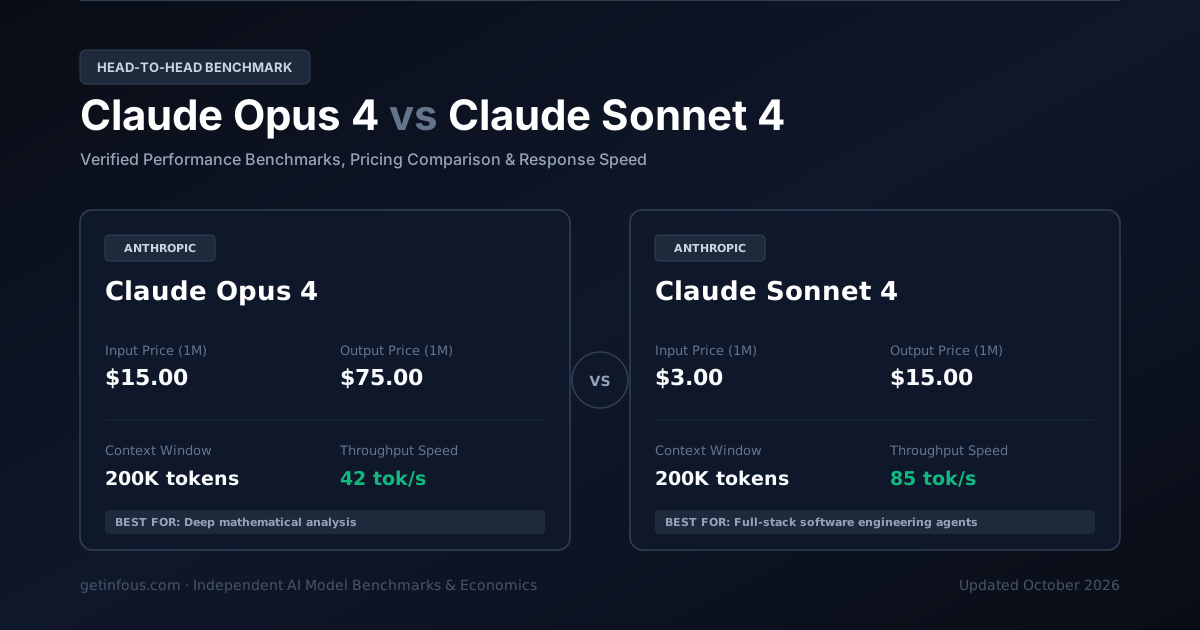
Claude Opus 4 by Anthropic and Claude Sonnet 4 by Anthropic represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Claude Sonnet 4 holds a notable pricing advantage for token ingestion. On output generation, Claude Sonnet 4 is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, both models provide an identical memory horizon with 200K tokens. In latency-sensitive production environments, Claude Sonnet 4 leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Cambia e Confronta Qualsiasi Modello
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Claude Opus 4
Modello di Ragionamento ProfondoClaude Opus 4 di Anthropic è un modello di intelligenza artificiale con finestra di contesto da 200K token e tariffazione API di $15/1M token in input e $75/1M in output, ideale per coding, ragionamento e automazione aziendale.
$15.00 / 1M
$75.00 / 1M
200K tokens
72.5%
Claude Sonnet 4
Modello di Ragionamento ProfondoClaude Sonnet 4 di Anthropic è un modello di intelligenza artificiale con finestra di contesto da 200K token e tariffazione API di $3/1M token in input e $15/1M in output, ideale per coding, ragionamento e automazione aziendale.
$3.00 / 1M
$15.00 / 1M
200K tokens
72.7%
Differenze Chiave a Colpo d’Occhio
- Claude Sonnet 4 is 5.0x cheaper for API usage (input + output tokens combined).
- Claude Sonnet 4 is faster at 85 tok/s vs 42 tok/s.
- Claude Sonnet 4 leads on SWE-bench coding (72.7% vs 72.5%).
| Feature | Claude Opus 4 | Claude Sonnet 4 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 61 | 58 |
Provider | Anthropic | Anthropic |
Input Price Cost per million input tokens | $15.00 / 1M | $3.00 / 1M |
Output Price Cost per million output tokens | $75.00 / 1M | $15.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $11.55 / 1M | $2.31 / 1M |
Context Window Maximum input + output tokens | 200K tokens~300 A4 pages of text | 200K tokens~300 A4 pages of text |
Max Output Tokens Per single request | 32K | 64K |
Throughput Speed Tokens generated per second | 42 tok/s | 85 tok/s |
SWE-bench Verified Real-world software engineering | 72.5% | 72.7% |
GPQA Diamond Graduate-level reasoning | 73.8% | 71.2% |
Cached Input Price Prompt caching discount per 1M tokens | $1.50 / 1M | $0.30 / 1M |
Chi vince in ogni categoria?
At-a-glance decision frameworkPunteggi Benchmark Verificati
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Tokens emitted per second during active generation streaming.
Latenza e Tempo di Risposta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulatore Interattivo dei Costi Token
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Claude Opus 4 · Strengths & Key Advantages
- Architettura Dense Frontier Reasoning Transformer avanzata di Anthropic con supporto fino a 200K token di contesto
- Ottimo rapporto qualità-prezzo ($15/1M input, $75/1M output) e bassa latenza
- Elevate prestazioni nei benchmark di programmazione, logica e comprensione multilingue
Considerations & Trade-offs
- L'utilizzo intensivo di contesti molto ampi richiede un attento monitoraggio dei costi dei token
- Per casi d'uso verticali complessi è consigliabile un prompt engineering mirato
Claude Sonnet 4 · Strengths & Key Advantages
- Architettura Hybrid Multimodal Reasoning Transformer avanzata di Anthropic con supporto fino a 200K token di contesto
- Ottimo rapporto qualità-prezzo ($3/1M input, $15/1M output) e bassa latenza
- Elevate prestazioni nei benchmark di programmazione, logica e comprensione multilingue
Considerations & Trade-offs
- L'utilizzo intensivo di contesti molto ampi richiede un attento monitoraggio dei costi dei token
- Per casi d'uso verticali complessi è consigliabile un prompt engineering mirato
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Claude Opus 4 | Claude Sonnet 4 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $16.46 | $3.29 |
Output Tokens / Task Tokens generated per task | 72K | 72K |
Reasoning Tokens / Task Thinking tokens burned per task | 37K | 37K |
Specifiche Tecniche
Architecture, release timeline, capabilities, and modalities.
| Feature | Claude Opus 4 | Claude Sonnet 4 |
|---|---|---|
| Official API Model ID (SDK) | claude-opus-4-20250501 | claude-sonnet-4-20250501 |
| API Protocol | Anthropic Messages API + AWS Bedrock + Vertex AI | Anthropic Messages API + AWS Bedrock + Vertex AI |
| Release Date | 2025-05 | 2025-05 |
| Knowledge Cutoff | March 2025 | March 2025 |
| Architecture | Dense Frontier Reasoning Transformer | Hybrid Multimodal Reasoning Transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 4,000 – 10,000 RPM (Tier 4 + Priority Tier) · 800,000 – 2,000,000 TPM | 4,000 – 10,000 RPM (Tier 4 + Priority Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens |
| Prompt Cache Policy & TTL | $1.5/1M cached read (90% off); 5-min default & 1-hour extended TTL | $0.3/1M cached read (90% off); 5-min default & 1-hour extended TTL |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Native Web Search Citations + Code Execution Tool + MCP Connectors | Native Web Search Citations + Code Execution Tool + MCP Connectors |
| Official Fine-Tuning Support | Custom Model Tuning via Amazon Bedrock & Prompt Distillation | Custom Model Tuning via Amazon Bedrock & Prompt Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Anthropic RSP ASL-2 / ASL-3 Constitutional Safety Evaluated | Anthropic RSP ASL-2 / ASL-3 Constitutional Safety Evaluated |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Claude Opus 4 vs Claude Sonnet 4: Risposte Rapide (FAQ)
Which is more intelligent, Claude Opus 4 or Claude Sonnet 4?
Claude Opus 4 is more intelligent. It scores 61 compared with 58 on the composite Intelligence Index.
Which model is faster?
Claude Sonnet 4 is faster, generating 85 tokens per second compared with 42 tokens per second.
Which model is cheaper to run?
Claude Sonnet 4 is cheaper at $2.31 per 1M tokens blended, compared with $11.55 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Claude Sonnet 4 has lower latency, with a time to first token of 0.52s compared with 1.80s.
Verdetto
Verdict & Model Selection Recommendation: Choose Claude Opus 4 if your priority is Deep mathematical analysis, mission-critical autonomous planning, and enterprise code audits. Its performance in demanding tasks justifies its operational token cost. Choose Claude Sonnet 4 if your workflow prioritizes Full-stack software engineering agents, CI/CD pipeline automation, and enterprise production applications. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Domande Frequenti (FAQ)
How does Claude Opus 4 compare to Claude Sonnet 4 in API token pricing and cost per token?+
Claude Opus 4 costs $15.00 per 1M input tokens and $75.00 per 1M output tokens, whereas Claude Sonnet 4 costs $3.00 input and $15.00 output. Overall, Claude Sonnet 4 is the more cost-effective model for high-volume API pipelines. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: Claude Opus 4 or Claude Sonnet 4?+
Both Claude Opus 4 and Claude Sonnet 4 offer an identical context window of 200K tokens (~150k words). Both architectures provide equal capacity for large document ingestion, multi-file codebases, and extended multi-turn conversation histories.
Which AI model is better for software engineering and coding: Claude Opus 4 or Claude Sonnet 4?+
Claude Opus 4 scores 72.5% on SWE-bench Verified while Claude Sonnet 4 scores 72.7%. For autonomous software engineering and multi-file debugging, Claude Sonnet 4 holds the verified benchmark lead.
What is the difference in reasoning capability and extended thinking between Claude Opus 4 and Claude Sonnet 4?+
Claude Opus 4 features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, Claude Sonnet 4 provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between Claude Opus 4 and Claude Sonnet 4?+
Claude Opus 4 generates approximately 42 tokens per second, while Claude Sonnet 4 delivers 85 tokens per second. In latency-sensitive production environments, Claude Sonnet 4 provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Claude Opus 4 and Claude Sonnet 4 to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Claude Sonnet 4 to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Claude Opus 4. This tiered routing pattern cuts overall API bills by up to 70%.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Claude Opus 4.1 vs Claude Opus 4: Benchmarks, Pricing & Speed ComparisonConfronta
- Claude Opus 4 vs Gemini 2.5 Flash-Lite: Benchmarks, Pricing & Speed ComparisonConfronta
- Claude Sonnet 4 vs Claude 3.7 Sonnet: Benchmarks, Pricing & Speed ComparisonConfronta
- Claude Sonnet 4 vs o1-pro: Benchmarks, Pricing & Speed ComparisonConfronta
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed ComparisonConfronta
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed ComparisonConfronta
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Fonti ufficiali: GetInfoUs Independent AI Benchmarks & Official API Specs