o3-pro vs GPT-6 Astra
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
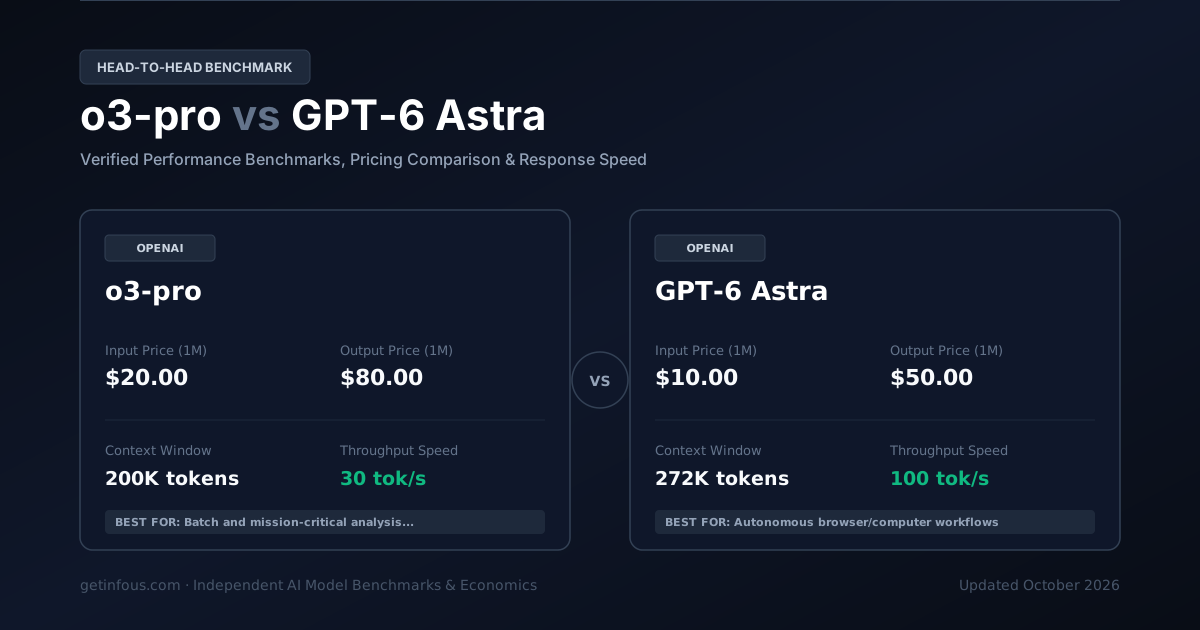
يُعد o3-pro من OpenAI وGPT-6 Astra من OpenAI من أبرز نماذج الذكاء الاصطناعي. يوفر o3-pro نافذة سياق بحجم 200K رمز بسعر $20.00/$80.00 لكل مليون رمز، بينما يوفر GPT-6 Astra سياقًا بحجم 272K رمز بسعر $10.00/$50.00 لكل مليون رمز. نستعرض أدناه مقارنة شاملة للأداء والسرعة والتكلفة.
بدّل وقارن بين أي نموذجين
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
o3-pro
محرك استدلال منطقي عميقنموذج o3-pro من OpenAI مصمم خصيصاً لـالاستدلال المنطقي العميق والرياضيات المتقدمة والبحث العلمي متعدد الخطوات، حيث يوفر نافذة سياق بسعة 200K وسرعة 30 رمز/ثانية ومؤشر ذكاء 58/100 (بتكلفة $20/$80 لكل مليون رمز).
$20.00 / 1M
$80.00 / 1M
200K tokens
71.5%
GPT-6 Astra
نموذج الصوت والكلام الطبيعينموذج GPT-6 Astra من OpenAI مصمم خصيصاً لـتوليد الكلام البشري الطبيعي ومعالجة الصوت الفورية والنسخ الصوتي الدقيق، حيث يوفر نافذة سياق بسعة 272K وسرعة 100 رمز/ثانية ومؤشر ذكاء 96/100 (بتكلفة $10/$50 لكل مليون رمز).
$10.00 / 1M
$50.00 / 1M
272K tokens
82.4%
أهم الفروقات في لمحة
- GPT-6 Astra is 1.8x cheaper for API usage (input + output tokens combined).
- GPT-6 Astra has a larger context window (272K vs 200K tokens).
- GPT-6 Astra is faster at 100 tok/s vs 30 tok/s.
- GPT-6 Astra leads on SWE-bench coding (82.4% vs 71.5%).
| Feature | o3-pro | GPT-6 Astra |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 58 | 96 |
Provider | OpenAI | OpenAI |
Input Price Cost per million input tokens | $20.00 / 1M | $10.00 / 1M |
Output Price Cost per million output tokens | $80.00 / 1M | $50.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $15.50 / 1M | $7.70 / 1M |
Context Window Maximum input + output tokens | 200K tokens~300 A4 pages of text | 272K tokens~408 A4 pages of text |
Max Output Tokens Per single request | 100K | 128K |
Throughput Speed Tokens generated per second | 30 tok/s | 100 tok/s |
SWE-bench Verified Real-world software engineering | 71.5% | 82.4% |
GPQA Diamond Graduate-level reasoning | 79.5% | 80.9% |
Cached Input Price Prompt caching discount per 1M tokens | $5.00 / 1M | $1.00 / 1M |
من يتفوق في كل مجال؟
At-a-glance decision frameworkنتائج الاختبارات المعيارية الموثقة
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
زمن الاستجابة والسرعة
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
محاكي تكلفة الرموز التفاعلي
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
o3-pro · Strengths & Key Advantages
- نافذة سياق بسعة 200K وحد أقصى للمخرجات يصل إلى 100K رمز (SWE-bench Verified 71.5% · GPQA Diamond 79.5%)
- سرعة توليد عالية تبلغ 30 رمز/ثانية مع زمن استجابة لأول رمز (TTFT) قدره 5200 مللي ثانية
- تسعير API تنافسي (بتكلفة $20/$80 لكل مليون رمز) مع دعم التخزين المؤقت للأوامر والمخرجات المهيكلة بصيغة JSON
Considerations & Trade-offs
- نموذج سحابي مغلق الأوزان لا يدعم تنزيل الأوزان للتشغيل المحلي المعزول عن الإنترنت
- في حالات الاستخدام الكثيف، يُنصح بتفعيل التخزين المؤقت (Prompt Caching) وBatch API لترشيد النفقات
GPT-6 Astra · Strengths & Key Advantages
- نافذة سياق بسعة 272K وحد أقصى للمخرجات يصل إلى 128K رمز (SWE-bench Verified 82.4% · GPQA Diamond 80.9%)
- سرعة توليد عالية تبلغ 100 رمز/ثانية مع زمن استجابة لأول رمز (TTFT) قدره 950 مللي ثانية
- تسعير API تنافسي (بتكلفة $10/$50 لكل مليون رمز) مع دعم التخزين المؤقت للأوامر والمخرجات المهيكلة بصيغة JSON
Considerations & Trade-offs
- نموذج سحابي مغلق الأوزان لا يدعم تنزيل الأوزان للتشغيل المحلي المعزول عن الإنترنت
- في حالات الاستخدام الكثيف، يُنصح بتفعيل التخزين المؤقت (Prompt Caching) وBatch API لترشيد النفقات
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | o3-pro | GPT-6 Astra |
|---|---|---|
Cost per Task Estimated USD to finish one task | $11.68 | $2.15 |
Output Tokens / Task Tokens generated per task | 58K | 58K |
Reasoning Tokens / Task Thinking tokens burned per task | 38K | 32K |
المواصفات التقنية
Architecture, release timeline, capabilities, and modalities.
| Feature | o3-pro | GPT-6 Astra |
|---|---|---|
| Official API Model ID (SDK) | o3-pro | gpt-6-astra |
| API Protocol | OpenAI Responses API & Chat Completions v1 | OpenAI Responses API & Chat Completions v1 |
| Release Date | 2025-06 | 2026-09 |
| Knowledge Cutoff | June 2024 | June 2026 |
| Architecture | High-effort reasoning transformer | Omni-Adaptive Autoregressive with Dynamic CoT |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($20/1M in) across full 200K window | Flat rate ($10/1M in) across full 272K window |
| Prompt Cache Policy & TTL | Automatic prefix caching at $5/1M (no extra cache-write fee) | Automatic prefix caching at $1/1M (no extra cache-write fee) |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Native Web Search tool + Hosted Code Interpreter & File Search RAG | Native Web Search tool + Hosted Code Interpreter & File Search RAG |
| Official Fine-Tuning Support | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) · Audio (~25–32 tokens/sec) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | OpenAI Preparedness Framework Audited & System Card Published | OpenAI Preparedness Framework Audited & System Card Published |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision, audio |
| Output Modalities | text | text, audio |
o3-pro vs GPT-6 Astra: إجابات سريعة (FAQ)
Which is more intelligent, o3-pro or GPT-6 Astra?
GPT-6 Astra is more intelligent. It scores 96 compared with 58 on the composite Intelligence Index.
Which model is faster?
GPT-6 Astra is faster, generating 100 tokens per second compared with 30 tokens per second.
Which model is cheaper to run?
GPT-6 Astra is cheaper at $7.70 per 1M tokens blended, compared with $15.50 (7:2:1 cache:input:output ratio).
Which model has lower latency?
GPT-6 Astra has lower latency, with a time to first token of 0.95s compared with 5.20s.
Which model has a larger context window?
GPT-6 Astra has a larger context window, supporting 272K tokens compared with 200K tokens.
الحكم النهائي
يتميز كل من o3-pro (مثالي لـالاستدلال المنطقي العميق والرياضيات المتقدمة والبحث العلمي متعدد الخطوات وأنظمة RAG المؤسسية وربط واجهات البرمجة (API) القابلة للتوسع.) وGPT-6 Astra (مثالي لـتوليد الكلام البشري الطبيعي ومعالجة الصوت الفورية والنسخ الصوتي الدقيق وأنظمة RAG المؤسسية وربط واجهات البرمجة (API) القابلة للتوسع.) بنقاط قوة واضحة؛ حيث يتفوق GPT-6 Astra في اختبارات الذكاء والبرمجة، ويقدم GPT-6 Astra سرعة توليد أعلى، بينما يُعد GPT-6 Astra الخيار الأكثر توفيراً للتشغيل عبر API.
الأسئلة الشائعة (FAQ)
أيهما أفضل للبرمجة والاستدلال، o3-pro أم GPT-6 Astra؟+
يتصدر GPT-6 Astra في مؤشر الذكاء المركب واختبارات البرمجة. يمكنك مراجعة نتائج SWE-bench وGPQA أعلاه لمقارنة دقيقة.
ما الفرق في تكلفة API بين o3-pro وGPT-6 Astra؟+
يبلغ سعر o3-pro نحو $20.00 / $80.00 لكل مليون رمز (إدخال/إخراج)، بينما يبلغ سعر GPT-6 Astra نحو $10.00 / $50.00. ومن حيث التكلفة الإجمالية يُعد GPT-6 Astra الأرخص.
أي نموذج يوفر نافذة سياق أكبر وسرعة أعلى؟+
يدعم o3-pro سياقًا بحجم 200K رمز مقابل 272K رمز لنموذج GPT-6 Astra، بينما يتفوق GPT-6 Astra في سرعة تدفق الرموز.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Claude Fable 5.1 ضد GPT-6 Astra: مقارنة الاختبارات وأسعار API والسرعة (2026)مقارنة
- Claude Mythos 5.1 ضد GPT-6 Astra: مقارنة الاختبارات وأسعار API والسرعة (2026)مقارنة
- Command A Plus ضد GPT-6 Astra: مقارنة الاختبارات وأسعار API والسرعة (2026)مقارنة
- DeepSeek V4 Pro ضد GPT-6 Astra: مقارنة الاختبارات وأسعار API والسرعة (2026)مقارنة
- GPT-5 Chat ضد o3-pro: مقارنة الاختبارات وأسعار API والسرعة (2026)مقارنة
- GPT-6.1 Sol ضد GPT-6 Astra: مقارنة الاختبارات وأسعار API والسرعة (2026)مقارنة
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
المصادر الرسمية: وثائق API الرسمية من OpenAI وOpenAI وتقييمات الاختبارات القياسية المستقلة (2026).