Qwen3.5 27B vs Qwen3-Next 80B-A3B Instruct
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
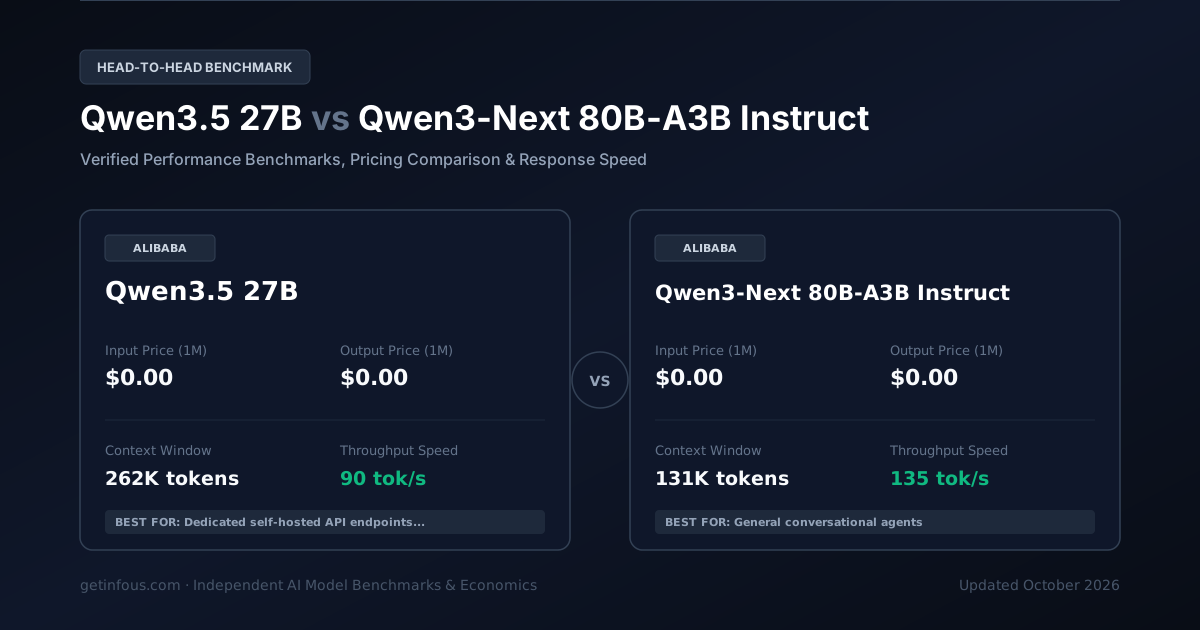
Qwen3.5 27B di Alibaba e Qwen3-Next 80B-A3B Instruct di Alibaba sono due modelli di IA di riferimento. Qwen3.5 27B offre una finestra di contesto di 262.1K token a $0.00/$0.00 per milione di token, mentre Qwen3-Next 80B-A3B Instruct mette a disposizione 131.1K token di contesto a $0.00/$0.00 per milione di token. Di seguito analizziamo benchmark, latenza e costi.
Cambia e Confronta Qualsiasi Modello
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Qwen3.5 27B
Modello Base a Pesi ApertiQwen3.5 27B di Alibaba è un modello di IA progettato per il self-hosting su infrastruttura privata, il fine-tuning e la piena sovranità dei dati, con finestra di contesto da 262K, velocità di 90 token/s, indice di intelligenza di 75/100 e t
$0.00 / 1M
$0.00 / 1M
262.1K tokens
N/A
Qwen3-Next 80B-A3B Instruct
Modello Base a Pesi ApertiQwen3-Next 80B-A3B Instruct di Alibaba è un modello di IA progettato per il self-hosting su infrastruttura privata, il fine-tuning e la piena sovranità dei dati, con finestra di contesto da 131K, velocità di 135 token/s, indice di intellige
$0.00 / 1M
$0.00 / 1M
131.1K tokens
N/A
Differenze Chiave a Colpo d’Occhio
- Both models cost the same under this workload — choose on capability, not price.
- Qwen3.5 27B has a larger context window (262K vs 131K tokens).
- Qwen3-Next 80B-A3B Instruct is faster at 135 tok/s vs 90 tok/s.
| Feature | Qwen3.5 27B | Qwen3-Next 80B-A3B Instruct |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 75 | 78 |
Provider | Alibaba | Alibaba |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 262.1K tokens~393 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 8K | 8K |
Throughput Speed Tokens generated per second | 90 tok/s | 135 tok/s |
SWE-bench Verified Real-world software engineering | N/A | N/A |
GPQA Diamond Graduate-level reasoning | 56.5% | 60% |
Chi vince in ogni categoria?
At-a-glance decision frameworkEvaluations ongoing
Punteggi Benchmark Verificati
Official evaluation metrics verified by independent third-party research labs.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
Latenza e Tempo di Risposta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulatore Interattivo dei Costi Token
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Qwen3.5 27B · Strengths & Key Advantages
- Finestra di contesto da 262K con capacità massima di output fino a 8K token (GPQA Diamond 56.5% · MMLU-Pro 74%)
- Throughput elevato di 90 token/secondo con latenza al primo token (TTFT) di soli 410 ms
- Pesi aperti (27B) pronti per il self-hosting locale o su cloud privato tramite vLLM, SGLang o Ollama
Considerations & Trade-offs
- Richiede server GPU dedicati con sufficiente memoria VRAM per l’esecuzione locale a piena precisione
- Nelle dimostrazioni scientifiche più estreme, i modelli di ragionamento pesante dedicati offrono maggiore profondità
Qwen3-Next 80B-A3B Instruct · Strengths & Key Advantages
- Finestra di contesto da 131K con capacità massima di output fino a 8K token (GPQA Diamond 60% · MMLU-Pro 78%)
- Throughput elevato di 135 token/secondo con latenza al primo token (TTFT) di soli 310 ms
- Pesi aperti (80B total (3B MoE)) pronti per il self-hosting locale o su cloud privato tramite vLLM, SGLang o Ollama
Considerations & Trade-offs
- Richiede server GPU dedicati con sufficiente memoria VRAM per l’esecuzione locale a piena precisione
- Nelle dimostrazioni scientifiche più estreme, i modelli di ragionamento pesante dedicati offrono maggiore profondità
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Qwen3.5 27B | Qwen3-Next 80B-A3B Instruct |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 13K | 15K |
Reasoning Tokens / Task Thinking tokens burned per task | 0K | 0K |
Specifiche Tecniche
Architecture, release timeline, capabilities, and modalities.
| Feature | Qwen3.5 27B | Qwen3-Next 80B-A3B Instruct |
|---|---|---|
| Official API Model ID (SDK) | qwen3-5-27b-instruct | qwen3-next-80b-a3b-instruct-instruct |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-02 | 2025-09 |
| Knowledge Cutoff | December 2025 | August 2025 |
| Architecture | Dense Multimodal Autoregressive Transformer | Standard Instruction-Tuned Sparse Mixture-of-Experts |
| Parameters | 27B | 80B total (3B active MoE) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 17 GB VRAM (4-bit Quantized) · 58 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 50 GB VRAM (4-bit Quantized) · 172 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision | text |
| Output Modalities | text | text |
Qwen3.5 27B vs Qwen3-Next 80B-A3B Instruct: Risposte Rapide (FAQ)
Which is more intelligent, Qwen3.5 27B or Qwen3-Next 80B-A3B Instruct?
Qwen3-Next 80B-A3B Instruct is more intelligent. It scores 78 compared with 75 on the composite Intelligence Index.
Which model is faster?
Qwen3-Next 80B-A3B Instruct is faster, generating 135 tokens per second compared with 90 tokens per second.
Which model has lower latency?
Qwen3-Next 80B-A3B Instruct has lower latency, with a time to first token of 0.31s compared with 0.41s.
Which model has a larger context window?
Qwen3.5 27B has a larger context window, supporting 262.1K tokens compared with 131.1K tokens.
Verdetto
Sia Qwen3.5 27B (Ideale per il self-hosting su infrastruttura privata, il fine-tuning e la piena sovranità dei dati, sistemi RAG aziendali e integrazioni API scalabili.) sia Qwen3-Next 80B-A3B Instruct (Ideale per il self-hosting su infrastruttura privata, il fine-tuning e la piena sovranità dei dati, sistemi RAG aziendali e integrazioni API scalabili.) eccellono in produzione: Qwen3-Next 80B-A3B Instruct guida nei benchmark di ragionamento e programmazione, Qwen3-Next 80B-A3B Instruct garantisce una generazione più rapida e Qwen3.5 27B offre il miglior rapporto qualità-prezzo per carichi API elevati.
Domande Frequenti (FAQ)
Quale modello è migliore per coding e ragionamento, Qwen3.5 27B o Qwen3-Next 80B-A3B Instruct?+
Nell’indice di intelligenza composito e nei benchmark di programmazione prevale Qwen3-Next 80B-A3B Instruct. Consulta i punteggi SWE-bench e GPQA qui sopra per tutti i dettagli.
Qual è la differenza di prezzo API tra Qwen3.5 27B e Qwen3-Next 80B-A3B Instruct?+
Qwen3.5 27B costa $0.00 / $0.00 per milione di token di input/output, mentre Qwen3-Next 80B-A3B Instruct costa $0.00 / $0.00. Nel costo combinato, Qwen3.5 27B risulta più economico.
Quale modello ha la finestra di contesto più ampia e la velocità maggiore?+
Qwen3.5 27B supporta 262.1K token di contesto contro 131.1K token di Qwen3-Next 80B-A3B Instruct, mentre Qwen3-Next 80B-A3B Instruct offre una velocità di generazione superiore.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Qwen3.5 27B vs DeepSeek Chat: Confronto Benchmark, Prezzi API e Velocità (2026)Confronta
- Qwen3.5 35B-A3B vs Qwen3.5 27B: Confronto Benchmark, Prezzi API e Velocità (2026)Confronta
- Qwen3-Next 80B-A3B Instruct vs Llama 4 Scout: Confronto Benchmark, Prezzi API e Velocità (2026)Confronta
- Qwen3-Next 80B-A3B Instruct vs Qwen 2.5 72B: Confronto Benchmark, Prezzi API e Velocità (2026)Confronta
- Aion-3.0 vs Aion-Mini: Confronto Benchmark, Prezzi API e Velocità (2026)Confronta
- Aion-3.0 vs Gemini 3.6 Flash: Confronto Benchmark, Prezzi API e Velocità (2026)Confronta
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Fonti ufficiali: Documentazione API ufficiale di Alibaba e Alibaba, schede di sistema e benchmark indipendenti (2026).