Grok 4.3 vs Grok Build 0.1
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
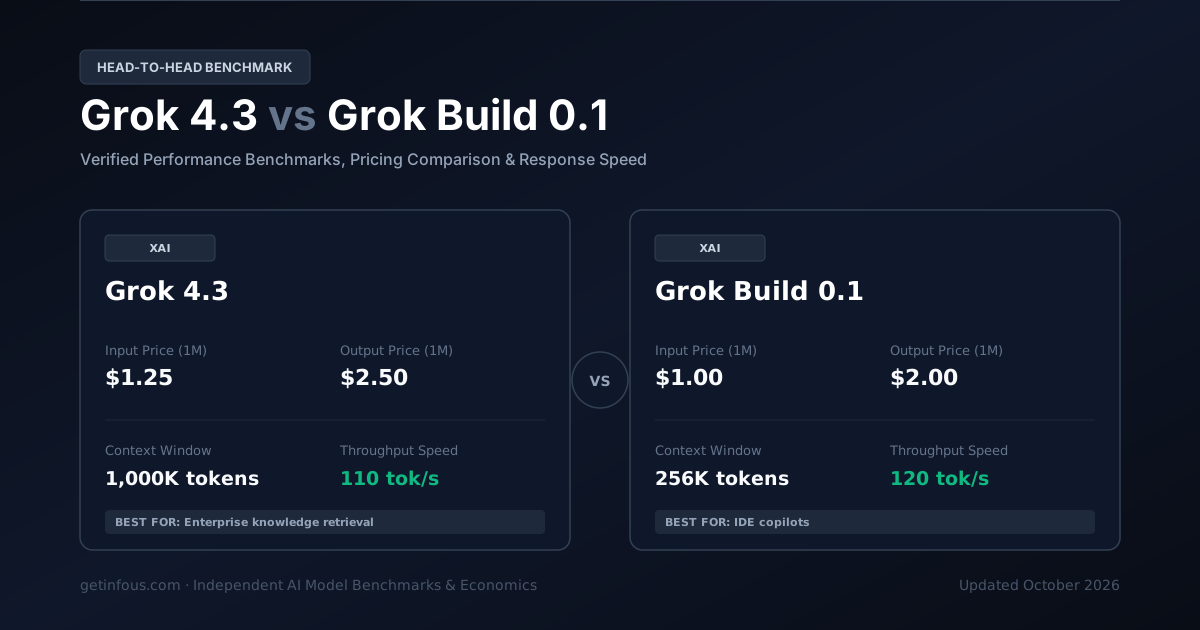
Grok 4.3 by xAI and Grok Build 0.1 by xAI represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Grok Build 0.1 holds a notable pricing advantage for token ingestion. On output generation, Grok Build 0.1 is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, Grok 4.3 provides an expanded memory horizon with 1,000K tokens. In latency-sensitive production environments, Grok Build 0.1 leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Cambia e Confronta Qualsiasi Modello
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Grok 4.3
Modello di Ragionamento ProfondoGrok 4.3 di xAI è un modello di intelligenza artificiale con finestra di contesto da 1M token e tariffazione API di $1.25/1M token in input e $2.5/1M in output, ideale per coding, ragionamento e automazione aziendale.
$1.25 / 1M
$2.50 / 1M
1M tokens
71.4%
Grok Build 0.1
Modello di Ragionamento ProfondoGrok Build 0.1 di xAI è un modello di intelligenza artificiale con finestra di contesto da 256K token e tariffazione API di $1.0/1M token in input e $2.0/1M in output, ideale per coding, ragionamento e automazione aziendale.
$1.00 / 1M
$2.00 / 1M
256K tokens
69.8%
Differenze Chiave a Colpo d’Occhio
- Grok Build 0.1 is 1.2x cheaper for API usage (input + output tokens combined).
- Grok 4.3 has a larger context window (1M vs 256K tokens).
- Grok Build 0.1 is faster at 120 tok/s vs 110 tok/s.
- Grok 4.3 leads on SWE-bench coding (71.4% vs 69.8%).
| Feature | Grok 4.3 | Grok Build 0.1 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 71 | 65 |
Provider | xAI | xAI |
Input Price Cost per million input tokens | $1.25 / 1M | $1.00 / 1M |
Output Price Cost per million output tokens | $2.50 / 1M | $2.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.72 / 1M | $0.57 / 1M |
Context Window Maximum input + output tokens | 1M tokens~1,500 A4 pages of text | 256K tokens~384 A4 pages of text |
Max Output Tokens Per single request | 66K | 66K |
Throughput Speed Tokens generated per second | 110 tok/s | 120 tok/s |
SWE-bench Verified Real-world software engineering | 71.4% | 69.8% |
GPQA Diamond Graduate-level reasoning | 73.5% | 68.2% |
Cached Input Price Prompt caching discount per 1M tokens | $0.31 / 1M | $0.25 / 1M |
Chi vince in ogni categoria?
At-a-glance decision frameworkPunteggi Benchmark Verificati
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
Latenza e Tempo di Risposta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulatore Interattivo dei Costi Token
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Grok 4.3 · Strengths & Key Advantages
- Architettura Colossus-Scale Mixture-of-Experts avanzata di xAI con supporto fino a 1M token di contesto
- Ottimo rapporto qualità-prezzo ($1.25/1M input, $2.5/1M output) e bassa latenza
- Elevate prestazioni nei benchmark di programmazione, logica e comprensione multilingue
Considerations & Trade-offs
- L'utilizzo intensivo di contesti molto ampi richiede un attento monitoraggio dei costi dei token
- Per casi d'uso verticali complessi è consigliabile un prompt engineering mirato
Grok Build 0.1 · Strengths & Key Advantages
- Architettura Code-Specialized Autoregressive Transformer avanzata di xAI con supporto fino a 256K token di contesto
- Ottimo rapporto qualità-prezzo ($1.0/1M input, $2.0/1M output) e bassa latenza
- Elevate prestazioni nei benchmark di programmazione, logica e comprensione multilingue
Considerations & Trade-offs
- L'utilizzo intensivo di contesti molto ampi richiede un attento monitoraggio dei costi dei token
- Per casi d'uso verticali complessi è consigliabile un prompt engineering mirato
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Grok 4.3 | Grok Build 0.1 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $1.35 | $0.95 |
Output Tokens / Task Tokens generated per task | 46K | 42K |
Reasoning Tokens / Task Thinking tokens burned per task | 22K | 18K |
Specifiche Tecniche
Architecture, release timeline, capabilities, and modalities.
| Feature | Grok 4.3 | Grok Build 0.1 |
|---|---|---|
| Official API Model ID (SDK) | grok-4-3-latest | grok-build-0-1-latest |
| API Protocol | xAI REST API (OpenAI-Compatible) | xAI REST API (OpenAI-Compatible) |
| Release Date | 2026-04 | 2026-04 |
| Knowledge Cutoff | January 2026 | January 2026 |
| Architecture | Colossus-Scale Mixture-of-Experts | Code-Specialized Autoregressive Transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 5,000 – 15,000 RPM (Production Tier) · 4,000,000 – 10,000,000 TPM | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($1.25/1M in) across full 1000K window | Flat rate ($1/1M in) across full 256K window |
| Prompt Cache Policy & TTL | Cached input at $0.31/1M tokens | Cached input at $0.25/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Real-time Web & X (Twitter) Search Grounding + Code Execution | Real-time Web & X (Twitter) Search Grounding + Code Execution |
| Official Fine-Tuning Support | API Prompt Engineering & RAG Distillation | API Prompt Engineering & RAG Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | xAI Production Safety & Alignment Verified | xAI Production Safety & Alignment Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Grok 4.3 vs Grok Build 0.1: Risposte Rapide (FAQ)
Which is more intelligent, Grok 4.3 or Grok Build 0.1?
Grok 4.3 is more intelligent. It scores 71 compared with 65 on the composite Intelligence Index.
Which model is faster?
Grok Build 0.1 is faster, generating 120 tokens per second compared with 110 tokens per second.
Which model is cheaper to run?
Grok Build 0.1 is cheaper at $0.57 per 1M tokens blended, compared with $0.72 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Grok Build 0.1 has lower latency, with a time to first token of 0.55s compared with 0.65s.
Which model has a larger context window?
Grok 4.3 has a larger context window, supporting 1M tokens compared with 256K tokens.
Verdetto
Verdict & Model Selection Recommendation: Choose Grok 4.3 if your priority is Enterprise knowledge retrieval, daily developer assistance, and general-purpose reasoning. Its performance in demanding tasks justifies its operational token cost. Choose Grok Build 0.1 if your workflow prioritizes IDE copilots, automated PR review agents, and rapid iterative software prototyping. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Domande Frequenti (FAQ)
How does Grok 4.3 compare to Grok Build 0.1 in API token pricing and cost per token?+
Grok 4.3 costs $1.25 per 1M input tokens and $2.50 per 1M output tokens, whereas Grok Build 0.1 costs $1.00 input and $2.00 output. Overall, Grok Build 0.1 is the more cost-effective model for high-volume API pipelines. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: Grok 4.3 or Grok Build 0.1?+
Grok 4.3 supports a context window of 1,000K tokens (~750k words), while Grok Build 0.1 supports 256K tokens (~192k words). Therefore, Grok 4.3 can process more textual data and document context in a single prompt.
Which AI model is better for software engineering and coding: Grok 4.3 or Grok Build 0.1?+
Grok 4.3 scores 71.4% on SWE-bench Verified while Grok Build 0.1 scores 69.8%. For autonomous software engineering and multi-file debugging, Grok 4.3 holds the verified benchmark lead.
What is the difference in reasoning capability and extended thinking between Grok 4.3 and Grok Build 0.1?+
Grok 4.3 features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, Grok Build 0.1 provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between Grok 4.3 and Grok Build 0.1?+
Grok 4.3 generates approximately 110 tokens per second, while Grok Build 0.1 delivers 120 tokens per second. In latency-sensitive production environments, Grok Build 0.1 provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Grok 4.3 and Grok Build 0.1 to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Grok Build 0.1 to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Grok 4.3. This tiered routing pattern cuts overall API bills by up to 70%.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Claude Opus 4.6 vs Grok Build 0.1: Benchmarks, Pricing & Speed ComparisonConfronta
- GPT-5.3 Chat vs Grok 4.3: Benchmarks, Pricing & Speed ComparisonConfronta
- Grok 4.5 vs Grok 4.3: Benchmarks, Pricing & Speed ComparisonConfronta
- Grok Build 0.1 vs Grok 4.20 (Reasoning): Benchmarks, Pricing & Speed ComparisonConfronta
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed ComparisonConfronta
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed ComparisonConfronta
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Fonti ufficiali: GetInfoUs Independent AI Benchmarks & Official API Specs