GLM-5.1 vs GLM-5.2
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
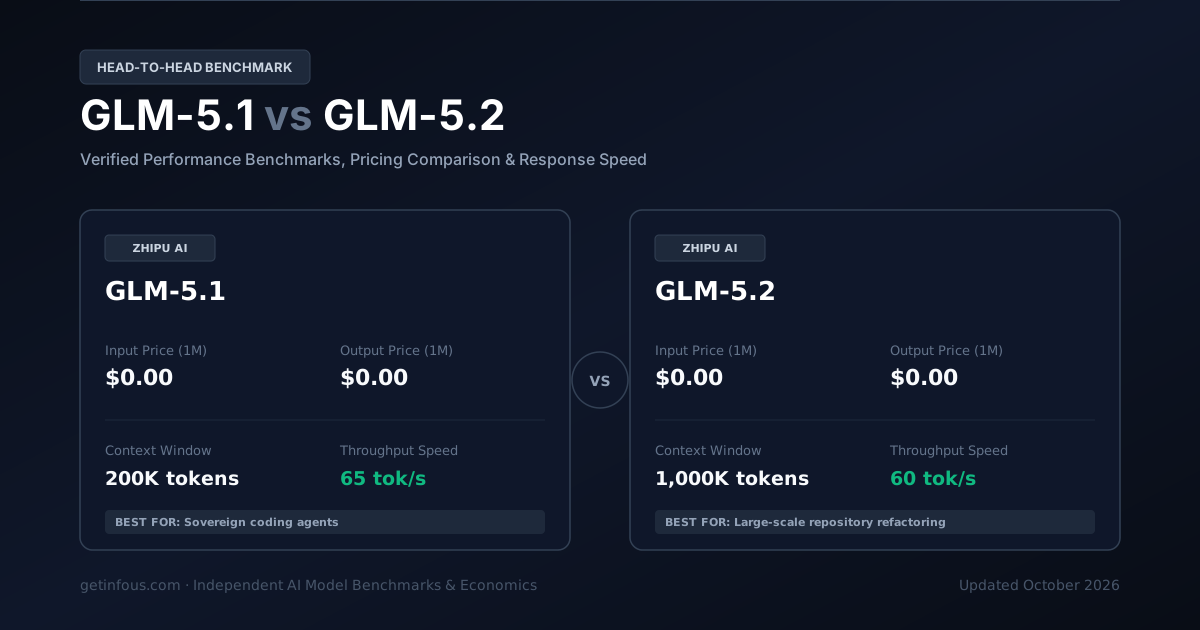
Zhipu AI का GLM-5.1 और Zhipu AI का GLM-5.2 दो प्रमुख एआई मॉडल हैं। GLM-5.1 में 200K टोकन कॉन्टेक्स्ट विंडो है और इसकी कीमत $0.00/$0.00 प्रति 1M टोकन है, जबकि GLM-5.2 में 1M टोकन कॉन्टेक्स्ट विंडो है और कीमत $0.00/$0.00 प्रति 1M टोकन है। यहाँ दोनों के बेंचमार्क, गति और लागत का विश्लेषण दिया गया है।
किसी भी मॉडल को बदलें और तुलना करें
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
GLM-5.1
ओपन-वेट्स कोडिंग विशेषज्ञZhipu AI का GLM-5.1 लोकल सर्वर पर कोडिंग और सॉफ्टवेयर डेवलपमेंट के लिए ओपन-वेट्स के लिए निर्मित एक उन्नत AI मॉडल है, जो 200K कॉन्टेक्स्ट विंडो, 65 टोकन/सेकंड स्पीड और निःशुल्क ओपन-वेट्स एक्सेस के साथ 89/100 इंटेलीजेंस स्कोर प्रदान करता है।
$0.00 / 1M
$0.00 / 1M
200K tokens
63%
GLM-5.2
ओपन-वेट्स फाउंडेशन मॉडलZhipu AI का GLM-5.2 प्राइवेट क्लाउड सेल्फ-होस्टिंग, फ़ाइन-ट्यूनिंग और पूर्ण डेटा गोपनीयता के लिए निर्मित एक उन्नत AI मॉडल है, जो 1M कॉन्टेक्स्ट विंडो, 60 टोकन/सेकंड स्पीड और निःशुल्क ओपन-वेट्स एक्सेस के साथ 91/100 इंटेलीजेंस स्कोर प्रदान कर
$0.00 / 1M
$0.00 / 1M
1M tokens
67.5%
एक नज़र में मुख्य अंतर
- Both models cost the same under this workload — choose on capability, not price.
- GLM-5.2 has a larger context window (1M vs 200K tokens).
- GLM-5.1 is faster at 65 tok/s vs 60 tok/s.
- GLM-5.2 leads on SWE-bench coding (67.5% vs 63.0%).
| Feature | GLM-5.1 | GLM-5.2 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 89 | 91 |
Provider | Zhipu AI | Zhipu AI |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 200K tokens~300 A4 pages of text | 1M tokens~1,500 A4 pages of text |
Max Output Tokens Per single request | 16K | 32K |
Throughput Speed Tokens generated per second | 65 tok/s | 60 tok/s |
SWE-bench Verified Real-world software engineering | 63% | 67.5% |
GPQA Diamond Graduate-level reasoning | 70% | 73.5% |
किस क्षेत्र में कौन आगे है?
At-a-glance decision frameworkसत्यापित बेंचमार्क स्कोर तुलना
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
लेटेंसी और रिस्पॉन्स समय
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
रियल-टाइम टोकन लागत सिम्युलेटर
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
GLM-5.1 · Strengths & Key Advantages
- 200K कॉन्टेक्स्ट विंडो और अधिकतम 16K आउटपुट टोकन क्षमता (SWE-bench Verified 63% · GPQA Diamond 70%)
- 65 टोकन/सेकंड की तेज़ जनरेशन स्पीड और मात्र 610ms का प्रथम टोकन लेटेंसी समय (TTFT)
- ओपन-वेट्स आर्किटेक्चर (280B MoE) — vLLM, Ollama या निजी GPU क्लस्टर पर सेल्फ-होस्टिंग के लिए उपयुक्त
Considerations & Trade-offs
- पूर्ण प्रिसिजन में लोकल GPU सर्वर पर चलाने के लिए पर्याप्त VRAM और हार्डवेयर संसाधनों की आवश्यकता होती है
- अत्यंत जटिल वैज्ञानिक शोध कार्यों में शीर्ष फ्लैगशिप रीजनिंग मॉडल की तुलना में गहराई थोड़ी कम हो सकती है
GLM-5.2 · Strengths & Key Advantages
- 1M कॉन्टेक्स्ट विंडो और अधिकतम 32K आउटपुट टोकन क्षमता (SWE-bench Verified 67.5% · GPQA Diamond 73.5%)
- 60 टोकन/सेकंड की तेज़ जनरेशन स्पीड और मात्र 650ms का प्रथम टोकन लेटेंसी समय (TTFT)
- ओपन-वेट्स आर्किटेक्चर (350B MoE) — vLLM, Ollama या निजी GPU क्लस्टर पर सेल्फ-होस्टिंग के लिए उपयुक्त
Considerations & Trade-offs
- पूर्ण प्रिसिजन में लोकल GPU सर्वर पर चलाने के लिए पर्याप्त VRAM और हार्डवेयर संसाधनों की आवश्यकता होती है
- अत्यंत जटिल वैज्ञानिक शोध कार्यों में शीर्ष फ्लैगशिप रीजनिंग मॉडल की तुलना में गहराई थोड़ी कम हो सकती है
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | GLM-5.1 | GLM-5.2 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 26K | 30K |
Reasoning Tokens / Task Thinking tokens burned per task | 9K | 12K |
तकनीकी विशिष्टताएँ (Specs)
Architecture, release timeline, capabilities, and modalities.
| Feature | GLM-5.1 | GLM-5.2 |
|---|---|---|
| Official API Model ID (SDK) | glm-5-1 | glm-5-2 |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-04 | 2026-06 |
| Knowledge Cutoff | February 2026 | February 2026 |
| Architecture | Expanded Code-Centric MoE Frontier Transformer | Massive Million-Token Open MoE Frontier Transformer |
| Parameters | 280B MoE | 350B MoE |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 174 GB VRAM (4-bit Quantized) · 602 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 217 GB VRAM (4-bit Quantized) · 753 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text | text |
| Output Modalities | text | text |
GLM-5.1 vs GLM-5.2: त्वरित प्रश्नोत्तर (FAQ)
Which is more intelligent, GLM-5.1 or GLM-5.2?
GLM-5.2 is more intelligent. It scores 91 compared with 89 on the composite Intelligence Index.
Which model is faster?
GLM-5.1 is faster, generating 65 tokens per second compared with 60 tokens per second.
Which model has lower latency?
GLM-5.1 has lower latency, with a time to first token of 0.61s compared with 0.65s.
Which model has a larger context window?
GLM-5.2 has a larger context window, supporting 1M tokens compared with 200K tokens.
निष्कर्ष
GLM-5.1 (लोकल सर्वर पर कोडिंग और सॉफ्टवेयर डेवलपमेंट के लिए ओपन-वेट्स, एंटरप्राइज RAG सिस्टम और स्केलेबल API इंटीग्रेशन के लिए सर्वोत्तम।) और GLM-5.2 (प्राइवेट क्लाउड सेल्फ-होस्टिंग, फ़ाइन-ट्यूनिंग और पूर्ण डेटा गोपनीयता, एंटरप्राइज RAG सिस्टम और स्केलेबल API इंटीग्रेशन के लिए सर्वोत्तम।) दोनों मजबूत विकल्प हैं: GLM-5.2 जटिल रीजनिंग और कोडिंग बेंचमार्क में आगे है, GLM-5.1 तेज़ टोकन जनरेशन देता है, और GLM-5.1 बड़े पैमाने के API उपयोग के लिए अधिक किफायती है।
अक्सर पूछे जाने वाले प्रश्न (FAQ)
कोडिंग और रीजनिंग के लिए GLM-5.1 या GLM-5.2 में से कौन बेहतर है?+
समग्र इंटेलिजेंस और कोडिंग बेंचमार्क में GLM-5.2 आगे है। विस्तृत तुलना के लिए ऊपर SWE-bench और GPQA स्कोर देखें।
GLM-5.1 और GLM-5.2 में किसका API सस्ता है?+
GLM-5.1 की इनपुट/आउटपुट कीमत $0.00 / $0.00 प्रति 1M टोकन है और GLM-5.2 की $0.00 / $0.00 है। समग्र लागत में GLM-5.1 अधिक किफायती है।
किस मॉडल का कॉन्टेक्स्ट विंडो और स्पीड बेहतर है?+
GLM-5.1 में 200K टोकन कॉन्टेक्स्ट विंडो है जबकि GLM-5.2 में 1M टोकन है। जनरेशन स्पीड के मामले में GLM-5.1 तेज़ है।
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- DeepSeek V4.1-Flash बनाम GLM-5.2: बेंचमार्क, API कीमत और स्पीड तुलना (2026)तुलना
- GLM-5.1 बनाम GLM-5: बेंचमार्क, API कीमत और स्पीड तुलना (2026)तुलना
- Kimi K3 बनाम GLM-5.2: बेंचमार्क, API कीमत और स्पीड तुलना (2026)तुलना
- Aion-3.0 बनाम Aion-Mini: बेंचमार्क, API कीमत और स्पीड तुलना (2026)तुलना
- Aion-3.0 बनाम Gemini 3.6 Flash: बेंचमार्क, API कीमत और स्पीड तुलना (2026)तुलना
- Aion-Mini बनाम Laguna XS 2.1: बेंचमार्क, API कीमत और स्पीड तुलना (2026)तुलना
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
स्रोत: Zhipu AI और Zhipu AI आधिकारिक API दस्तावेज़ और स्वतंत्र बेंचमार्क मूल्यांकन (2026)।