o3 vs o3-pro
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
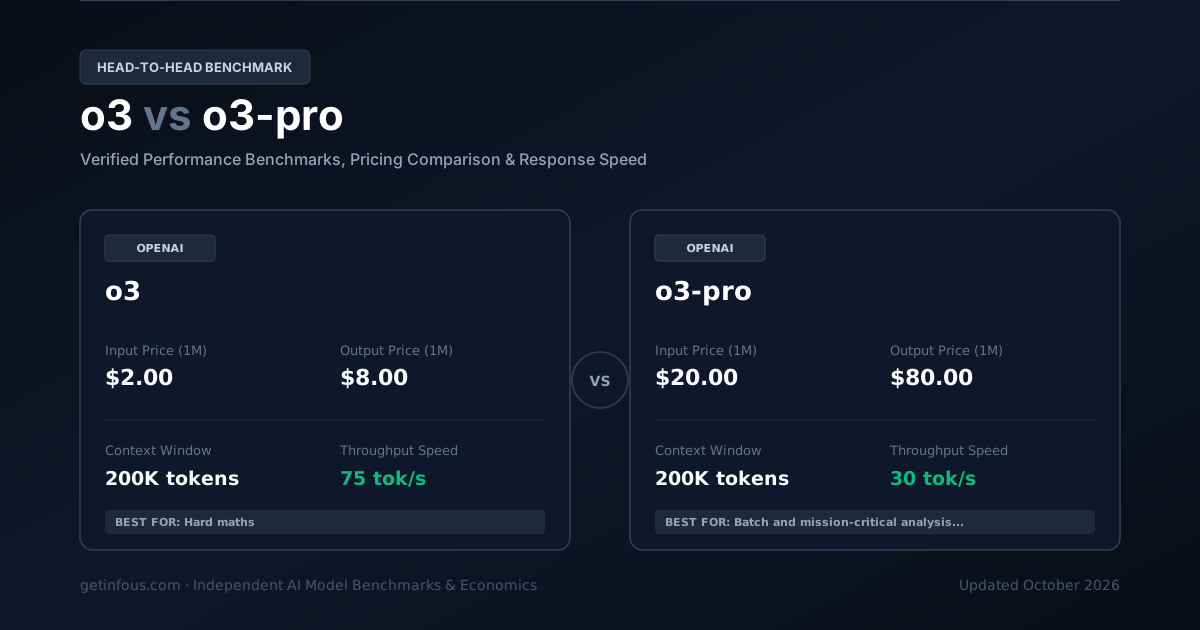
o3 de OpenAI y o3-pro de OpenAI compiten directamente en el ecosistema actual de IA. o3 ofrece una ventana de contexto de 200K tokens a $2.00/$8.00 por millón de tokens (entrada/salida), mientras que o3-pro ofrece 200K tokens de contexto a $20.00/$80.00 por millón de tokens. Analizamos sus benchmarks, latencia y costos reales.
Cambia y Compara Cualquier Modelo
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
o3
Motor de Razonamiento Profundoo3 de OpenAI es un modelo de IA diseñado para razonamiento lógico profundo, matemáticas avanzadas y resolución científica paso a paso, con ventana de contexto de 200K, velocidad de 75 tokens/s, índice de inteligencia de 56/100 y tarifa de $
$2.00 / 1M
$8.00 / 1M
200K tokens
69.1%
o3-pro
Motor de Razonamiento Profundoo3-pro de OpenAI es un modelo de IA diseñado para razonamiento lógico profundo, matemáticas avanzadas y resolución científica paso a paso, con ventana de contexto de 200K, velocidad de 30 tokens/s, índice de inteligencia de 58/100 y tarifa
$20.00 / 1M
$80.00 / 1M
200K tokens
71.5%
Diferencias Clave de un Vistazo
- o3 is 10.0x cheaper for API usage (input + output tokens combined).
- o3 is faster at 75 tok/s vs 30 tok/s.
- o3-pro leads on SWE-bench coding (71.5% vs 69.1%).
| Característica | o3 | o3-pro |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 56 | 58 |
Provider | OpenAI | OpenAI |
Input Price Cost per million input tokens | $2.00 / 1M | $20.00 / 1M |
Output Price Cost per million output tokens | $8.00 / 1M | $80.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $1.55 / 1M | $15.50 / 1M |
Context Window Maximum input + output tokens | 200K tokens~300 A4 pages of text | 200K tokens~300 A4 pages of text |
Max Output Tokens Per single request | 100K | 100K |
Throughput Speed Tokens generated per second | 75 tok/s | 30 tok/s |
SWE-bench Verified Real-world software engineering | 69.1% | 71.5% |
GPQA Diamond Graduate-level reasoning | 76.5% | 79.5% |
Cached Input Price Prompt caching discount per 1M tokens | $0.50 / 1M | $5.00 / 1M |
¿Quién gana en cada área?
At-a-glance decision frameworkPuntuaciones de Benchmarks Verificadas
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
Latencia y Tiempo de Respuesta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulador Interactivo de Costos de Tokens
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
o3 · Strengths & Key Advantages
- Ventana de contexto de 200K con hasta 100K tokens de salida máxima (SWE-bench Verified 69.1% · GPQA Diamond 76.5%)
- Rendimiento ágil de 75 tokens/segundo con latencia inicial (TTFT) de solo 2800 ms
- Economía de API competitiva ($2/$8 por 1M de tokens) con soporte para caché de prompts y salidas JSON estructuradas
Considerations & Trade-offs
- Modelo propietario en la nube; no permite descargar los pesos para ejecución local sin conexión
- En volúmenes masivos de tokens, se recomienda activar el caché de prompts y Batch API para optimizar costos
o3-pro · Strengths & Key Advantages
- Ventana de contexto de 200K con hasta 100K tokens de salida máxima (SWE-bench Verified 71.5% · GPQA Diamond 79.5%)
- Rendimiento ágil de 30 tokens/segundo con latencia inicial (TTFT) de solo 5200 ms
- Economía de API competitiva ($20/$80 por 1M de tokens) con soporte para caché de prompts y salidas JSON estructuradas
Considerations & Trade-offs
- Modelo propietario en la nube; no permite descargar los pesos para ejecución local sin conexión
- En volúmenes masivos de tokens, se recomienda activar el caché de prompts y Batch API para optimizar costos
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | o3 | o3-pro |
|---|---|---|
Cost per Task Estimated USD to finish one task | $1.35 | $11.68 |
Output Tokens / Task Tokens generated per task | 48K | 58K |
Reasoning Tokens / Task Thinking tokens burned per task | 26K | 38K |
Especificaciones Técnicas
Architecture, release timeline, capabilities, and modalities.
| Característica | o3 | o3-pro |
|---|---|---|
| Official API Model ID (SDK) | o3 | o3-pro |
| API Protocol | OpenAI Responses API & Chat Completions v1 | OpenAI Responses API & Chat Completions v1 |
| Release Date | 2025-04 | 2025-06 |
| Knowledge Cutoff | June 2024 | June 2024 |
| Architecture | Reasoning transformer with adjustable thinking effort | High-effort reasoning transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($2/1M in) across full 200K window | Flat rate ($20/1M in) across full 200K window |
| Prompt Cache Policy & TTL | Automatic prefix caching at $0.5/1M (no extra cache-write fee) | Automatic prefix caching at $5/1M (no extra cache-write fee) |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Native Web Search tool + Hosted Code Interpreter & File Search RAG | Native Web Search tool + Hosted Code Interpreter & File Search RAG |
| Official Fine-Tuning Support | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | OpenAI Preparedness Framework Audited & System Card Published | OpenAI Preparedness Framework Audited & System Card Published |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
o3 vs o3-pro: Respuestas Rápidas (FAQ)
Which is more intelligent, o3 or o3-pro?
o3-pro is more intelligent. It scores 58 compared with 56 on the composite Intelligence Index.
Which model is faster?
o3 is faster, generating 75 tokens per second compared with 30 tokens per second.
Which model is cheaper to run?
o3 is cheaper at $1.55 per 1M tokens blended, compared with $15.50 (7:2:1 cache:input:output ratio).
Which model has lower latency?
o3 has lower latency, with a time to first token of 2.80s compared with 5.20s.
Veredicto
Tanto o3 (Ideal para razonamiento lógico profundo, matemáticas avanzadas y resolución científica paso a paso, sistemas RAG empresariales y automatización mediante API.) como o3-pro (Ideal para razonamiento lógico profundo, matemáticas avanzadas y resolución científica paso a paso, sistemas RAG empresariales y automatización mediante API.) destacan en producción: o3-pro lidera en inteligencia general y programación, o3 ofrece mayor velocidad de generación de tokens y o3 resulta más rentable para cargas de trabajo API de alto volumen.
Preguntas frecuentes
¿Cuál es mejor para programación y razonamiento, o3 o o3-pro?+
En las pruebas de inteligencia compuesta y resolución de código, o3-pro obtiene la ventaja. Puedes revisar la tabla SWE-bench y GPQA arriba para comparar cada métrica.
¿Cuánto cuesta la API de o3 frente a o3-pro?+
o3 cuesta $2.00 / $8.00 por millón de tokens de entrada/salida, mientras que o3-pro cuesta $20.00 / $80.00. En costo combinado, o3 es la opción más económica.
¿Qué modelo tiene mayor ventana de contexto y menor latencia?+
o3 cuenta con 200K tokens de contexto frente a 200K tokens de o3-pro. En velocidad de inferencia, o3 ofrece un rendimiento superior.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Command A Reasoning vs. o3: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- GPT-5 Chat vs. o3-pro: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- Grok 4.20 (Reasoning) vs. o3: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- OpenAI o1 vs. o3: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- o3-pro vs. Claude Opus 5.5: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
- o3-pro vs. DeepSeek R1: Comparativa de Benchmarks, Precios API y Velocidad (2026)Comparar
Las puntuaciones de benchmarks, precios por token y límites de tasa evolucionan rápidamente. Verifique siempre las especificaciones actuales en la documentación oficial del proveedor.
Fuentes: Documentación oficial de API de OpenAI y OpenAI, tarjetas de sistema y benchmarks independientes (2026).