GPT-6 Sol vs Gemini 4 Argon
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
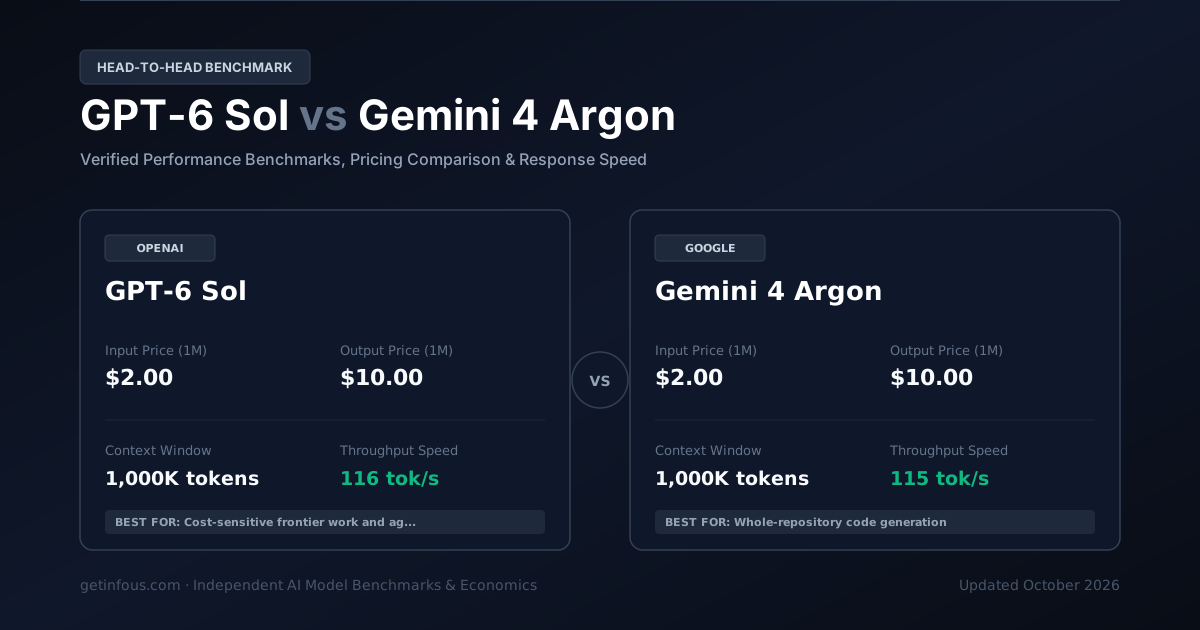
GPT-6 Sol by OpenAI and Gemini 4 Argon by Google represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, both models offer identical input token rates. On output generation, costs are matched. In data-heavy architectures requiring extensive repository or document analysis, both models provide an identical memory horizon with 1,000K tokens. In latency-sensitive production environments, GPT-6 Sol leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Cambia y Compara Cualquier Modelo
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
GPT-6 Sol
GPT-6 rentableun GPT-6 nivel ofreciendo complejo codificación y profesional trabajo un half el precio de GPT-5.6 Sol.
$2.00 / 1M
$10.00 / 1M
1M tokens
82.1%
Gemini 4 Argon
Rey multimodal con salida de 1MGoogle de DeepMind insignia de frontera razonamiento motor con 1-millones-token salida limits, autónomo cybersecurity defense, y en tiempo real audio/visión ingesta.
$2.00 / 1M
$10.00 / 1M
1M tokens
81.9%
Diferencias Clave de un Vistazo
- Both models cost the same under this workload — choose on capability, not price.
- GPT-6 Sol is faster at 116 tok/s vs 115 tok/s.
- GPT-6 Sol leads on SWE-bench coding (82.1% vs 81.9%).
| Característica | GPT-6 Sol | Gemini 4 Argon |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 93 | 97 |
Provider | OpenAI | |
Input Price Cost per million input tokens | $2.00 / 1M | $2.00 / 1M |
Output Price Cost per million output tokens | $10.00 / 1M | $10.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $1.47 / 1M | $1.47 / 1M |
Context Window Maximum input + output tokens | 1M tokens~1,500 A4 pages of text | 1M tokens~1,500 A4 pages of text |
Max Output Tokens Per single request | 128K | 1000K |
Throughput Speed Tokens generated per second | 116 tok/s | 115 tok/s |
SWE-bench Verified Real-world software engineering | 82.1% | 81.9% |
GPQA Diamond Graduate-level reasoning | 80.6% | 81.5% |
Cached Input Price Prompt caching discount per 1M tokens | $0.10 / 1M | $0.10 / 1M |
¿Quién gana en cada área?
At-a-glance decision frameworkPuntuaciones de Benchmarks Verificadas
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
Latencia y Tiempo de Respuesta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulador Interactivo de Costos de Tokens
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
GPT-6 Sol · Strengths & Key Advantages
- Roughly 50% cheaper que GPT-5.6 Sol
- Error rate close un half del previous generación
- sólido codificación agéntica y profesional flujos de trabajo
- Roughly half el precio de GPT-5.6 Sol con mejor error rates
Considerations & Trade-offs
- Weaker que GPT-6 Astra en el hardest tareas
- Sits close en precio un GPT-6.1 Sol, which es stronger
Gemini 4 Argon · Strengths & Key Advantages
- Groundbreaking 1,000,000 token maximum salida generación capacidad via largo Decode Continuation
- 1M-token entrada window con 99.7% GraphWalks recall (84.2% en el 256K-1M range)
- nativo procesamiento de completo audio, video streams, y visual datos (91.7% en LVBench)
- Half el token precio de de Anthropic Opus 5.5 y #1 en Chatbot Arena (1525 Elo)
Considerations & Trade-offs
- masivo token outputs puede incur alto absolute costos if unconstrained (~62K salida tokens por index tarea)
- $2/$10 precios es un introductory 50% discount; estándar rates revert un $4/$20 once el promotion ends
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | GPT-6 Sol | Gemini 4 Argon |
|---|---|---|
Cost per Task Estimated USD to finish one task | $2.00 | $2.45 |
Output Tokens / Task Tokens generated per task | 62K | 75K |
Reasoning Tokens / Task Thinking tokens burned per task | 36K | 36K |
Especificaciones Técnicas
Architecture, release timeline, capabilities, and modalities.
| Característica | GPT-6 Sol | Gemini 4 Argon |
|---|---|---|
| Official API Model ID (SDK) | gpt-6-sol | models/gemini-4-argon |
| API Protocol | OpenAI Responses API & Chat Completions v1 | Google Gemini API (generateContent) + OpenAI-Compatible SDK |
| Release Date | 2026-09 | 2026-09 |
| Knowledge Cutoff | April 2026 | June 2026 |
| Architecture | Cost-efficient frontier unified reasoning model | Pathways Multimodal Sparse Mixture-of-Experts |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 4,000,000 – 10,000,000 TPM | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 4,000,000 – 10,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($2/1M in) across full 1000K window | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens |
| Prompt Cache Policy & TTL | Automatic prefix caching at $0.1/1M (no extra cache-write fee) | Implicit + Explicit Context Caching at $0.1/1M with configurable TTL |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Native Web Search tool + Hosted Code Interpreter & File Search RAG | Built-in Google Search Grounding + Managed Python Code Execution Sandbox |
| Official Fine-Tuning Support | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) | Vertex AI Supervised Adapter Tuning & Context Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) · Audio (~25–32 tokens/sec) · Video (~258–300 tokens/sec) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | OpenAI Preparedness Framework Audited & System Card Published | Google DeepMind Frontier Safety Framework Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision, audio, video |
| Output Modalities | text | text |
GPT-6 Sol vs Gemini 4 Argon: Respuestas Rápidas (FAQ)
Which is more intelligent, GPT-6 Sol or Gemini 4 Argon?
Gemini 4 Argon is more intelligent. It scores 97 compared with 93 on the composite Intelligence Index.
Which model is faster?
GPT-6 Sol is faster, generating 116 tokens per second compared with 115 tokens per second.
Which model has lower latency?
Gemini 4 Argon has lower latency, with a time to first token of 0.85s compared with 1.16s.
Veredicto
Verdict & Model Selection Recommendation: Choose GPT-6 Sol if your priority is Cost-sensitive frontier work and agentic coding. Its performance in demanding tasks justifies its operational token cost. Choose Gemini 4 Argon if your workflow prioritizes Whole-repository code generation, full-book synthesis, video understanding, and multi-hour audio processing. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Preguntas frecuentes
How does GPT-6 Sol compare to Gemini 4 Argon in API token pricing and cost per token?+
Both GPT-6 Sol and Gemini 4 Argon share matched API token pricing at $2.00 per 1M input tokens and $10.00 per 1M output tokens. Because their token economics are identical, your selection should be guided by benchmark latency, memory horizon, and reasoning capabilities rather than operational token fees. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: GPT-6 Sol or Gemini 4 Argon?+
Both GPT-6 Sol and Gemini 4 Argon offer an identical context window of 1,000K tokens (~750k words). Both architectures provide equal capacity for large document ingestion, multi-file codebases, and extended multi-turn conversation histories.
Which AI model is better for software engineering and coding: GPT-6 Sol or Gemini 4 Argon?+
GPT-6 Sol scores 82.1% on SWE-bench Verified while Gemini 4 Argon scores 81.9%. For autonomous software engineering and multi-file debugging, GPT-6 Sol holds the verified benchmark lead.
What is the difference in reasoning capability and extended thinking between GPT-6 Sol and Gemini 4 Argon?+
GPT-6 Sol features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, Gemini 4 Argon provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between GPT-6 Sol and Gemini 4 Argon?+
GPT-6 Sol generates approximately 116 tokens per second, while Gemini 4 Argon delivers 115 tokens per second. In latency-sensitive production environments, GPT-6 Sol provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining GPT-6 Sol and Gemini 4 Argon to optimize costs?+
Yes! Tiered multi-model routing can optimize for latency and accuracy: you can route high-frequency conversational turns and latency-sensitive queries to GPT-6 Sol, and route deep architectural or complex reasoning queries to GPT-6 Sol. This balanced routing strategy maximizes system throughput and answer quality.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Claude Mythos 5.1 vs Gemini 4 Argon: Benchmarks, Pricing & Speed ComparisonComparar
- Claude Opus 5.5 vs Gemini 4 Argon: Benchmarks, Pricing & Speed ComparisonComparar
- Claude Sonnet 5.5 vs Gemini 4 Argon: Benchmarks, Pricing & Speed ComparisonComparar
- Command A Plus vs Gemini 4 Argon: Benchmarks, Pricing & Speed ComparisonComparar
- DeepSeek V4.1-Flash vs Gemini 4 Argon: Benchmarks, Pricing & Speed ComparisonComparar
- Gemini 4 Argon vs Claude Fable 5.1: Benchmarks, Pricing & Speed ComparisonComparar
Las puntuaciones de benchmarks, precios por token y límites de tasa evolucionan rápidamente. Verifique siempre las especificaciones actuales en la documentación oficial del proveedor.
Fuentes: GetInfoUs Independent AI Benchmarks & Official API Specs