Hy3 vs Kimi K2.7 Code
বেঞ্চমার্ক, এপিআই টোকেন মূল্য, কনটেক্সট উইন্ডো এবং ইনফারেন্স স্পিড তুলনা
Related topics (12)
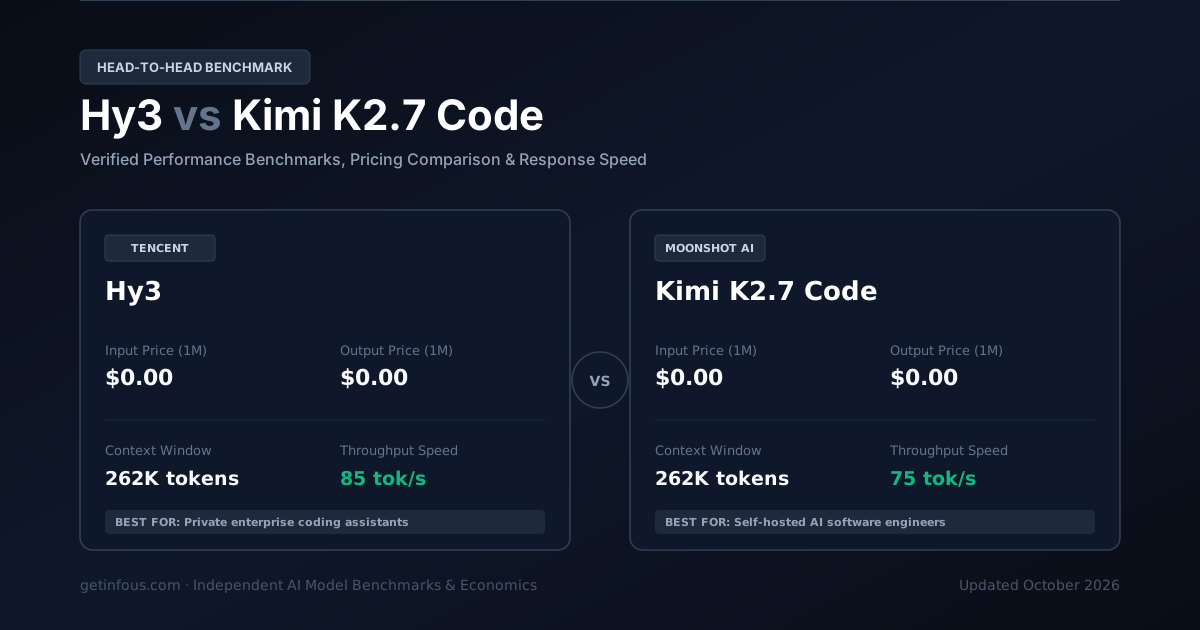
Hy3 by Tencent and Kimi K2.7 Code by Moonshot AI represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, both models offer identical input token rates. On output generation, costs are matched. In data-heavy architectures requiring extensive repository or document analysis, both models provide an identical memory horizon with 262K tokens. In latency-sensitive production environments, Hy3 leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
যেকোনো দুটি এআই মডেল পরিবর্তন ও তুলনা করুন
আমাদের যাচাইকৃত বেঞ্চমার্ক ডাটাবেস থেকে যেকোনো এআই মডেল নির্বাচন করে তাৎক্ষণিক তুলনা দেখুন।
Hy3
বাজেট রিজনারTencent-এর ওপেন-ওয়েটস Hy রিজনিং মডেল এর জন্য বিশেষভাবে তৈরি সাশ্রয়ী কোডিং, সুসংগঠিত টুল এক্সিকিউশন, এবং এর ওপর-premises এন্টারপ্রাইজ ওয়ার্কলোড.
$0.00 / 1M
$0.00 / 1M
262.1K tokens
N/A
Kimi K2.7 Code
কোডিং বিশেষজ্ঞনিবেদিত code engineering পাওয়ারহাউস trained প্রতি avoid unnecessary রিজনিং overhead পাশাপাশি প্রদানকারী pinpoint রিপোজিটরি রিফ্যাক্টরিং.
$0.00 / 1M
$0.00 / 1M
262.1K tokens
62%
একনজরে প্রধান পার্থক্যসমূহ
- Both models cost the same under this workload — choose on capability, not price.
- Hy3 is faster at 85 tok/s vs 75 tok/s.
| বৈশিষ্ট্য | Hy3 | Kimi K2.7 Code |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 81 | 89 |
Provider | Tencent | Moonshot AI |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 262.1K tokens~393 A4 pages of text | 262.1K tokens~393 A4 pages of text |
Max Output Tokens Per single request | 16K | 32K |
Throughput Speed Tokens generated per second | 85 tok/s | 75 tok/s |
SWE-bench Verified Real-world software engineering | N/A | 62% |
GPQA Diamond Graduate-level reasoning | 64% | 73% |
কোন ক্ষেত্রে কোন মডেল সেরা?
একনজরে সিদ্ধান্ত নেওয়ার ফ্রেমওয়ার্কEvaluations ongoing
যাচাইকৃত বেঞ্চমার্ক স্কোর তুলনা
স্বাধীন গবেষণা ল্যাব দ্বারা যাচাইকৃত অফিশিয়াল ইভ্যালুয়েশন মেট্রিক্স।
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Contamination-free competitive programming problems collected continuously over time.
Tokens emitted per second during active generation streaming.
লেটেন্সি ও রেসপন্স টাইম
প্রথম টোকেন আসার সময় (TTFT) এবং ৫০০ টোকেনের রেসপন্স জেনারেট করতে আনুমানিক সময়।
রিয়েল-টাইম টোকেন খরচ সিমুলেটর
প্রম্পট ক্যাশিং ডিসকাউন্টসহ মাসিক ক্লাউড API খরচ হিসাব করতে স্লাইডার পরিবর্তন করুন।
Hy3 · শক্তি ও প্রধান সুবিধাসমূহ
- Solid 262K কনটেক্সট উইন্ডো সহ ওপেন-ওয়েটস এর জন্য লোকাল privacy
- নির্দেশনা অনুসরণে অত্যন্ত পারদর্শী এবং নির্ভরযোগ্য JSON function calling
- Reasonable হার্ডওয়্যার ফুটপ্রিন্ট deployable এর ওপর মানদণ্ড dual-GPU setups
বিবেচ্য বিষয় ও সীমাবদ্ধতা
- Slightly behind ফ্রন্টিয়ার মডেলগুলো এর ওপর difficult Olympiad-level mathematics
- কম community ইকোসিস্টেম documentation outside এর China
Kimi K2.7 Code · শক্তি ও প্রধান সুবিধাসমূহ
- 62% SWE-bench score সহ reduced টোকেন verbosity এবং দ্রুত প্রজন্ম turnaround
- Superb অনুধাবন এর intricate মাল্টি-ফাইল git diffs এবং dependency trees
- উচ্চ নির্দেশনা alignment specifically tuned এর জন্য সফটওয়্যার ডেভেলপার
বিবেচ্য বিষয় ও সীমাবদ্ধতা
- কম এর জন্য অপ্টিমাইজড সৃজনশীল writing বা casual ওপেন-ended chatting
- Heavyweight মডেল requiring এন্টারপ্রাইজ GPU hosting
টোকেন ব্যবহার ও টাস্ক ইকোনমিক্স
একটি স্ট্যান্ডার্ড এজেন্টিক টাস্ক সম্পন্ন করতে আনুমানিক খরচ এবং টোকেন ব্যবহার।
| Metric | Hy3 | Kimi K2.7 Code |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 18K | 26K |
Reasoning Tokens / Task Thinking tokens burned per task | 5K | 5K |
টেকনিক্যাল স্পেসিফিকেশন
অফিশিয়াল প্রোভাইডার রিলিজ স্পেক্স, API মডেল আইডি, রেট লিমিট, লং-কনটেক্সট প্রাইসিং ও এজেন্টিক সক্ষমতা
| বৈশিষ্ট্য | Hy3 | Kimi K2.7 Code |
|---|---|---|
| অফিশিয়াল API মডেল আইডি (SDK) | hy3 | kimi-k2-7-code |
| API প্রোটোকল | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| রিলিজ তারিখ | 2026-07 | 2026-06 |
| নলেজ কাটঅফ | April 2026 | April 2026 |
| আর্কিটেকচার | Efficient Open Reasoning MoE Transformer | Code-Optimized Sparse Mixture-of-Experts Transformer |
| প্যারামিটার স্কেল | Confidential / 140B MoE | 1.5T total (40B active MoE) |
| এন্টারপ্রাইজ রেট লিমিট (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| লং-কনটেক্সট প্রাইসিং (>128K/200K) | পূর্ণ কনটেক্সট উইন্ডোতে সম্পূর্ণ ফ্রি (শুধু জিপিইউ VRAM ব্যবহৃত হয়) | পূর্ণ কনটেক্সট উইন্ডোতে সম্পূর্ণ ফ্রি (শুধু জিপিইউ VRAM ব্যবহৃত হয়) |
| প্রম্পট ক্যাশিং ও TTL | vLLM ও SGLang-এ স্বয়ংক্রিয় প্রিফিক্স KV-ক্যাশিং (সম্পূর্ণ বিনামূল্যে) | vLLM ও SGLang-এ স্বয়ংক্রিয় প্রিফিক্স KV-ক্যাশিং (সম্পূর্ণ বিনামূল্যে) |
| কম্পিউটার ইউজ / GUI এজেন্ট | API ও CLI টুল-কলিং এজেন্ট সমর্থিত (র-পিক্সেল ডেস্কটপ ক্লিক ছাড়া) | সমর্থিত (স্ক্রিন কোঅর্ডিনেট গ্রাউন্ডিং, ব্রাউজার ও ডেস্কটপ GUI অটোমেশন) |
| MCP ও প্যারালাল টুল কলিং | নেটিভ MCP সাপোর্ট · প্যারালাল ফাংশন কলিং · ১০০% স্ট্রিক্ট JSON স্কিমা | নেটিভ MCP সাপোর্ট · প্যারালাল ফাংশন কলিং · ১০০% স্ট্রিক্ট JSON স্কিমা |
| ওয়েব সার্চ ও কোড স্যান্ডবক্স | এক্সটার্নাল সার্চ (Tavily/Exa) ও ডকার স্যান্ডবক্সের মাধ্যমে সমর্থিত | এক্সটার্নাল সার্চ (Tavily/Exa) ও ডকার স্যান্ডবক্সের মাধ্যমে সমর্থিত |
| অফিশিয়াল ফাইন-টিউনিং (SFT/LoRA/RFT) | পূর্ণ ওয়েটস SFT, LoRA, QLoRA, DPO ও RL ফাইন-টিউনিং (Unsloth / Axolotl) | পূর্ণ ওয়েটস SFT, LoRA, QLoRA, DPO ও RL ফাইন-টিউনিং (Unsloth / Axolotl) |
| মাল্টিমোডাল টোকেন বিলিং | টেক্সট BPE (~৪ অক্ষর/টোকেন) | টেক্সট BPE (~৪ অক্ষর/টোকেন) · ইমেজ (~২৫৮–৭৬৫ টোকেন/ছবি) |
| কোয়ান্টাইজেশন ও মিনিমাম VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 87 GB VRAM (৪-বিট কোয়ান্টাইজড) · 301 GB VRAM (নেটিভ BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 930 GB VRAM (৪-বিট কোয়ান্টাইজড) · 3225 GB VRAM (নেটিভ BF16) |
| সেফটি ও ফ্রন্টিয়ার ক্লাসিফিকেশন | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| এন্টারপ্রাইজ কমপ্লায়েন্স (ZDR/HIPAA/SOC2) | ১০০% অন-প্রেমিসেস / প্রাইভেট VPC নিয়ন্ত্রণ · সম্পূর্ণ HIPAA, GDPR ও SOC2 কমপ্লায়েন্ট | ১০০% অন-প্রেমিসেস / প্রাইভেট VPC নিয়ন্ত্রণ · সম্পূর্ণ HIPAA, GDPR ও SOC2 কমপ্লায়েন্ট |
| ইনপুট মডালিটি | text | text, vision |
| আউটপুট মডালিটি | text | text |
Hy3 vs Kimi K2.7 Code: সংক্ষিপ্ত প্রশ্নোত্তর (FAQ)
Which is more intelligent, Hy3 or Kimi K2.7 Code?
Kimi K2.7 Code is more intelligent. It scores 89 compared with 81 on the composite Intelligence Index.
Which model is faster?
Hy3 is faster, generating 85 tokens per second compared with 75 tokens per second.
Which model has lower latency?
Hy3 has lower latency, with a time to first token of 0.46s compared with 0.48s.
চূড়ান্ত মতামত
Verdict & Model Selection Recommendation: Choose Hy3 if your priority is Private enterprise coding assistants, automated workflow agents, and internal data analysis. Its performance in demanding tasks justifies its operational token cost. Choose Kimi K2.7 Code if your workflow prioritizes Self-hosted AI software engineers, automated CI/CD code repair, and security auditing. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
সাধারণ জিজ্ঞাসা (FAQ)
How does Hy3 compare to Kimi K2.7 Code in API token pricing and cost per token?+
Both Hy3 and Kimi K2.7 Code are open-weights foundation models available at $0.00 direct API cost when self-hosted, or offered at identical baseline rates across major inference providers. Model selection depends on GPU deployment sizing and specialized benchmark performance rather than raw token price.
Which model has a larger context window: Hy3 or Kimi K2.7 Code?+
Both Hy3 and Kimi K2.7 Code offer an identical context window of 262K tokens (~197k words). Both architectures provide equal capacity for large document ingestion, multi-file codebases, and extended multi-turn conversation histories.
Which AI model is better for software engineering and coding: Hy3 or Kimi K2.7 Code?+
Hy3 scores at the frontier of coding benchmarks, while Kimi K2.7 Code scores 62%. For complex autonomous debugging and agentic engineering, Kimi K2.7 Code provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between Hy3 and Kimi K2.7 Code?+
Hy3 features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, Kimi K2.7 Code provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between Hy3 and Kimi K2.7 Code?+
Hy3 generates approximately 85 tokens per second, while Kimi K2.7 Code delivers 75 tokens per second. In latency-sensitive production environments, Hy3 provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Hy3 and Kimi K2.7 Code to optimize costs?+
Yes! Tiered multi-model routing can optimize for latency and accuracy: you can route high-frequency conversational turns and latency-sensitive queries to Hy3, and route deep architectural or complex reasoning queries to Hy3. This balanced routing strategy maximizes system throughput and answer quality.
মডেলের বিভিন্ন পরিমাপক যেমন কনটেক্সট উইন্ডো, টোকেন প্রাইজ এবং রিজনিং স্কোর সম্পর্কে বিস্তারিত জানতে আমাদের এআই গ্লোসারি দেখুন।
Related reading
- Hy3 vs Hy3 preview: Benchmarks, Pricing & Speed Comparisonতুলনা
- MiniMax-M3 vs Kimi K2.7 Code: Benchmarks, Pricing & Speed Comparisonতুলনা
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed Comparisonতুলনা
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed Comparisonতুলনা
- Aion-Mini vs Laguna XS 2.1: Benchmarks, Pricing & Speed Comparisonতুলনা
- Aya Expanse 32B vs Llama 3.2 90B Vision: Benchmarks, Pricing & Speed Comparisonতুলনা
এআই ল্যাবগুলোর নতুন রিলিজের সাথে সাথে বেঞ্চমার্ক স্কোর, টোকেন প্রাইসিং এবং রেট লিমিট নিয়মিত পরিবর্তিত হয়। প্রোডাকশনে ব্যবহারের পূর্বে সর্বদা অফিশিয়াল প্রোভাইডার ডকুমেন্টেশন যাচাই করুন।
তথ্যসূত্র: GetInfoUs Independent AI Benchmarks & Official API Specs