MiniMax-M2 vs GLM-4.6
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
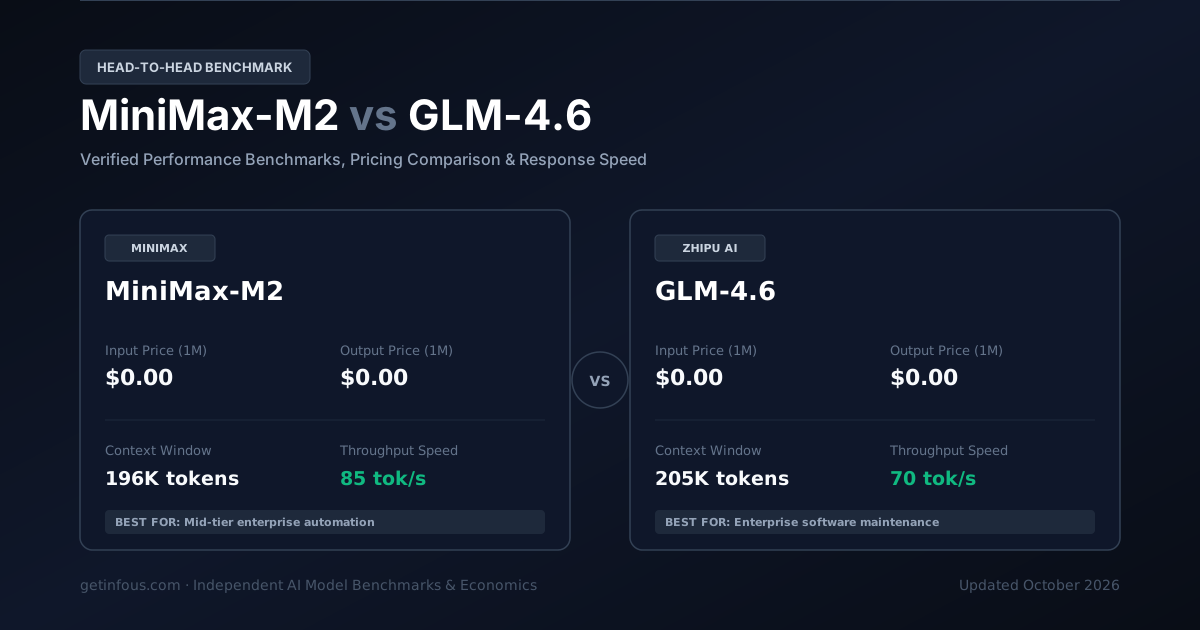
MiniMax-M2 by MiniMax and GLM-4.6 by Zhipu AI represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, both models offer identical input token rates. On output generation, costs are matched. In data-heavy architectures requiring extensive repository or document analysis, GLM-4.6 provides an expanded memory horizon with 205K tokens. In latency-sensitive production environments, MiniMax-M2 leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
원하는 AI 모델 선택 및 실시간 비교
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
MiniMax-M2
오픈 웨이트 모델MiniMax의 MiniMax-M2 모델은 196K 토큰 컨텍스트 윈도우와 입력 $0/1M 토큰, 출력 $0/1M 토큰의 합리적인 API 요금을 제공하며 코딩, 추론 및 엔터프라이즈 자동화에 최적화되어 있습니다.
$0.00 / 1M
$0.00 / 1M
196K tokens
N/A
GLM-4.6
오픈 웨이트 모델Zhipu AI의 GLM-4.6 모델은 204K 토큰 컨텍스트 윈도우와 입력 $0/1M 토큰, 출력 $0/1M 토큰의 합리적인 API 요금을 제공하며 코딩, 추론 및 엔터프라이즈 자동화에 최적화되어 있습니다.
$0.00 / 1M
$0.00 / 1M
204.8K tokens
48%
한눈에 보는 핵심 차이점
- Both models cost the same under this workload — choose on capability, not price.
- GLM-4.6 has a larger context window (205K vs 196K tokens).
- MiniMax-M2 is faster at 85 tok/s vs 70 tok/s.
| Feature | MiniMax-M2 | GLM-4.6 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 78 | 82 |
Provider | MiniMax | Zhipu AI |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 196K tokens~294 A4 pages of text | 204.8K tokens~307 A4 pages of text |
Max Output Tokens Per single request | 8K | 8K |
Throughput Speed Tokens generated per second | 85 tok/s | 70 tok/s |
SWE-bench Verified Real-world software engineering | N/A | 48% |
GPQA Diamond Graduate-level reasoning | 58% | 63.5% |
부문별 우위 모델
At-a-glance decision frameworkEvaluations ongoing
검증된 벤치마크 점수 비교
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
지연 시간(Latency) 및 응답 속도
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
실시간 API 토큰 비용 시뮬레이터
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
MiniMax-M2 · Strengths & Key Advantages
- MiniMax의 첨단 High-Efficiency Open Mixture-of-Experts Transformer 아키텍처와 최대 196K 토큰 컨텍스트 지원
- 경쟁력 있는 API 가격(입력 $0/1M, 출력 $0/1M)과 빠른 응답 속도
- 코드 생성, 복잡한 논리 추론 및 다국어 벤치마크에서 검증된 성능 발휘
Considerations & Trade-offs
- 대규모 장문 컨텍스트 처리 시 토큰 비용 및 호출 한도 관리가 필요함
- 특수 도메인 작업에서는 정교한 프롬프트 엔지니어링과 RAG 연동이 권장됨
GLM-4.6 · Strengths & Key Advantages
- Zhipu AI의 첨단 Advanced Mixture-of-Experts Enterprise Transformer 아키텍처와 최대 204K 토큰 컨텍스트 지원
- 경쟁력 있는 API 가격(입력 $0/1M, 출력 $0/1M)과 빠른 응답 속도
- 코드 생성, 복잡한 논리 추론 및 다국어 벤치마크에서 검증된 성능 발휘
Considerations & Trade-offs
- 대규모 장문 컨텍스트 처리 시 토큰 비용 및 호출 한도 관리가 필요함
- 특수 도메인 작업에서는 정교한 프롬프트 엔지니어링과 RAG 연동이 권장됨
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | MiniMax-M2 | GLM-4.6 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 15K | 18K |
Reasoning Tokens / Task Thinking tokens burned per task | 3K | 6K |
기술 사양 (Specifications)
Architecture, release timeline, capabilities, and modalities.
| Feature | MiniMax-M2 | GLM-4.6 |
|---|---|---|
| Official API Model ID (SDK) | minimax-m2 | glm-4-6 |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2025-10 | 2025-09 |
| Knowledge Cutoff | August 2025 | July 2025 |
| Architecture | High-Efficiency Open Mixture-of-Experts Transformer | Advanced Mixture-of-Experts Enterprise Transformer |
| Parameters | Confidential / 120B MoE | 150B MoE |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 74 GB VRAM (4-bit Quantized) · 258 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 93 GB VRAM (4-bit Quantized) · 323 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text | text |
| Output Modalities | text | text |
MiniMax-M2 vs GLM-4.6: 핵심 요약 문답 (FAQ)
Which is more intelligent, MiniMax-M2 or GLM-4.6?
GLM-4.6 is more intelligent. It scores 82 compared with 78 on the composite Intelligence Index.
Which model is faster?
MiniMax-M2 is faster, generating 85 tokens per second compared with 70 tokens per second.
Which model has lower latency?
MiniMax-M2 has lower latency, with a time to first token of 0.44s compared with 0.56s.
Which model has a larger context window?
GLM-4.6 has a larger context window, supporting 204.8K tokens compared with 196K tokens.
종합 평가
Verdict & Model Selection Recommendation: Choose MiniMax-M2 if your priority is Mid-tier enterprise automation, customer chatbots, and internal knowledge search. Its performance in demanding tasks justifies its operational token cost. Choose GLM-4.6 if your workflow prioritizes Enterprise software maintenance, repository code reviews, and automated compliance auditing. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
자주 묻는 질문 (FAQ)
How does MiniMax-M2 compare to GLM-4.6 in API token pricing and cost per token?+
Both MiniMax-M2 and GLM-4.6 are open-weights foundation models available at $0.00 direct API cost when self-hosted, or offered at identical baseline rates across major inference providers. Model selection depends on GPU deployment sizing and specialized benchmark performance rather than raw token price.
Which model has a larger context window: MiniMax-M2 or GLM-4.6?+
MiniMax-M2 supports a context window of 196K tokens (~147k words), while GLM-4.6 supports 205K tokens (~154k words). Therefore, GLM-4.6 can process more textual data and document context in a single prompt.
Which AI model is better for software engineering and coding: MiniMax-M2 or GLM-4.6?+
MiniMax-M2 scores at the frontier of coding benchmarks, while GLM-4.6 scores 48%. For complex autonomous debugging and agentic engineering, GLM-4.6 provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between MiniMax-M2 and GLM-4.6?+
MiniMax-M2 features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, GLM-4.6 provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between MiniMax-M2 and GLM-4.6?+
MiniMax-M2 generates approximately 85 tokens per second, while GLM-4.6 delivers 70 tokens per second. In latency-sensitive production environments, MiniMax-M2 provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining MiniMax-M2 and GLM-4.6 to optimize costs?+
Yes! Tiered multi-model routing can optimize for latency and accuracy: you can route high-frequency conversational turns and latency-sensitive queries to MiniMax-M2, and route deep architectural or complex reasoning queries to MiniMax-M2. This balanced routing strategy maximizes system throughput and answer quality.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- GLM-4.6 vs Qwen3-Next 80B-A3B (Thinking): Benchmarks, Pricing & Speed Comparison비교
- GLM-4.6V vs GLM-4.6: Benchmarks, Pricing & Speed Comparison비교
- MiniMax-M2.1 vs MiniMax-M2: Benchmarks, Pricing & Speed Comparison비교
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed Comparison비교
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed Comparison비교
- Aion-Mini vs Laguna XS 2.1: Benchmarks, Pricing & Speed Comparison비교
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
공식 출처: GetInfoUs Independent AI Benchmarks & Official API Specs