Kimi K2.6 vs Kimi K2.5
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
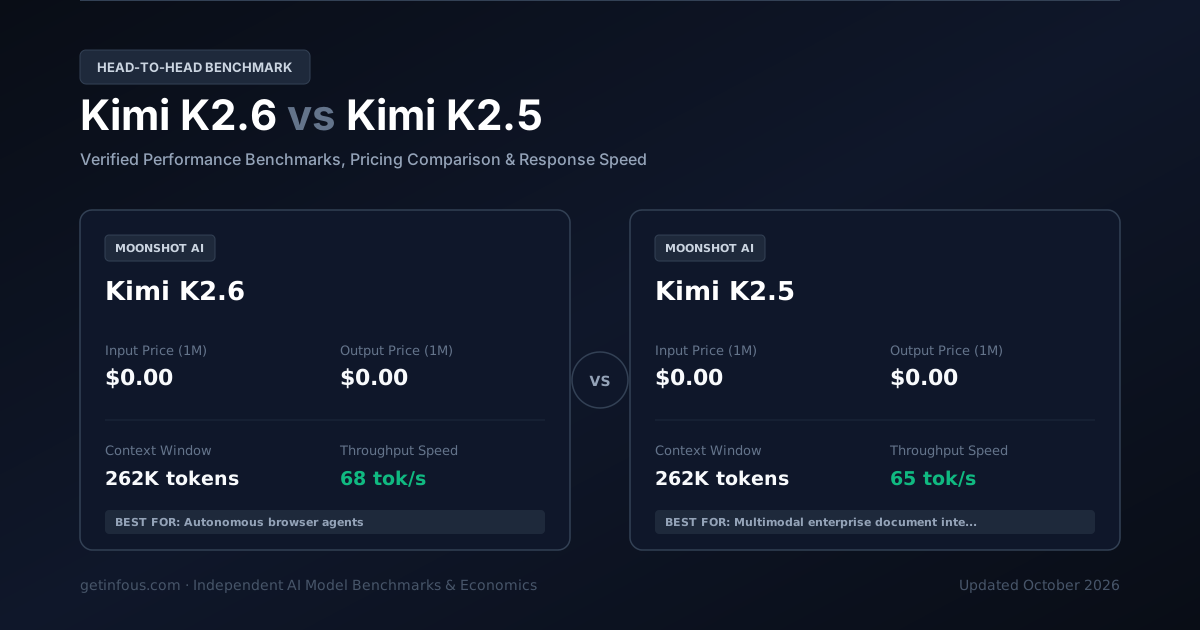
Moonshot AI의 Kimi K2.6와 Moonshot AI의 Kimi K2.5는 현재 가장 주목받는 AI 모델입니다. Kimi K2.6는 262.1K 토큰 컨텍스트 윈도우와 100만 토큰당 $0.00/$0.00(입력/출력)의 요금을 제공하며, Kimi K2.5는 262.1K 토큰 컨텍스트와 $0.00/$0.00의 요금을 제공합니다. 아래에서 벤치마크, 지연 시간 및 비용을 상세히 비교해 보세요.
원하는 AI 모델 선택 및 실시간 비교
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Kimi K2.6
자율 에이전트 및 도구 호출 특화Moonshot AI의 Kimi K2.6 모델은 자율 에이전트 워크플로우, 도구 호출(Tool Calling) 및 다단계 업무 자동화에 최적화된 AI 모델로, 262K 컨텍스트 윈도우, 초당 68 토큰의 생성 속도, 종합 지능 지수 87/100점(무료 오픈 웨이트 제공)을 제공합니다.
$0.00 / 1M
$0.00 / 1M
262.1K tokens
54%
Kimi K2.5
네이티브 멀티모달 AIMoonshot AI의 Kimi K2.5 모델은 텍스트와 이미지의 네이티브 멀티모달 이해 및 복합 문서·차트 분석에 최적화된 AI 모델로, 262K 컨텍스트 윈도우, 초당 65 토큰의 생성 속도, 종합 지능 지수 86/100점(무료 오픈 웨이트 제공)을 제공합니다.
$0.00 / 1M
$0.00 / 1M
262.1K tokens
52%
한눈에 보는 핵심 차이점
- Both models cost the same under this workload — choose on capability, not price.
- Kimi K2.6 is faster at 68 tok/s vs 65 tok/s.
- Kimi K2.6 leads on SWE-bench coding (54.0% vs 52.0%).
| Feature | Kimi K2.6 | Kimi K2.5 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 87 | 86 |
Provider | Moonshot AI | Moonshot AI |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 262.1K tokens~393 A4 pages of text | 262.1K tokens~393 A4 pages of text |
Max Output Tokens Per single request | 16K | 16K |
Throughput Speed Tokens generated per second | 68 tok/s | 65 tok/s |
SWE-bench Verified Real-world software engineering | 54% | 52% |
GPQA Diamond Graduate-level reasoning | 71% | 69.5% |
부문별 우위 모델
At-a-glance decision framework검증된 벤치마크 점수 비교
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
지연 시간(Latency) 및 응답 속도
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
실시간 API 토큰 비용 시뮬레이터
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Kimi K2.6 · Strengths & Key Advantages
- 262K 컨텍스트 윈도우 및 최대 16K 출력 토큰 생성 지원 (SWE-bench Verified 54% · GPQA Diamond 71%)
- 초당 68 토큰의 빠른 처리 속도와 590ms에 불과한 첫 토큰 지연 시간(TTFT)
- 오픈 웨이트 아키텍처 (1.5T total (40B MoE))를 통해 vLLM, SGLang, Ollama 기반 자체 GPU 서버 구축 및 파인튜닝 가능
Considerations & Trade-offs
- 비양자화 전체 정밀도로 로컬 서버에서 구동하려면 충분한 GPU VRAM 용량이 필요합니다
- 초고난도 학술 연구 및 수학 증명 과제에서는 상위 대형 추론 특화 모델이 더 깊은 분석을 제공할 수 있습니다
Kimi K2.5 · Strengths & Key Advantages
- 262K 컨텍스트 윈도우 및 최대 16K 출력 토큰 생성 지원 (SWE-bench Verified 52% · GPQA Diamond 69.5%)
- 초당 65 토큰의 빠른 처리 속도와 620ms에 불과한 첫 토큰 지연 시간(TTFT)
- 오픈 웨이트 아키텍처 (1.2T total (36B MoE))를 통해 vLLM, SGLang, Ollama 기반 자체 GPU 서버 구축 및 파인튜닝 가능
Considerations & Trade-offs
- 비양자화 전체 정밀도로 로컬 서버에서 구동하려면 충분한 GPU VRAM 용량이 필요합니다
- 초고난도 학술 연구 및 수학 증명 과제에서는 상위 대형 추론 특화 모델이 더 깊은 분석을 제공할 수 있습니다
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Kimi K2.6 | Kimi K2.5 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 25K | 24K |
Reasoning Tokens / Task Thinking tokens burned per task | 9K | 8K |
기술 사양 (Specifications)
Architecture, release timeline, capabilities, and modalities.
| Feature | Kimi K2.6 | Kimi K2.5 |
|---|---|---|
| Official API Model ID (SDK) | kimi-k2-6 | kimi-k2-5 |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-04 | 2026-01 |
| Knowledge Cutoff | February 2026 | November 2025 |
| Architecture | Refined Multimodal Agentic MoE Transformer | Multimodal Open Mixture-of-Experts Transformer |
| Parameters | 1.5T total (40B active MoE) | 1.2T total (36B active MoE) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 930 GB VRAM (4-bit Quantized) · 3225 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 744 GB VRAM (4-bit Quantized) · 2580 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Kimi K2.6 vs Kimi K2.5: 핵심 요약 문답 (FAQ)
Which is more intelligent, Kimi K2.6 or Kimi K2.5?
Kimi K2.6 is more intelligent. It scores 87 compared with 86 on the composite Intelligence Index.
Which model is faster?
Kimi K2.6 is faster, generating 68 tokens per second compared with 65 tokens per second.
Which model has lower latency?
Kimi K2.6 has lower latency, with a time to first token of 0.59s compared with 0.62s.
종합 평가
Kimi K2.6(자율 에이전트 워크플로우, 도구 호출(Tool Calling) 및 다단계 업무 자동화, 엔터프라이즈 RAG 지식베이스 및 대규모 프로덕션 API 연동에 최적.)와 Kimi K2.5(텍스트와 이미지의 네이티브 멀티모달 이해 및 복합 문서·차트 분석, 엔터프라이즈 RAG 지식베이스 및 대규모 프로덕션 API 연동에 최적.) 모두 뛰어난 성능을 자랑합니다. 고난도 추론과 코딩 벤치마크에서는 Kimi K2.6가 앞서며, 토큰 생성 속도에서는 Kimi K2.6가 빠르고, 대규모 API 운영 비용 면에서는 Kimi K2.6가 더 경제적입니다.
자주 묻는 질문 (FAQ)
코딩과 복잡한 추론에는 Kimi K2.6와 Kimi K2.5 중 어느 모델이 더 나은가요?+
종합 지능 지수 및 코딩 벤치마크에서는 Kimi K2.6가 우위를 보입니다. 상단의 SWE-bench 및 GPQA 점수를 함께 확인해 보세요.
Kimi K2.6와 Kimi K2.5의 API 요금 차이는 얼마인가요?+
Kimi K2.6는 100만 토큰당 입력 $0.00 / 출력 $0.00이며, Kimi K2.5는 입력 $0.00 / 출력 $0.00입니다. 혼합 비용 기준으로는 Kimi K2.6가 더 저렴합니다.
어느 모델이 더 큰 컨텍스트 윈도우와 빠른 속도를 제공하나요?+
컨텍스트 길이는 Kimi K2.6가 262.1K 토큰, Kimi K2.5가 262.1K 토큰를 지원하며, 출력 속도 면에서는 Kimi K2.6가 더 빠릅니다.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Kimi K2.5 vs Kimi K2 Thinking: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Kimi K2.5 vs MiniMax-M2.7: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Kimi K2.6 vs Qwen3.6 35B-A3B: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Aion-3.0 vs Aion-Mini: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Aion-3.0 vs Gemini 3.6 Flash: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Aion-Mini vs Laguna XS 2.1: 벤치마크, API 요금 및 속도 비교 (2026)비교
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
공식 출처: Moonshot AI 및 Moonshot AI 공식 API 문서, 시스템 카드 및 독립 벤치마크 평가 (2026).