Gemini 3.5 Flash vs Gemini Deep Research
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
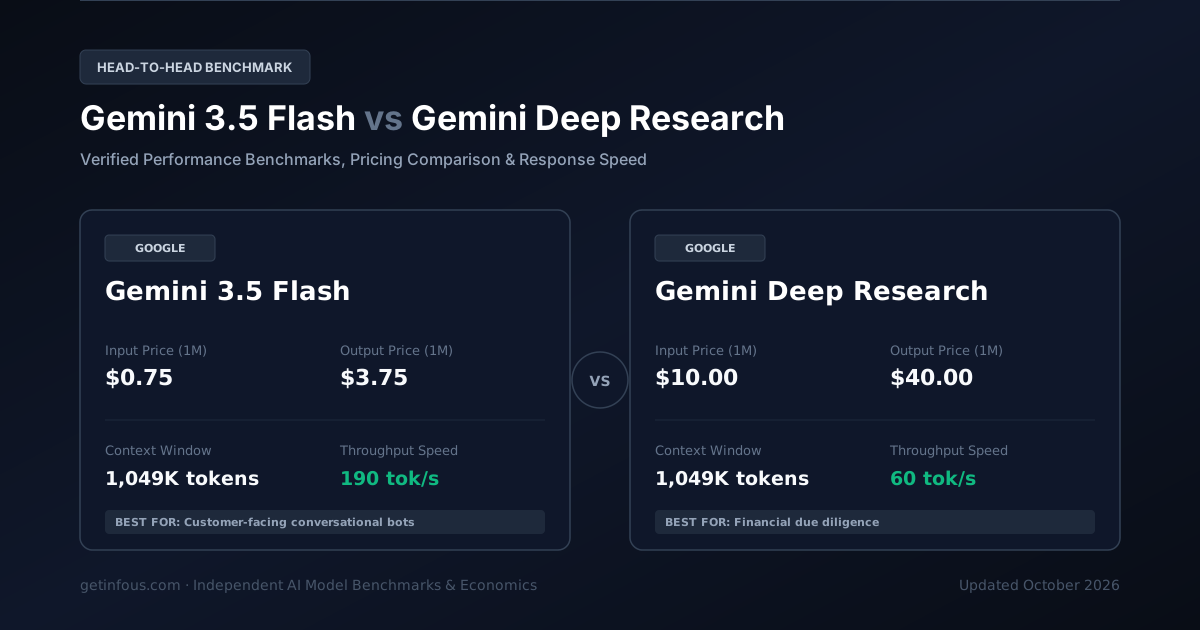
GoogleのGemini 3.5 FlashとGoogleのGemini Deep Researchは、注目度の高い主要AIモデルです。Gemini 3.5 Flashは1.05M トークンのコンテキストウィンドウを備え、API料金は100万トークンあたり入力$0.75/出力$3.75、一方のGemini Deep Researchは1.05M トークンのコンテキストで入力$10.00/出力$40.00です。以下でベンチマーク、速度、コストを詳しく比較します。
任意のAIモデルを切り替えて比較
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Gemini 3.5 Flash
フラッグシップ最先端モデルGoogle の Gemini 3.5 Flash は、最先端のエンタープライズ推論、ソフトウェア工学、ミッションクリティカルな本番運用向けに設計されたAIモデルです。1.0M のコンテキストウィンドウ、毎秒 190 トークンの生成速度、知能指数 82/100(1Mトークンあたり入力$0.75・出力$3.75)を実現しています。
$0.75 / 1M
$3.75 / 1M
1.05M tokens
70.2%
Gemini Deep Research
自律型エージェント・ツール特化Google の Gemini Deep Research は、自律型AIエージェントの実行、ツール呼び出し(Tool Calling)、複雑な業務自動化向けに設計されたAIモデルです。1.0M のコンテキストウィンドウ、毎秒 60 トークンの生成速度、知能指数 91/100(1Mトークンあたり入力$10・出力$40)を実現しています。
$10.00 / 1M
$40.00 / 1M
1.05M tokens
N/A
ひと目でわかる主な違い
- Gemini 3.5 Flash is 11.5x cheaper for API usage (input + output tokens combined).
- Gemini 3.5 Flash is faster at 190 tok/s vs 60 tok/s.
| Feature | Gemini 3.5 Flash | Gemini Deep Research |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 82 | 91 |
Provider | ||
Input Price Cost per million input tokens | $0.75 / 1M | $10.00 / 1M |
Output Price Cost per million output tokens | $3.75 / 1M | $40.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.66 / 1M | $7.75 / 1M |
Context Window Maximum input + output tokens | 1.05M tokens~1,573 A4 pages of text | 1.05M tokens~1,573 A4 pages of text |
Max Output Tokens Per single request | 66K | 66K |
Throughput Speed Tokens generated per second | 190 tok/s | 60 tok/s |
SWE-bench Verified Real-world software engineering | 70.2% | N/A |
GPQA Diamond Graduate-level reasoning | 81% | 85% |
Cached Input Price Prompt caching discount per 1M tokens | $0.19 / 1M | $2.50 / 1M |
分野別勝者スコアカード
At-a-glance decision frameworkEvaluations ongoing
検証済みベンチマークスコア比較
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Tokens emitted per second during active generation streaming.
レイテンシ&応答時間
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
リアルタイムAPIトークン料金シミュレーター
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Gemini 3.5 Flash · Strengths & Key Advantages
- 1.0M のコンテキストウィンドウと最大 66K トークンの出力容量(SWE-bench Verified 70.2% · GPQA Diamond 81%)
- 毎秒 190 トークンの高速スループットと、初回トークン到達時間(TTFT)わずか 360ms の低遅延
- 優れたAPI経済性(1Mトークンあたり入力$0.75・出力$3.75)に加え、プロンプトキャッシュや構造化JSON出力・関数呼び出しに完全対応
Considerations & Trade-offs
- クラウド専用のプロプライエタリモデルのため、モデル重みをダウンロードしてオフライン実行することはできません
- 極めて高度な専門科学の証明問題では、上位の大型推論特化モデルの方がより深い洞察を提供する場合があります
Gemini Deep Research · Strengths & Key Advantages
- 1.0M のコンテキストウィンドウと最大 66K トークンの出力容量(GPQA Diamond 85% · MMLU-Pro 89.5%)
- 毎秒 60 トークンの高速スループットと、初回トークン到達時間(TTFT)わずか 1500ms の低遅延
- 優れたAPI経済性(1Mトークンあたり入力$10・出力$40)に加え、プロンプトキャッシュや構造化JSON出力・関数呼び出しに完全対応
Considerations & Trade-offs
- クラウド専用のプロプライエタリモデルのため、モデル重みをダウンロードしてオフライン実行することはできません
- 大量のトークンを処理する本番環境では、プロンプトキャッシュや Batch API の併用によるコスト最適化が推奨されます
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Gemini 3.5 Flash | Gemini Deep Research |
|---|---|---|
Cost per Task Estimated USD to finish one task | $1.05 | $8.50 |
Output Tokens / Task Tokens generated per task | 38K | 50K |
Reasoning Tokens / Task Thinking tokens burned per task | 18K | 35K |
技術仕様・スペック
Architecture, release timeline, capabilities, and modalities.
| Feature | Gemini 3.5 Flash | Gemini Deep Research |
|---|---|---|
| Official API Model ID (SDK) | models/gemini-3-5-flash | models/gemini-deep-research |
| API Protocol | Google Gemini API (generateContent) + OpenAI-Compatible SDK | Google Gemini API (generateContent) + OpenAI-Compatible SDK |
| Release Date | 2026-05 | 2026-04 |
| Knowledge Cutoff | January 2026 | Real-time Google Search Integration |
| Architecture | Optimized Search-Grade Multimodal MoE | Agentic recursive research and synthesis engine |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 4,000,000 – 10,000,000 TPM | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 4,000,000 – 10,000,000 TPM |
| Long-Context Tier (>128K/200K) | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens |
| Prompt Cache Policy & TTL | Implicit + Explicit Context Caching at $0.1875/1M with configurable TTL | Implicit + Explicit Context Caching at $2.5/1M with configurable TTL |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox |
| Official Fine-Tuning Support | Vertex AI Supervised Adapter Tuning & Context Distillation | Vertex AI Supervised Adapter Tuning & Context Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) · Audio (~25–32 tokens/sec) · Video (~258–300 tokens/sec) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Google DeepMind Frontier Safety Framework Verified | Google DeepMind Frontier Safety Framework Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision, audio, video | text, vision |
| Output Modalities | text | text |
Gemini 3.5 Flash vs Gemini Deep Research: よくある質問 (FAQ)
Which is more intelligent, Gemini 3.5 Flash or Gemini Deep Research?
Gemini Deep Research is more intelligent. It scores 91 compared with 82 on the composite Intelligence Index.
Which model is faster?
Gemini 3.5 Flash is faster, generating 190 tokens per second compared with 60 tokens per second.
Which model is cheaper to run?
Gemini 3.5 Flash is cheaper at $0.66 per 1M tokens blended, compared with $7.75 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Gemini 3.5 Flash has lower latency, with a time to first token of 0.36s compared with 1.50s.
総合評価
Gemini 3.5 Flash(最先端のエンタープライズ推論、ソフトウェア工学、ミッションクリティカルな本番運用、エンタープライズRAG基盤、スケーラブルな本番API統合に最適。)とGemini Deep Research(自律型AIエージェントの実行、ツール呼び出し(Tool Calling)、複雑な業務自動化、エンタープライズRAG基盤、スケーラブルな本番API統合に最適。)はいずれも優れた選択肢です。高度な推論・コーディング精度ではGemini Deep Researchがリードし、応答速度とスループットではGemini 3.5 Flashが優れ、APIコスト効率ではGemini 3.5 Flashが有利です。
よくある質問 (FAQ)
コーディングや複雑な推論には Gemini 3.5 Flash と Gemini Deep Research のどちらが適していますか?+
総合知能指数およびコーディング評価では Gemini Deep Research が優位です。上部の SWE-bench や GPQA スコアもあわせてご確認ください。
Gemini 3.5 Flash と Gemini Deep Research ではどちらのAPI料金が安いですか?+
Gemini 3.5 Flash は100万トークンあたり入力$0.75 / 出力$3.75、Gemini Deep Research は入力$10.00 / 出力$40.00です。総合的なコスト効率では Gemini 3.5 Flash がより経済的です。
コンテキスト長と生成速度はどちらが優れていますか?+
コンテキストウィンドウは Gemini 3.5 Flash が 1.05M トークン、Gemini Deep Research が 1.05M トークン です。出力スピード(トークン/秒)では Gemini 3.5 Flash がリードしています。
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Gemini 3.8 Flash vs Gemini 3.5 Flash:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- o3-deep-research vs Gemini Deep Research:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- o4-mini-deep-research vs Gemini Deep Research:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Aion-3.0 vs Aion-Mini:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Aion-3.0 vs Gemini 3.6 Flash:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Aion-Mini vs Laguna XS 2.1:ベンチマーク・API料金・速度の徹底比較 (2026)比較
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
公的ソース: GoogleおよびGoogle公式APIドキュメント、システムカード、独立ベンチマーク評価 (2026)。