Grok 4.20 (Non-Reasoning) vs Grok 2
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
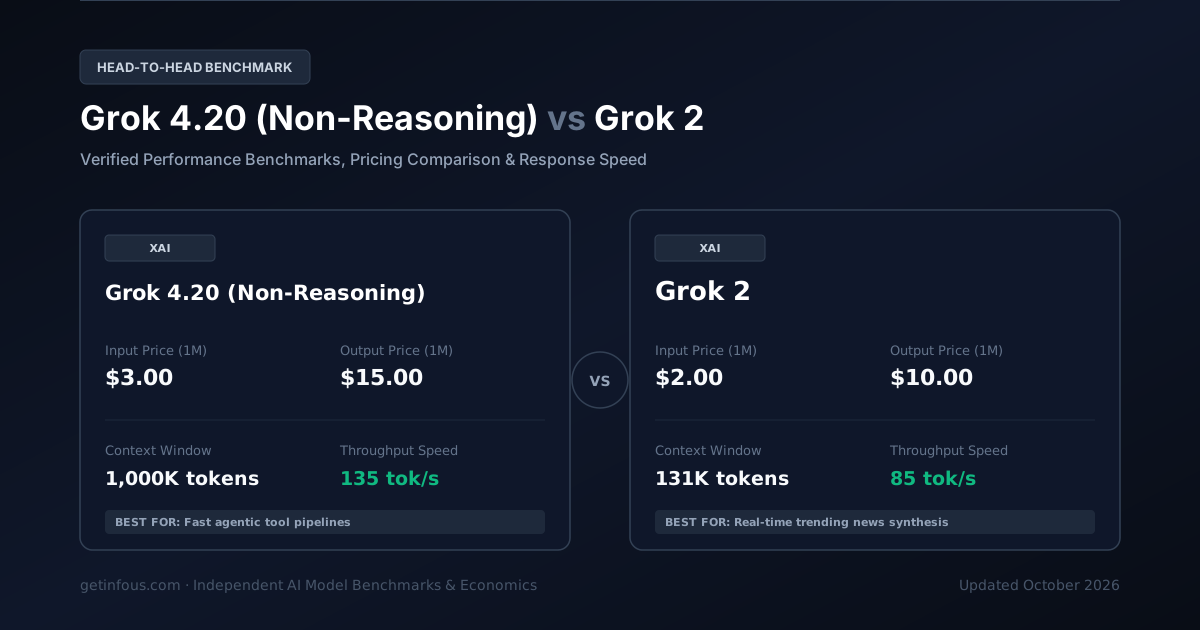
Grok 4.20 (Non-Reasoning) by xAI and Grok 2 by xAI represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Grok 2 holds a notable pricing advantage for token ingestion. On output generation, Grok 2 is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, Grok 4.20 (Non-Reasoning) provides an expanded memory horizon with 1,000K tokens. In latency-sensitive production environments, Grok 4.20 (Non-Reasoning) leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Switch & Compare Any Models
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Grok 4.20 (Non-Reasoning)
Fast AgenticFast, direct Grok model built for responsive agentic tool calling, fast coding, and real-time live assistance without reasoning latency.
$3.00 / 1M
$15.00 / 1M
1M tokens
61.5%
Grok 2
Colossus Supercluster FlagshipState-of-the-art conversational and visual reasoning model trained on the Colossus 100K H100 cluster, integrating Flux image generation and real-time live data.
$2.00 / 1M
$10.00 / 1M
131.1K tokens
36.5%
Key Differences at a Glance
- Grok 2 is 1.4x cheaper for API usage (input + output tokens combined).
- Grok 4.20 (Non-Reasoning) has a larger context window (1M vs 131K tokens).
- Grok 4.20 (Non-Reasoning) is faster at 135 tok/s vs 85 tok/s.
- Grok 4.20 (Non-Reasoning) leads on SWE-bench coding (61.5% vs 36.5%).
| Feature | Grok 4.20 (Non-Reasoning) | Grok 2 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 62 | 45 |
Provider | xAI | xAI |
Input Price Cost per million input tokens | $3.00 / 1M | $2.00 / 1M |
Output Price Cost per million output tokens | $15.00 / 1M | $10.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $2.63 / 1M | $2.10 / 1M |
Context Window Maximum input + output tokens | 1M tokens~1,500 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 66K | 8K |
Throughput Speed Tokens generated per second | 135 tok/s | 85 tok/s |
SWE-bench Verified Real-world software engineering | 61.5% | 36.5% |
GPQA Diamond Graduate-level reasoning | 65.4% | 56% |
Cached Input Price Prompt caching discount per 1M tokens | $0.75 / 1M | $1.00 / 1M |
Who Wins Where?
At-a-glance decision frameworkEmpirical Head-to-Head Benchmark Scores
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
Latency & Response Time
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Real-Time Interactive Token Cost Simulator
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Grok 4.20 (Non-Reasoning) · Strengths & Key Advantages
- Blazing-fast response time with 135 tokens/sec throughput and 420ms time-to-first-token
- Full 1M-token context window without reasoning token overhead
- Precise structured JSON outputs and reliable external tool calling
- Native visual multimodal ingestion
Considerations & Trade-offs
- Lacks extended chain-of-thought verification for multi-stage math and logic proofs
- Can struggle with nuanced multi-step code refactoring without external linters
Grok 2 · Strengths & Key Advantages
- Trained on Memphis Colossus cluster — one of the world’s largest supercomputers
- Top-tier Chatbot Arena Elo (1295) rivaling GPT-4o and Claude 3.5 Sonnet
- Strong visual comprehension and diagram analysis
Considerations & Trade-offs
- API ecosystem younger than OpenAI or Anthropic
- Output tokens capped at 8K
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Grok 4.20 (Non-Reasoning) | Grok 2 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.88 | $0.20 |
Output Tokens / Task Tokens generated per task | 35K | 24K |
Reasoning Tokens / Task Thinking tokens burned per task | 0K | 0K |
Technical Specifications
Architecture, release timeline, capabilities, and modalities.
| Feature | Grok 4.20 (Non-Reasoning) | Grok 2 |
|---|---|---|
| Official API Model ID (SDK) | grok-4-20-non-reasoning-latest | grok-2-latest |
| API Protocol | xAI REST API (OpenAI-Compatible) | xAI REST API (OpenAI-Compatible) |
| Release Date | 2026-03 | 2024-08 |
| Knowledge Cutoff | November 2025 | August 2024 |
| Architecture | Colossus-Scale Sparse MoE | Frontier Multimodal Mixture-of-Experts |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 5,000 – 15,000 RPM (Production Tier) · 4,000,000 – 10,000,000 TPM | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($3/1M in) across full 1000K window | Flat rate ($2/1M in) across full 131K window |
| Prompt Cache Policy & TTL | Cached input at $0.75/1M tokens | Cached input at $1/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Real-time Web & X (Twitter) Search Grounding + Code Execution | Real-time Web & X (Twitter) Search Grounding + Code Execution |
| Official Fine-Tuning Support | API Prompt Engineering & RAG Distillation | API Prompt Engineering & RAG Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | xAI Production Safety & Alignment Verified | xAI Production Safety & Alignment Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Grok 4.20 (Non-Reasoning) vs Grok 2: Quick Answers
Which is more intelligent, Grok 4.20 (Non-Reasoning) or Grok 2?
Grok 4.20 (Non-Reasoning) is more intelligent. It scores 62 compared with 45 on the composite Intelligence Index.
Which model is faster?
Grok 4.20 (Non-Reasoning) is faster, generating 135 tokens per second compared with 85 tokens per second.
Which model is cheaper to run?
Grok 2 is cheaper at $2.10 per 1M tokens blended, compared with $2.63 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Grok 4.20 (Non-Reasoning) has lower latency, with a time to first token of 0.42s compared with 0.48s.
Which model has a larger context window?
Grok 4.20 (Non-Reasoning) has a larger context window, supporting 1M tokens compared with 131.1K tokens.
Verdict
Verdict & Model Selection Recommendation: Choose Grok 4.20 (Non-Reasoning) if your priority is Fast agentic tool pipelines, real-time interactive chat, and high-throughput document extraction. Its performance in demanding tasks justifies its operational token cost. Choose Grok 2 if your workflow prioritizes Real-time trending news synthesis, visual STEM reasoning, and interactive X applications. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Frequently asked questions
How does Grok 4.20 (Non-Reasoning) compare to Grok 2 in API token pricing and cost per token?+
Grok 4.20 (Non-Reasoning) costs $3.00 per 1M input tokens and $15.00 per 1M output tokens, whereas Grok 2 costs $2.00 input and $10.00 output. Overall, Grok 2 is the more cost-effective model for high-volume API pipelines. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: Grok 4.20 (Non-Reasoning) or Grok 2?+
Grok 4.20 (Non-Reasoning) supports a context window of 1,000K tokens (~750k words), while Grok 2 supports 131K tokens (~98k words). Therefore, Grok 4.20 (Non-Reasoning) can process more textual data and document context in a single prompt.
Which AI model is better for software engineering and coding: Grok 4.20 (Non-Reasoning) or Grok 2?+
Grok 4.20 (Non-Reasoning) scores 61.5% on SWE-bench Verified while Grok 2 scores 36.5%. For autonomous software engineering and multi-file debugging, Grok 4.20 (Non-Reasoning) holds the verified benchmark lead.
What is the difference in reasoning capability and extended thinking between Grok 4.20 (Non-Reasoning) and Grok 2?+
Grok 4.20 (Non-Reasoning) is optimized for low-latency direct generation. In contrast, Grok 2 focuses on standard fast inference.
How does inference speed (tokens per second) compare between Grok 4.20 (Non-Reasoning) and Grok 2?+
Grok 4.20 (Non-Reasoning) generates approximately 135 tokens per second, while Grok 2 delivers 85 tokens per second. In latency-sensitive production environments, Grok 4.20 (Non-Reasoning) provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Grok 4.20 (Non-Reasoning) and Grok 2 to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Grok 2 to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Grok 4.20 (Non-Reasoning). This tiered routing pattern cuts overall API bills by up to 70%.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Grok 2 vs GPT-4o: Benchmarks, Pricing & Speed ComparisonCompare
- Grok 4.20 (Non-Reasoning) vs GPT-4.1: Benchmarks, Pricing & Speed ComparisonCompare
- Solar Pro vs Grok 2: Benchmarks, Pricing & Speed ComparisonCompare
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed ComparisonCompare
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed ComparisonCompare
- Aion-Mini vs Laguna XS 2.1: Benchmarks, Pricing & Speed ComparisonCompare
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Sources: GetInfoUs Independent AI Benchmarks & Official API Specs