ERNIE Speed vs ERNIE Lite
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
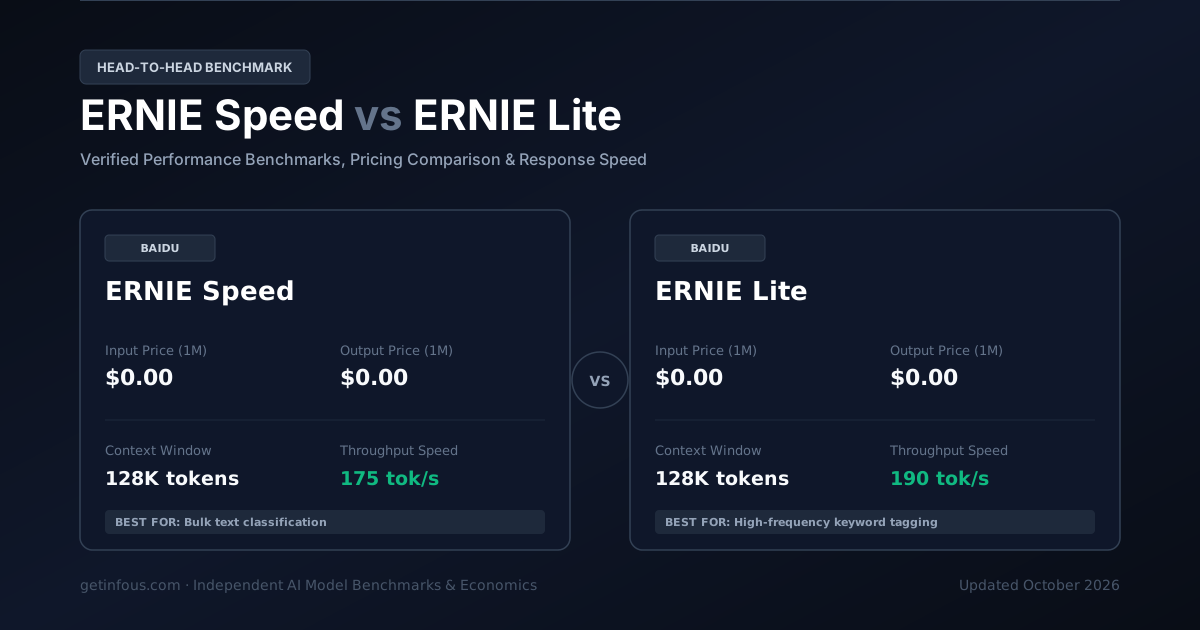
ERNIE Speed by Baidu and ERNIE Lite by Baidu represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, both models offer identical input token rates. On output generation, costs are matched. In data-heavy architectures requiring extensive repository or document analysis, both models provide an identical memory horizon with 128K tokens. In latency-sensitive production environments, ERNIE Lite leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
Switch & Compare Any Models
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
ERNIE Speed
Fast BudgetFast, free-tier accessible language model offering rapid response generation for bulk processing and entry-level automation.
$0.00 / 1M
$0.00 / 1M
128K tokens
N/A
ERNIE Lite
Cheapest ERNIEBaidu smallest language model engineered for minimal memory consumption, high streaming throughput, and high-volume background jobs.
$0.00 / 1M
$0.00 / 1M
128K tokens
N/A
Key Differences at a Glance
- Both models cost the same under this workload — choose on capability, not price.
- ERNIE Lite is faster at 190 tok/s vs 175 tok/s.
| Feature | ERNIE Speed | ERNIE Lite |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 68 | 65 |
Provider | Baidu | Baidu |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 128K tokens~192 A4 pages of text | 128K tokens~192 A4 pages of text |
Max Output Tokens Per single request | 4K | 4K |
Throughput Speed Tokens generated per second | 175 tok/s | 190 tok/s |
SWE-bench Verified Real-world software engineering | N/A | N/A |
Who Wins Where?
At-a-glance decision frameworkEvaluations ongoing
Empirical Head-to-Head Benchmark Scores
Official evaluation metrics verified by independent third-party research labs.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
Latency & Response Time
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Real-Time Interactive Token Cost Simulator
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
ERNIE Speed · Strengths & Key Advantages
- Free of charge on Baidu Qianfan API for registered developers
- Sub-250ms initial token generation and fast 175 tokens/sec throughput
- Adequate accuracy for standard text summarization and sentiment tagging
Considerations & Trade-offs
- Limited analytical depth on complex technical or scientific problems
- Max output token ceiling of 4096 tokens
ERNIE Lite · Strengths & Key Advantages
- Completely free tier access on Baidu Qianfan platform
- Blazing fast generation exceeding 190 tokens per second
- Minimal resource footprint suitable for embedded edge devices
Considerations & Trade-offs
- Low accuracy on subtle linguistic nuances or complex multi-step reasoning
- High rate of hallucination when pushed beyond straightforward facts
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | ERNIE Speed | ERNIE Lite |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 8K | 6K |
Reasoning Tokens / Task Thinking tokens burned per task | 0K | 0K |
Technical Specifications
Architecture, release timeline, capabilities, and modalities.
| Feature | ERNIE Speed | ERNIE Lite |
|---|---|---|
| Official API Model ID (SDK) | ernie-speed | ernie-lite |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2024-03 | 2024-03 |
| Knowledge Cutoff | December 2023 | December 2023 |
| Architecture | Distilled High-Throughput Transformer | Ultra-Lightweight Edge-Ready Transformer |
| Parameters | Confidential / 8B Scale | Confidential / 3B Scale |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 5 GB VRAM (4-bit Quantized) · 17 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 2 GB VRAM (4-bit Quantized) · 6 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text | text |
| Output Modalities | text | text |
ERNIE Speed vs ERNIE Lite: Quick Answers
Which is more intelligent, ERNIE Speed or ERNIE Lite?
ERNIE Speed is more intelligent. It scores 68 compared with 65 on the composite Intelligence Index.
Which model is faster?
ERNIE Lite is faster, generating 190 tokens per second compared with 175 tokens per second.
Which model has lower latency?
ERNIE Lite has lower latency, with a time to first token of 0.20s compared with 0.23s.
Verdict
Verdict & Model Selection Recommendation: Choose ERNIE Speed if your priority is Bulk text classification, simple conversational routing, and zero-cost prototyping. Its performance in demanding tasks justifies its operational token cost. Choose ERNIE Lite if your workflow prioritizes High-frequency keyword tagging, basic intent routing, and embedded device NLP. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
Frequently asked questions
How does ERNIE Speed compare to ERNIE Lite in API token pricing and cost per token?+
Both ERNIE Speed and ERNIE Lite are open-weights foundation models available at $0.00 direct API cost when self-hosted, or offered at identical baseline rates across major inference providers. Model selection depends on GPU deployment sizing and specialized benchmark performance rather than raw token price.
Which model has a larger context window: ERNIE Speed or ERNIE Lite?+
Both ERNIE Speed and ERNIE Lite offer an identical context window of 128K tokens (~96k words). Both architectures provide equal capacity for large document ingestion, multi-file codebases, and extended multi-turn conversation histories.
Which AI model is better for software engineering and coding: ERNIE Speed or ERNIE Lite?+
ERNIE Speed scores at the frontier of coding benchmarks, while ERNIE Lite scores competitively for software generation. For complex autonomous debugging and agentic engineering, ERNIE Speed provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between ERNIE Speed and ERNIE Lite?+
ERNIE Speed is optimized for low-latency direct generation. In contrast, ERNIE Lite focuses on standard fast inference.
How does inference speed (tokens per second) compare between ERNIE Speed and ERNIE Lite?+
ERNIE Speed generates approximately 175 tokens per second, while ERNIE Lite delivers 190 tokens per second. In latency-sensitive production environments, ERNIE Lite provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining ERNIE Speed and ERNIE Lite to optimize costs?+
Yes! Tiered multi-model routing can optimize for latency and accuracy: you can route high-frequency conversational turns and latency-sensitive queries to ERNIE Lite, and route deep architectural or complex reasoning queries to ERNIE Speed. This balanced routing strategy maximizes system throughput and answer quality.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- DBRX Instruct vs ERNIE Lite: Benchmarks, Pricing & Speed ComparisonCompare
- DBRX Instruct vs ERNIE Speed: Benchmarks, Pricing & Speed ComparisonCompare
- ERNIE Lite vs Gemma 2: Benchmarks, Pricing & Speed ComparisonCompare
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed ComparisonCompare
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed ComparisonCompare
- Aion-Mini vs Laguna XS 2.1: Benchmarks, Pricing & Speed ComparisonCompare
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Sources: GetInfoUs Independent AI Benchmarks & Official API Specs