Gemma 4 E4B vs Gemma 4 E2B
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
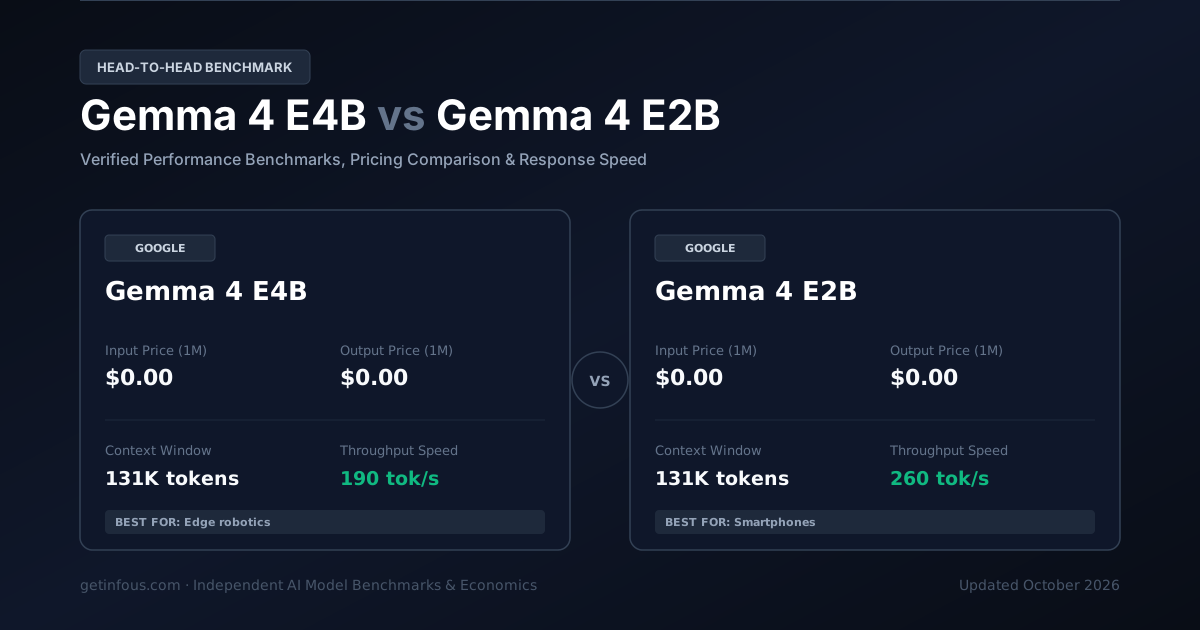
Gemma 4 E4B von Google und Gemma 4 E2B von Google gehören zu den führenden KI-Modellen. Gemma 4 E4B bietet ein Kontextfenster von 131.1K Tokens bei API-Preisen von $0.00/$0.00 pro 1M Tokens, während Gemma 4 E2B 131.1K Tokens Kontext zu $0.00/$0.00 pro 1M Tokens bereitstellt. Hier finden Sie den vollständigen Benchmark-, Latenz- und Kostenvergleich.
Beliebige Modelle wechseln & vergleichen
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Gemma 4 E4B
Open-Weights-BasismodellGemma 4 E4B von Google ist ein KI-Modell für Self-Hosting im eigenen Rechenzentrum, Fine-Tuning und volle Datensouveränität mit 131K Kontextfenster, 190 Token/s Durchsatz, einem Intelligenz-Index von 65/100 und kostenlosem Open-Weights-Zuga
$0.00 / 1M
$0.00 / 1M
131.1K tokens
N/A
Gemma 4 E2B
Open-Weights-BasismodellGemma 4 E2B von Google ist ein KI-Modell für Self-Hosting im eigenen Rechenzentrum, Fine-Tuning und volle Datensouveränität mit 131K Kontextfenster, 260 Token/s Durchsatz, einem Intelligenz-Index von 55/100 und kostenlosem Open-Weights-Zuga
$0.00 / 1M
$0.00 / 1M
131.1K tokens
N/A
Wichtigste Unterschiede auf einen Blick
- Both models cost the same under this workload — choose on capability, not price.
- Gemma 4 E2B is faster at 260 tok/s vs 190 tok/s.
| Feature | Gemma 4 E4B | Gemma 4 E2B |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 65 | 55 |
Provider | ||
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 131.1K tokens~197 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 16K | 8K |
Throughput Speed Tokens generated per second | 190 tok/s | 260 tok/s |
SWE-bench Verified Real-world software engineering | N/A | N/A |
Wer gewinnt in welcher Disziplin?
At-a-glance decision frameworkEvaluations ongoing
Geprüfte Benchmark-Ergebnisse im Vergleich
Official evaluation metrics verified by independent third-party research labs.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
Latenz & Antwortzeit
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Interaktiver Token-Kosten-Simulator
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Gemma 4 E4B · Strengths & Key Advantages
- 131K Kontextfenster und bis zu 16K maximale Output-Token (MMLU-Pro 74% · Arena Elo 1320)
- Hohe Generierungsgeschwindigkeit von 190 Token/Sekunde bei nur 220 ms Erstlatenz (TTFT)
- Offene Modellgewichte (E4B (4B)) für lokales Self-Hosting und Fine-Tuning über vLLM, SGLang oder Ollama
Considerations & Trade-offs
- Erfordert dedizierte GPU-Hardware mit ausreichend VRAM für den lokalen Betrieb in voller Präzision
- Bei extrem komplexen mehrstufigen Forschungsfragen bieten schwere Reasoning-Spezialmodelle noch tiefere Analysen
Gemma 4 E2B · Strengths & Key Advantages
- 131K Kontextfenster und bis zu 8K maximale Output-Token (MMLU-Pro 67.2% · Arena Elo 1260)
- Hohe Generierungsgeschwindigkeit von 260 Token/Sekunde bei nur 180 ms Erstlatenz (TTFT)
- Offene Modellgewichte (E2B (2B)) für lokales Self-Hosting und Fine-Tuning über vLLM, SGLang oder Ollama
Considerations & Trade-offs
- Erfordert dedizierte GPU-Hardware mit ausreichend VRAM für den lokalen Betrieb in voller Präzision
- Bei extrem komplexen mehrstufigen Forschungsfragen bieten schwere Reasoning-Spezialmodelle noch tiefere Analysen
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Gemma 4 E4B | Gemma 4 E2B |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 4K | 2K |
Reasoning Tokens / Task Thinking tokens burned per task | 1K | 1K |
Technische Spezifikationen
Architecture, release timeline, capabilities, and modalities.
| Feature | Gemma 4 E4B | Gemma 4 E2B |
|---|---|---|
| Official API Model ID (SDK) | models/gemma-4-e4b | models/gemma-4-e2b |
| API Protocol | Google Gemini API (generateContent) + OpenAI-Compatible SDK | Google Gemini API (generateContent) + OpenAI-Compatible SDK |
| Release Date | 2026-04 | 2026-04 |
| Knowledge Cutoff | January 2026 | January 2026 |
| Architecture | Edge-optimized dense open transformer | Ultra-compact edge transformer |
| Parameters | E4B (4B) | E2B (2B) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 2 GB VRAM (4-bit Quantized) · 9 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 2 GB VRAM (4-bit Quantized) · 4 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Google DeepMind Frontier Safety Framework Verified | Google DeepMind Frontier Safety Framework Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Gemma 4 E4B vs Gemma 4 E2B: Schnelle Antworten (FAQ)
Which is more intelligent, Gemma 4 E4B or Gemma 4 E2B?
Gemma 4 E4B is more intelligent. It scores 65 compared with 55 on the composite Intelligence Index.
Which model is faster?
Gemma 4 E2B is faster, generating 260 tokens per second compared with 190 tokens per second.
Which model has lower latency?
Gemma 4 E2B has lower latency, with a time to first token of 0.18s compared with 0.22s.
Fazit
Sowohl Gemma 4 E4B (Optimal für Self-Hosting im eigenen Rechenzentrum, Fine-Tuning und volle Datensouveränität, Enterprise-RAG-Systeme und skalierbare API-Pipelines.) als auch Gemma 4 E2B (Optimal für Self-Hosting im eigenen Rechenzentrum, Fine-Tuning und volle Datensouveränität, Enterprise-RAG-Systeme und skalierbare API-Pipelines.) überzeugen im Produktionseinsatz: Gemma 4 E4B führt bei komplexem Reasoning und Coding, Gemma 4 E2B liefert den höheren Token-Durchsatz und Gemma 4 E4B ist die kosteneffizienteste Wahl für große API-Workloads.
Häufig gestellte Fragen (FAQ)
Welches Modell ist besser für Coding und Reasoning – Gemma 4 E4B oder Gemma 4 E2B?+
Im Gesamt-Intelligenzindex und bei Software-Benchmarks liegt Gemma 4 E4B vorn. Prüfen Sie oben die SWE-bench- und GPQA-Werte für Ihren Anwendungsfall.
Wie unterscheiden sich die API-Preise von Gemma 4 E4B und Gemma 4 E2B?+
Gemma 4 E4B kostet $0.00 / $0.00 pro 1M Input-/Output-Tokens, Gemma 4 E2B liegt bei $0.00 / $0.00. Beim gewichteten Gesamtpreis ist Gemma 4 E4B günstiger.
Welches Modell hat das größere Kontextfenster und die höhere Geschwindigkeit?+
Gemma 4 E4B bietet 131.1K Tokens Kontext gegenüber 131.1K Tokens bei Gemma 4 E2B. Bei der Generierungsgeschwindigkeit liegt Gemma 4 E2B vorn.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- DeepSeek V4 vs. Gemma 4 E2B: Benchmarks, API-Preise & Geschwindigkeit im Vergleich (2026)Vergleich
- Gemma 4 E2B vs. Gemma 4 31B: Benchmarks, API-Preise & Geschwindigkeit im Vergleich (2026)Vergleich
- Gemma 4 E4B vs. Hy3 preview: Benchmarks, API-Preise & Geschwindigkeit im Vergleich (2026)Vergleich
- Aion-3.0 vs. Aion-Mini: Benchmarks, API-Preise & Geschwindigkeit im Vergleich (2026)Vergleich
- Aion-3.0 vs. Gemini 3.6 Flash: Benchmarks, API-Preise & Geschwindigkeit im Vergleich (2026)Vergleich
- Aion-Mini vs. Laguna XS 2.1: Benchmarks, API-Preise & Geschwindigkeit im Vergleich (2026)Vergleich
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Offizielle Quellen: Offizielle API-Dokumentation von Google und Google, Systemkarten und unabhängige Benchmark-Auswertungen (2026).