Nemotron 3 Nano Omni 30B A3B Reasoning vs Mistral Small 4
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
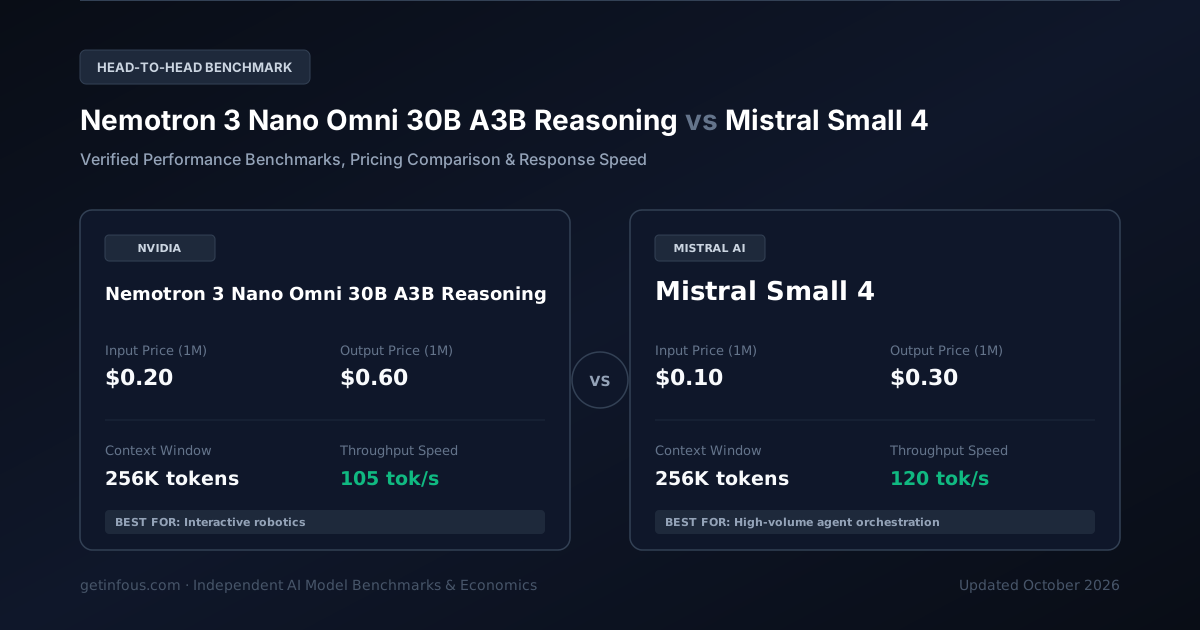
Nemotron 3 Nano Omni 30B A3B Reasoning by NVIDIA and Mistral Small 4 by Mistral AI represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, Mistral Small 4 holds a notable pricing advantage for token ingestion. On output generation, Mistral Small 4 is more economical per million generated tokens. In data-heavy architectures requiring extensive repository or document analysis, both models provide an identical memory horizon with 256K tokens. In latency-sensitive production environments, Mistral Small 4 leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
切换并对比任意模型
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Nemotron 3 Nano Omni 30B A3B Reasoning
开源权重模型NVIDIA 推出的 Nemotron 3 Nano Omni 30B A3B Reasoning 人工智能模型,具备 256K 上下文窗口,输入价格为 $0.2/百万 Token,输出价格为 $0.6/百万 Token,专为高质量生产环境、推理与自动化工作流打造。
$0.20 / 1M
$0.60 / 1M
256K tokens
42%
Mistral Small 4
开源权重模型Mistral AI 推出的 Mistral Small 4 人工智能模型,具备 256K 上下文窗口,输入价格为 $0.15/百万 Token,输出价格为 $0.6/百万 Token,专为高质量生产环境、推理与自动化工作流打造。
$0.10 / 1M
$0.30 / 1M
256K tokens
44.5%
核心差异一览
- Mistral Small 4 is 2.0x cheaper for API usage (input + output tokens combined).
- Mistral Small 4 is faster at 120 tok/s vs 105 tok/s.
- Mistral Small 4 leads on SWE-bench coding (44.5% vs 42.0%).
| Feature | Nemotron 3 Nano Omni 30B A3B Reasoning | Mistral Small 4 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 48 | 48 |
Provider | NVIDIA | Mistral AI |
Input Price Cost per million input tokens | $0.20 / 1M | $0.10 / 1M |
Output Price Cost per million output tokens | $0.60 / 1M | $0.30 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.14 / 1M | $0.07 / 1M |
Context Window Maximum input + output tokens | 256K tokens~384 A4 pages of text | 256K tokens~384 A4 pages of text |
Max Output Tokens Per single request | 16K | 16K |
Throughput Speed Tokens generated per second | 105 tok/s | 120 tok/s |
SWE-bench Verified Real-world software engineering | 42% | 44.5% |
GPQA Diamond Graduate-level reasoning | 56.5% | 56% |
Cached Input Price Prompt caching discount per 1M tokens | $0.05 / 1M | $0.03 / 1M |
各项指标谁更胜一筹?
At-a-glance decision framework权威基准测试得分对比
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
延迟与响应速度
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
实时 Token 成本模拟器
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Nemotron 3 Nano Omni 30B A3B Reasoning · Strengths & Key Advantages
- 由 NVIDIA 研发的高精度 Omnimodal Sparse MoE (30B Total / 3B Active) 架构,支持 256K 上下文窗口
- 极具竞争力的 API 定价(输入 $0.2/1M,输出 $0.6/1M),支持高速推理与工具调用
- 在代码生成、逻辑推理与多语言处理基准测试中表现出色
Considerations & Trade-offs
- 超长上下文请求需要规划 Token 成本与并发配额
- 针对特定垂直领域任务建议结合系统提示词与检索增强(RAG)以获得最佳效果
Mistral Small 4 · Strengths & Key Advantages
- 由 Mistral AI 研发的高精度 Next-Gen Compact Multimodal Transformer 架构,支持 256K 上下文窗口
- 极具竞争力的 API 定价(输入 $0.15/1M,输出 $0.6/1M),支持高速推理与工具调用
- 在代码生成、逻辑推理与多语言处理基准测试中表现出色
Considerations & Trade-offs
- 超长上下文请求需要规划 Token 成本与并发配额
- 针对特定垂直领域任务建议结合系统提示词与检索增强(RAG)以获得最佳效果
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Nemotron 3 Nano Omni 30B A3B Reasoning | Mistral Small 4 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.22 | $0.12 |
Output Tokens / Task Tokens generated per task | 28K | 28K |
Reasoning Tokens / Task Thinking tokens burned per task | 12K | 12K |
技术规格参数
Architecture, release timeline, capabilities, and modalities.
| Feature | Nemotron 3 Nano Omni 30B A3B Reasoning | Mistral Small 4 |
|---|---|---|
| Official API Model ID (SDK) | nemotron-3-nano-omni-30b-a3b | mistral-small-4-latest |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-04 | 2026-03 |
| Knowledge Cutoff | February 2026 | January 2026 |
| Architecture | Omnimodal Sparse MoE (30B Total / 3B Active) | Next-Gen Compact Multimodal Transformer |
| Parameters | 30B (3B active MoE) | 24B |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Flat rate ($0.2/1M in) across full 256K window | Flat rate ($0.1/1M in) across full 256K window |
| Prompt Cache Policy & TTL | Cached input at $0.05/1M tokens | Cached input at $0.03/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) · Audio (~25–32 tokens/sec) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 19 GB VRAM (4-bit Quantized) · 65 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 15 GB VRAM (4-bit Quantized) · 52 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision, audio | text, vision |
| Output Modalities | text | text |
Nemotron 3 Nano Omni 30B A3B Reasoning vs Mistral Small 4: 常见问题解答 (FAQ)
Which model is faster?
Mistral Small 4 is faster, generating 120 tokens per second compared with 105 tokens per second.
Which model is cheaper to run?
Mistral Small 4 is cheaper at $0.07 per 1M tokens blended, compared with $0.14 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Mistral Small 4 has lower latency, with a time to first token of 0.34s compared with 0.38s.
综合结论
Verdict & Model Selection Recommendation: Choose Nemotron 3 Nano Omni 30B A3B Reasoning if your priority is Interactive robotics, smart camera analysis, and multimodal customer kiosks. Its performance in demanding tasks justifies its operational token cost. Choose Mistral Small 4 if your workflow prioritizes High-volume agent orchestration, low-cost document parsing, and edge deployments. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
常见问题 (FAQ)
How does Nemotron 3 Nano Omni 30B A3B Reasoning compare to Mistral Small 4 in API token pricing and cost per token?+
Nemotron 3 Nano Omni 30B A3B Reasoning costs $0.20 per 1M input tokens and $0.60 per 1M output tokens, whereas Mistral Small 4 costs $0.10 input and $0.30 output. Overall, Mistral Small 4 is the more cost-effective model for high-volume API pipelines. Both models support prompt caching discounts of up to 90% for repeated prompt prefixes.
Which model has a larger context window: Nemotron 3 Nano Omni 30B A3B Reasoning or Mistral Small 4?+
Both Nemotron 3 Nano Omni 30B A3B Reasoning and Mistral Small 4 offer an identical context window of 256K tokens (~192k words). Both architectures provide equal capacity for large document ingestion, multi-file codebases, and extended multi-turn conversation histories.
Which AI model is better for software engineering and coding: Nemotron 3 Nano Omni 30B A3B Reasoning or Mistral Small 4?+
Nemotron 3 Nano Omni 30B A3B Reasoning scores 42% on SWE-bench Verified while Mistral Small 4 scores 44.5%. For autonomous software engineering and multi-file debugging, Mistral Small 4 holds the verified benchmark lead.
What is the difference in reasoning capability and extended thinking between Nemotron 3 Nano Omni 30B A3B Reasoning and Mistral Small 4?+
Nemotron 3 Nano Omni 30B A3B Reasoning features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, Mistral Small 4 provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between Nemotron 3 Nano Omni 30B A3B Reasoning and Mistral Small 4?+
Nemotron 3 Nano Omni 30B A3B Reasoning generates approximately 105 tokens per second, while Mistral Small 4 delivers 120 tokens per second. In latency-sensitive production environments, Mistral Small 4 provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining Nemotron 3 Nano Omni 30B A3B Reasoning and Mistral Small 4 to optimize costs?+
Yes! High-efficiency architectures route high-frequency routine classification and conversational tasks to Mistral Small 4 to save operational costs, and dynamically escalate complex architectural queries or reasoning tasks to Nemotron 3 Nano Omni 30B A3B Reasoning. This tiered routing pattern cuts overall API bills by up to 70%.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Gemma 4 31B vs Mistral Small 4: Benchmarks, Pricing & Speed Comparison对比
- Mistral Small 4 vs Claude Haiku 5.5: Benchmarks, Pricing & Speed Comparison对比
- Mistral Small 4 vs GPT-4.1 mini: Benchmarks, Pricing & Speed Comparison对比
- Nemotron 3 Nano Omni 30B A3B Reasoning vs Nemotron 3 Super 120B A12B: Benchmarks, Pricing & Speed Comparison对比
- Nemotron Cascade 2 30B A3B vs Mistral Small 4: Benchmarks, Pricing & Speed Comparison对比
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed Comparison对比
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
数据来源: GetInfoUs Independent AI Benchmarks & Official API Specs