Command A Plus vs Nemotron 3 Ultra 550B A55B
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
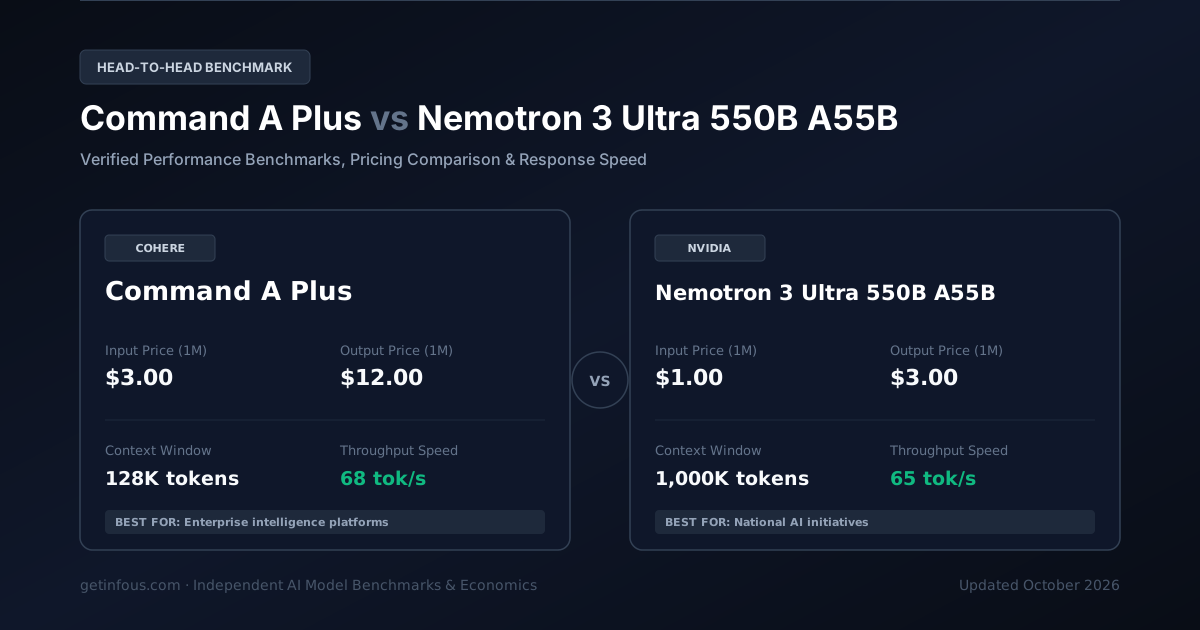
Cohere tarafından geliştirilen Command A Plus ve NVIDIA tarafından sunulan Nemotron 3 Ultra 550B A55B, kendi sınıflarının öne çıkan yapay zeka modelleridir. Command A Plus, 128K token bağlam penceresi ve 1M token başına $3.00/$12.00 fiyat sunarken; Nemotron 3 Ultra 550B A55B, 1M token bağlam penceresi ve $1.00/$3.00 fiyatla gelir. Aşağıda tüm benchmark, hız ve maliyet detaylarını inceleyebilirsiniz.
İstediğiniz Modelleri Seçin ve Karşılaştırın
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Command A Plus
Açık Ağırlıklı Temel ModelCohere tarafından geliştirilen Command A Plus; özel sunucuda kendi kendine barındırma (self-hosting), ince ayar ve tam veri egemenliği için tasarlanmış olup 128K bağlam penceresi, 68 token/sn hız, 58/100 zeka indeksi ve 1M token başına $3/$
$3.00 / 1M
$12.00 / 1M
128K tokens
60.5%
Nemotron 3 Ultra 550B A55B
Açık Ağırlıklı Temel ModelNVIDIA tarafından geliştirilen Nemotron 3 Ultra 550B A55B; özel sunucuda kendi kendine barındırma (self-hosting), ince ayar ve tam veri egemenliği için tasarlanmış olup 1M bağlam penceresi, 65 token/sn hız, 60/100 zeka indeksi ve 1M token b
$1.00 / 1M
$3.00 / 1M
1M tokens
64.5%
Bir Bakışta Temel Farklar
- Nemotron 3 Ultra 550B A55B is 3.6x cheaper for API usage (input + output tokens combined).
- Nemotron 3 Ultra 550B A55B has a larger context window (1M vs 128K tokens).
- Command A Plus is faster at 68 tok/s vs 65 tok/s.
- Nemotron 3 Ultra 550B A55B leads on SWE-bench coding (64.5% vs 60.5%).
| Feature | Command A Plus | Nemotron 3 Ultra 550B A55B |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 58 | 60 |
Provider | Cohere | NVIDIA |
Input Price Cost per million input tokens | $3.00 / 1M | $1.00 / 1M |
Output Price Cost per million output tokens | $12.00 / 1M | $3.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $2.33 / 1M | $0.68 / 1M |
Context Window Maximum input + output tokens | 128K tokens~192 A4 pages of text | 1M tokens~1,500 A4 pages of text |
Max Output Tokens Per single request | 33K | 66K |
Throughput Speed Tokens generated per second | 68 tok/s | 65 tok/s |
SWE-bench Verified Real-world software engineering | 60.5% | 64.5% |
GPQA Diamond Graduate-level reasoning | 74% | 76% |
Cached Input Price Prompt caching discount per 1M tokens | $0.75 / 1M | $0.25 / 1M |
Hangi Alanda Kim Kazanıyor?
At-a-glance decision frameworkDoğrulanmış Benchmark Puanları
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
Gecikme Süresi ve Yanıt Hızı
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Gerçek Zamanlı Token Maliyet Simülatörü
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Command A Plus · Strengths & Key Advantages
- 128K bağlam penceresi ve yanıt başına maksimum 33K çıktı tokenı kapasitesi (SWE-bench Verified 60.5% · GPQA Diamond 74%)
- Sadece 560 ms ilk token gecikmesi (TTFT) ile saniyede 68 token yüksek üretim hızı
- vLLM, SGLang veya Ollama üzerinden yerel GPU sunucularında barındırılabilen açık ağırlıklı mimari (Confidential (~180B+ MoE))
Considerations & Trade-offs
- Tam hassasiyette yerel GPU çıkarımı için yeterli VRAM kapasitesine sahip donanım altyapısı gerektirir
- Yüksek hacimli üretim trafiğinde maliyetleri optimize etmek için Prompt Caching ve Batch API kullanımı önerilir
Nemotron 3 Ultra 550B A55B · Strengths & Key Advantages
- 1M bağlam penceresi ve yanıt başına maksimum 66K çıktı tokenı kapasitesi (SWE-bench Verified 64.5% · GPQA Diamond 76%)
- Sadece 620 ms ilk token gecikmesi (TTFT) ile saniyede 65 token yüksek üretim hızı
- vLLM, SGLang veya Ollama üzerinden yerel GPU sunucularında barındırılabilen açık ağırlıklı mimari (550B (55B MoE))
Considerations & Trade-offs
- Tam hassasiyette yerel GPU çıkarımı için yeterli VRAM kapasitesine sahip donanım altyapısı gerektirir
- Çok karmaşık akademik ve bilimsel çıkarımlarda üst düzey ağır akıl yürütme modelleri daha derin sonuçlar verebilir
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Command A Plus | Nemotron 3 Ultra 550B A55B |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.85 | $0.85 |
Output Tokens / Task Tokens generated per task | 45K | 48K |
Reasoning Tokens / Task Thinking tokens burned per task | 22K | 24K |
Teknik Özellikler
Architecture, release timeline, capabilities, and modalities.
| Feature | Command A Plus | Nemotron 3 Ultra 550B A55B |
|---|---|---|
| Official API Model ID (SDK) | command-a-plus | nemotron-3-ultra-550b-a55b |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-05 | 2026-06 |
| Knowledge Cutoff | March 2026 | February 2026 |
| Architecture | Flagship Multimodal Agentic MoE | Colossal Sparse MoE (550B Total / 55B Active) |
| Parameters | Confidential (~180B+ MoE) | 550B (55B active MoE) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Flat rate ($3/1M in) across full 128K window | Flat rate ($1/1M in) across full 1000K window |
| Prompt Cache Policy & TTL | Cached input at $0.75/1M tokens | Cached input at $0.25/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 112 GB VRAM (4-bit Quantized) · 387 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 341 GB VRAM (4-bit Quantized) · 1183 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision | text |
| Output Modalities | text | text |
Command A Plus vs Nemotron 3 Ultra 550B A55B: Hızlı Yanıtlar (SSS)
Which is more intelligent, Command A Plus or Nemotron 3 Ultra 550B A55B?
Nemotron 3 Ultra 550B A55B is more intelligent. It scores 60 compared with 58 on the composite Intelligence Index.
Which model is faster?
Command A Plus is faster, generating 68 tokens per second compared with 65 tokens per second.
Which model is cheaper to run?
Nemotron 3 Ultra 550B A55B is cheaper at $0.68 per 1M tokens blended, compared with $2.33 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Command A Plus has lower latency, with a time to first token of 0.56s compared with 0.62s.
Which model has a larger context window?
Nemotron 3 Ultra 550B A55B has a larger context window, supporting 1M tokens compared with 128K tokens.
Sonuç
Hem Command A Plus (özel sunucuda kendi kendine barındırma (self-hosting), ince ayar ve tam veri egemenliği, kurumsal RAG mimarileri ve ölçeklenebilir üretim API entegrasyonları için idealdir.) hem de Nemotron 3 Ultra 550B A55B (özel sunucuda kendi kendine barındırma (self-hosting), ince ayar ve tam veri egemenliği, kurumsal RAG mimarileri ve ölçeklenebilir üretim API entegrasyonları için idealdir.) güçlü üretim seçenekleridir: Nemotron 3 Ultra 550B A55B karmaşık akıl yürütme ve kodlama testlerinde öne çıkarken, Command A Plus daha yüksek üretim hızı sağlar; Nemotron 3 Ultra 550B A55B ise yüksek hacimli API kullanımlarında daha ekonomiktir.
Sıkça Sorulan Sorular (SSS)
Kodlama ve akıl yürütme için Command A Plus mi yoksa Nemotron 3 Ultra 550B A55B mi daha iyi?+
Bileşik zeka endeksi ve yazılım testlerinde Nemotron 3 Ultra 550B A55B önde yer alıyor. Detaylı karşılaştırma için yukarıdaki SWE-bench ve GPQA tablolarına göz atabilirsiniz.
Command A Plus ve Nemotron 3 Ultra 550B A55B API fiyatları nasıl karşılaştırılır?+
Command A Plus 1M giriş/çıkış tokeni başına $3.00 / $12.00 ücretlendirilirken, Nemotron 3 Ultra 550B A55B $1.00 / $3.00 seviyesindedir. Karma maliyette Nemotron 3 Ultra 550B A55B daha avantajlıdır.
Hangi modelin bağlam penceresi daha geniş ve hızı daha yüksek?+
Command A Plus 128K token bağlam penceresi sunarken Nemotron 3 Ultra 550B A55B 1M token kapasiteye sahiptir. Saniyedeki token üretim hızında ise Command A Plus öndedir.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Command A Plus vs Claude Opus 5.5: Benchmark, API Fiyatları ve Hız Karşılaştırması (2026)Karşılaştır
- Command A Plus vs Command A Reasoning: Benchmark, API Fiyatları ve Hız Karşılaştırması (2026)Karşılaştır
- Command A Plus vs Command A: Benchmark, API Fiyatları ve Hız Karşılaştırması (2026)Karşılaştır
- Command A Plus vs Gemini 4 Argon: Benchmark, API Fiyatları ve Hız Karşılaştırması (2026)Karşılaştır
- Command A Plus vs GPT-6 Astra: Benchmark, API Fiyatları ve Hız Karşılaştırması (2026)Karşılaştır
- Llama 4 Behemoth vs Nemotron 3 Ultra 550B A55B: Benchmark, API Fiyatları ve Hız Karşılaştırması (2026)Karşılaştır
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Resmi kaynaklar: Cohere ve NVIDIA resmi API dokümantasyonu, sistem kartları ve bağımsız benchmark testleri (2026).