Kimi K2 Thinking vs Kimi K2
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
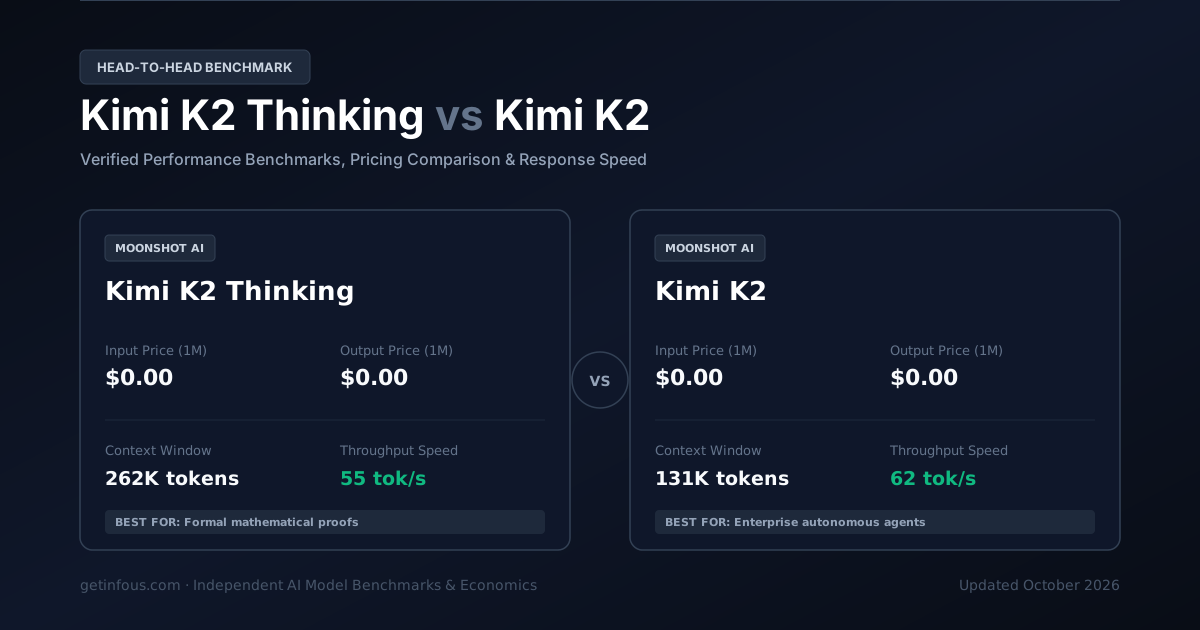
Kimi K2 Thinking da Moonshot AI e Kimi K2 da Moonshot AI são dois modelos de IA de destaque. O Kimi K2 Thinking oferece uma janela de contexto de 262.1K tokens a $0.00/$0.00 por milhão de tokens, enquanto o Kimi K2 oferece 131.1K tokens de contexto a $0.00/$0.00 por milhão de tokens. Veja abaixo a comparação completa de benchmarks, latência e custos.
Troque e Compare Qualquer Modelo
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Kimi K2 Thinking
Raciocínio de Pesos AbertosO Kimi K2 Thinking da Moonshot AI é um modelo de IA projetado para raciocínio em cadeia de pensamento com pesos abertos e alta eficiência, oferecendo janela de contexto de 262K, velocidade de 55 tokens/s, índice de inteligência de 85/100 e
$0.00 / 1M
$0.00 / 1M
262.1K tokens
50%
Kimi K2
IA Agêntica e Uso de FerramentasO Kimi K2 da Moonshot AI é um modelo de IA projetado para fluxos de trabalho agênticos autônomos, chamada de ferramentas e automação, oferecendo janela de contexto de 131K, velocidade de 62 tokens/s, índice de inteligência de 83/100 e tarif
$0.00 / 1M
$0.00 / 1M
131.1K tokens
46%
Principais Diferenças em Resumo
- Both models cost the same under this workload — choose on capability, not price.
- Kimi K2 Thinking has a larger context window (262K vs 131K tokens).
- Kimi K2 is faster at 62 tok/s vs 55 tok/s.
- Kimi K2 Thinking leads on SWE-bench coding (50.0% vs 46.0%).
| Feature | Kimi K2 Thinking | Kimi K2 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 85 | 83 |
Provider | Moonshot AI | Moonshot AI |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 262.1K tokens~393 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 32K | 16K |
Throughput Speed Tokens generated per second | 55 tok/s | 62 tok/s |
SWE-bench Verified Real-world software engineering | 50% | 46% |
GPQA Diamond Graduate-level reasoning | 70% | 66.5% |
Quem vence em cada categoria?
At-a-glance decision frameworkPontuações de Benchmarks Verificadas
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Tokens emitted per second during active generation streaming.
Latência e Tempo de Resposta
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulador Interativo de Custo de Tokens
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Kimi K2 Thinking · Strengths & Key Advantages
- Janela de contexto de 262K com limite máximo de saída de 32K tokens (SWE-bench Verified 50% · GPQA Diamond 70%)
- Taxa de transferência rápida de 55 tokens/segundo com latência inicial (TTFT) de 950 ms
- Pesos abertos (1T total (32B MoE)) para auto-hospedagem local ou em nuvem privada via vLLM, SGLang ou Ollama
Considerations & Trade-offs
- Requer servidores GPU com memória VRAM adequada para execução local em precisão total
- Em derivações científicas extremas, modelos pesados dedicados exclusivamente ao raciocínio oferecem maior profundidade
Kimi K2 · Strengths & Key Advantages
- Janela de contexto de 131K com limite máximo de saída de 16K tokens (SWE-bench Verified 46% · GPQA Diamond 66.5%)
- Taxa de transferência rápida de 62 tokens/segundo com latência inicial (TTFT) de 640 ms
- Pesos abertos (1T total (32B MoE)) para auto-hospedagem local ou em nuvem privada via vLLM, SGLang ou Ollama
Considerations & Trade-offs
- Requer servidores GPU com memória VRAM adequada para execução local em precisão total
- Em derivações científicas extremas, modelos pesados dedicados exclusivamente ao raciocínio oferecem maior profundidade
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Kimi K2 Thinking | Kimi K2 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 28K | 22K |
Reasoning Tokens / Task Thinking tokens burned per task | 16K | 8K |
Especificações Técnicas
Architecture, release timeline, capabilities, and modalities.
| Feature | Kimi K2 Thinking | Kimi K2 |
|---|---|---|
| Official API Model ID (SDK) | kimi-k2-thinking | kimi-k2 |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2025-11 | 2025-07 |
| Knowledge Cutoff | September 2025 | May 2025 |
| Architecture | Deliberate Reasoning Open Sparse Mixture-of-Experts | Trillion-Scale Sparse Mixture-of-Experts Transformer |
| Parameters | 1T total (32B active MoE) | 1T total (32B active MoE) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 620 GB VRAM (4-bit Quantized) · 2150 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 620 GB VRAM (4-bit Quantized) · 2150 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text | text |
| Output Modalities | text | text |
Kimi K2 Thinking vs Kimi K2: Respostas Rápidas (FAQ)
Which is more intelligent, Kimi K2 Thinking or Kimi K2?
Kimi K2 Thinking is more intelligent. It scores 85 compared with 83 on the composite Intelligence Index.
Which model is faster?
Kimi K2 is faster, generating 62 tokens per second compared with 55 tokens per second.
Which model has lower latency?
Kimi K2 has lower latency, with a time to first token of 0.64s compared with 0.95s.
Which model has a larger context window?
Kimi K2 Thinking has a larger context window, supporting 262.1K tokens compared with 131.1K tokens.
Veredito
Tanto Kimi K2 Thinking (Indicado para raciocínio em cadeia de pensamento com pesos abertos e alta eficiência, arquiteturas RAG corporativas e integração escalável via API.) quanto Kimi K2 (Indicado para fluxos de trabalho agênticos autônomos, chamada de ferramentas e automação, arquiteturas RAG corporativas e integração escalável via API.) entregam excelente desempenho: Kimi K2 Thinking lidera em inteligência geral e programação, Kimi K2 oferece geração mais rápida e Kimi K2 Thinking apresenta o melhor custo-benefício em produção.
Perguntas Frequentes (FAQ)
Qual é melhor para programação e raciocínio, Kimi K2 Thinking ou Kimi K2?+
Nas avaliações de inteligência e código, Kimi K2 Thinking leva vantagem. Confira os gráficos SWE-bench e GPQA acima para detalhes.
Qual modelo tem a API mais barata, Kimi K2 Thinking ou Kimi K2?+
O Kimi K2 Thinking custa $0.00 / $0.00 por 1M de tokens (entrada/saída) e o Kimi K2 custa $0.00 / $0.00. No custo combinado, Kimi K2 Thinking é mais econômico.
Qual modelo possui maior janela de contexto e velocidade?+
O Kimi K2 Thinking suporta 262.1K tokens de contexto contra 131.1K tokens do Kimi K2, enquanto Kimi K2 entrega maior velocidade de geração.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- GLM-4.5-Air vs. Kimi K2: Comparação de Benchmarks, Preços API e Velocidade (2026)Comparar
- GLM-4.7 vs. Kimi K2 Thinking: Comparação de Benchmarks, Preços API e Velocidade (2026)Comparar
- Kimi K2.5 vs. Kimi K2 Thinking: Comparação de Benchmarks, Preços API e Velocidade (2026)Comparar
- Aion-3.0 vs. Aion-Mini: Comparação de Benchmarks, Preços API e Velocidade (2026)Comparar
- Aion-3.0 vs. Gemini 3.6 Flash: Comparação de Benchmarks, Preços API e Velocidade (2026)Comparar
- Aion-Mini vs. Laguna XS 2.1: Comparação de Benchmarks, Preços API e Velocidade (2026)Comparar
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Fontes oficiais: Documentação oficial de API da Moonshot AI e Moonshot AI e benchmarks independentes (2026).