Qwen3.8 Max Preview vs DeepSeek V4.1-Flash
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
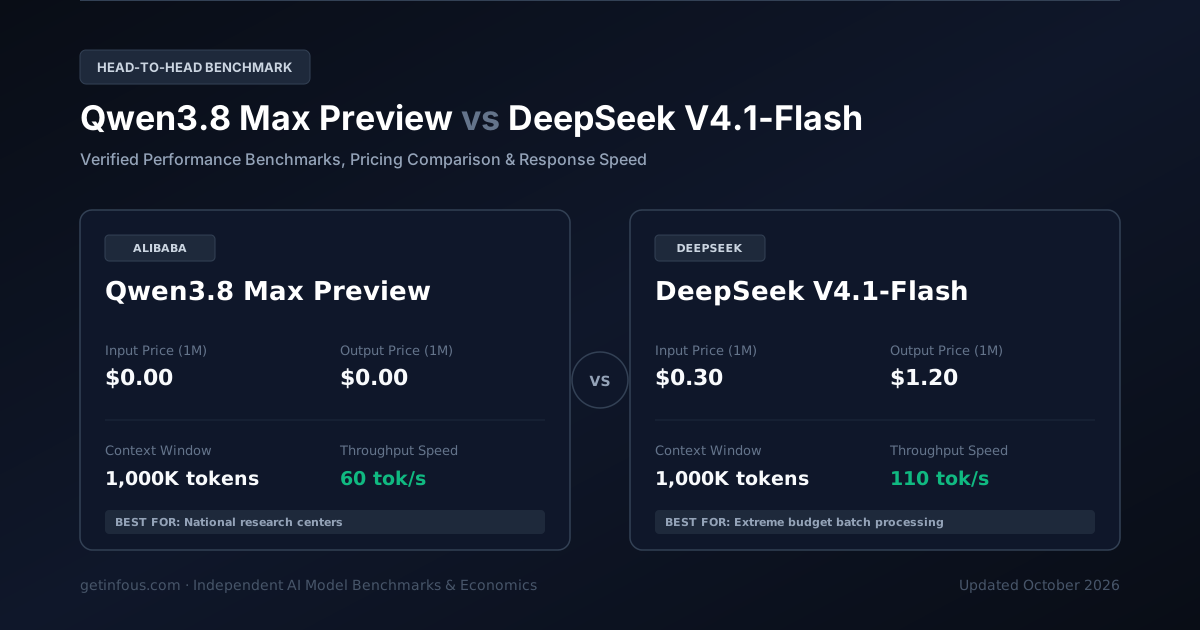
Alibaba의 Qwen3.8 Max Preview와 DeepSeek의 DeepSeek V4.1-Flash는 현재 가장 주목받는 AI 모델입니다. Qwen3.8 Max Preview는 1M 토큰 컨텍스트 윈도우와 100만 토큰당 $0.00/$0.00(입력/출력)의 요금을 제공하며, DeepSeek V4.1-Flash는 1M 토큰 컨텍스트와 $0.30/$1.20의 요금을 제공합니다. 아래에서 벤치마크, 지연 시간 및 비용을 상세히 비교해 보세요.
원하는 AI 모델 선택 및 실시간 비교
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Qwen3.8 Max Preview
오픈 웨이트 파운데이션 모델Alibaba의 Qwen3.8 Max Preview 모델은 프라이빗 클라우드 자체 호스팅, 파인튜닝 및 완벽한 데이터 주권 확보에 최적화된 AI 모델로, 1M 컨텍스트 윈도우, 초당 60 토큰의 생성 속도, 종합 지능 지수 93/100점(무료 오픈 웨이트 제공)을 제공합니다.
$0.00 / 1M
$0.00 / 1M
1M tokens
75.2%
DeepSeek V4.1-Flash
오픈 웨이트 파운데이션 모델DeepSeek의 DeepSeek V4.1-Flash 모델은 프라이빗 클라우드 자체 호스팅, 파인튜닝 및 완벽한 데이터 주권 확보에 최적화된 AI 모델로, 1M 컨텍스트 윈도우, 초당 110 토큰의 생성 속도, 종합 지능 지수 58/100점(1M 토큰당 입력 $0.3 / 출력 $1.2)을 제공합니다.
$0.30 / 1M
$1.20 / 1M
1M tokens
74.2%
한눈에 보는 핵심 차이점
- Qwen3.8 Max Preview is 1.0x cheaper for API usage (input + output tokens combined).
- DeepSeek V4.1-Flash is faster at 110 tok/s vs 60 tok/s.
- Qwen3.8 Max Preview leads on SWE-bench coding (75.2% vs 74.2%).
| Feature | Qwen3.8 Max Preview | DeepSeek V4.1-Flash |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 93 | 58 |
Provider | Alibaba | DeepSeek |
Input Price Cost per million input tokens | $0.00 / 1M | $0.30 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $1.20 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.18 / 1M |
Context Window Maximum input + output tokens | 1M tokens~1,500 A4 pages of text | 1M tokens~1,500 A4 pages of text |
Max Output Tokens Per single request | 32K | 384K |
Throughput Speed Tokens generated per second | 60 tok/s | 110 tok/s |
SWE-bench Verified Real-world software engineering | 75.2% | 74.2% |
GPQA Diamond Graduate-level reasoning | 79.5% | 90.9% |
Cached Input Price Prompt caching discount per 1M tokens | $0.00 / 1M | $0.01 / 1M |
부문별 우위 모델
At-a-glance decision framework검증된 벤치마크 점수 비교
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
지연 시간(Latency) 및 응답 속도
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
실시간 API 토큰 비용 시뮬레이터
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Qwen3.8 Max Preview · Strengths & Key Advantages
- 1M 컨텍스트 윈도우 및 최대 32K 출력 토큰 생성 지원 (SWE-bench Verified 75.2% · GPQA Diamond 79.5%)
- 초당 60 토큰의 빠른 처리 속도와 680ms에 불과한 첫 토큰 지연 시간(TTFT)
- 오픈 웨이트 아키텍처 (2.4T total (95B MoE))를 통해 vLLM, SGLang, Ollama 기반 자체 GPU 서버 구축 및 파인튜닝 가능
Considerations & Trade-offs
- 비양자화 전체 정밀도로 로컬 서버에서 구동하려면 충분한 GPU VRAM 용량이 필요합니다
- 초고난도 학술 연구 및 수학 증명 과제에서는 상위 대형 추론 특화 모델이 더 깊은 분석을 제공할 수 있습니다
DeepSeek V4.1-Flash · Strengths & Key Advantages
- 1M 컨텍스트 윈도우 및 최대 384K 출력 토큰 생성 지원 (SWE-bench Verified 74.2% · GPQA Diamond 90.9%)
- 초당 110 토큰의 빠른 처리 속도와 460ms에 불과한 첫 토큰 지연 시간(TTFT)
- 오픈 웨이트 아키텍처 (763B total (8B prefill / 16B decode ))를 통해 vLLM, SGLang, Ollama 기반 자체 GPU 서버 구축 및 파인튜닝 가능
Considerations & Trade-offs
- 비양자화 전체 정밀도로 로컬 서버에서 구동하려면 충분한 GPU VRAM 용량이 필요합니다
- 초고난도 학술 연구 및 수학 증명 과제에서는 상위 대형 추론 특화 모델이 더 깊은 분석을 제공할 수 있습니다
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Qwen3.8 Max Preview | DeepSeek V4.1-Flash |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.27 |
Output Tokens / Task Tokens generated per task | 35K | 58K |
Reasoning Tokens / Task Thinking tokens burned per task | 15K | 28K |
기술 사양 (Specifications)
Architecture, release timeline, capabilities, and modalities.
| Feature | Qwen3.8 Max Preview | DeepSeek V4.1-Flash |
|---|---|---|
| Official API Model ID (SDK) | qwen3-8-max-preview-instruct | deepseek-reasoner |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-07 | 2026-09 |
| Knowledge Cutoff | April 2026 | June 2026 |
| Architecture | Colossus-Scale Open Sparse Mixture-of-Experts | Causal Encoder-Decoder (20 enc + 20 dec layers) |
| Parameters | 2.4T total (95B active MoE) | 763B total (8B prefill / 16B decode active) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Flat rate ($0.3/1M in) across full 1000K window |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix caching at $0.006/1M (no extra cache-write fee) |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 1488 GB VRAM (4-bit Quantized) · 5160 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 473 GB VRAM (4-bit Quantized) · 1640 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Qwen3.8 Max Preview vs DeepSeek V4.1-Flash: 핵심 요약 문답 (FAQ)
Which is more intelligent, Qwen3.8 Max Preview or DeepSeek V4.1-Flash?
Qwen3.8 Max Preview is more intelligent. It scores 93 compared with 58 on the composite Intelligence Index.
Which model is faster?
DeepSeek V4.1-Flash is faster, generating 110 tokens per second compared with 60 tokens per second.
Which model is cheaper to run?
Qwen3.8 Max Preview is cheaper at $0.00 per 1M tokens blended, compared with $0.18 (7:2:1 cache:input:output ratio).
Which model has lower latency?
DeepSeek V4.1-Flash has lower latency, with a time to first token of 0.46s compared with 0.68s.
종합 평가
Qwen3.8 Max Preview(프라이빗 클라우드 자체 호스팅, 파인튜닝 및 완벽한 데이터 주권 확보, 엔터프라이즈 RAG 지식베이스 및 대규모 프로덕션 API 연동에 최적.)와 DeepSeek V4.1-Flash(프라이빗 클라우드 자체 호스팅, 파인튜닝 및 완벽한 데이터 주권 확보, 엔터프라이즈 RAG 지식베이스 및 대규모 프로덕션 API 연동에 최적.) 모두 뛰어난 성능을 자랑합니다. 고난도 추론과 코딩 벤치마크에서는 Qwen3.8 Max Preview가 앞서며, 토큰 생성 속도에서는 DeepSeek V4.1-Flash가 빠르고, 대규모 API 운영 비용 면에서는 Qwen3.8 Max Preview가 더 경제적입니다.
자주 묻는 질문 (FAQ)
코딩과 복잡한 추론에는 Qwen3.8 Max Preview와 DeepSeek V4.1-Flash 중 어느 모델이 더 나은가요?+
종합 지능 지수 및 코딩 벤치마크에서는 Qwen3.8 Max Preview가 우위를 보입니다. 상단의 SWE-bench 및 GPQA 점수를 함께 확인해 보세요.
Qwen3.8 Max Preview와 DeepSeek V4.1-Flash의 API 요금 차이는 얼마인가요?+
Qwen3.8 Max Preview는 100만 토큰당 입력 $0.00 / 출력 $0.00이며, DeepSeek V4.1-Flash는 입력 $0.30 / 출력 $1.20입니다. 혼합 비용 기준으로는 Qwen3.8 Max Preview가 더 저렴합니다.
어느 모델이 더 큰 컨텍스트 윈도우와 빠른 속도를 제공하나요?+
컨텍스트 길이는 Qwen3.8 Max Preview가 1M 토큰, DeepSeek V4.1-Flash가 1M 토큰를 지원하며, 출력 속도 면에서는 DeepSeek V4.1-Flash가 더 빠릅니다.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- DeepSeek V4.1-Flash vs Gemini 4 Argon: 벤치마크, API 요금 및 속도 비교 (2026)비교
- DeepSeek V4.1-Flash vs GLM-5.2: 벤치마크, API 요금 및 속도 비교 (2026)비교
- GPT-6 Luna vs DeepSeek V4.1-Flash: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Grok 4.7 vs DeepSeek V4.1-Flash: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Llama 5 vs Qwen3.8 Max Preview: 벤치마크, API 요금 및 속도 비교 (2026)비교
- Mistral Medium 3.5 vs DeepSeek V4.1-Flash: 벤치마크, API 요금 및 속도 비교 (2026)비교
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
공식 출처: Alibaba 및 DeepSeek 공식 API 문서, 시스템 카드 및 독립 벤치마크 평가 (2026).