GLM-4.5 vs GLM-4.5-Air
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
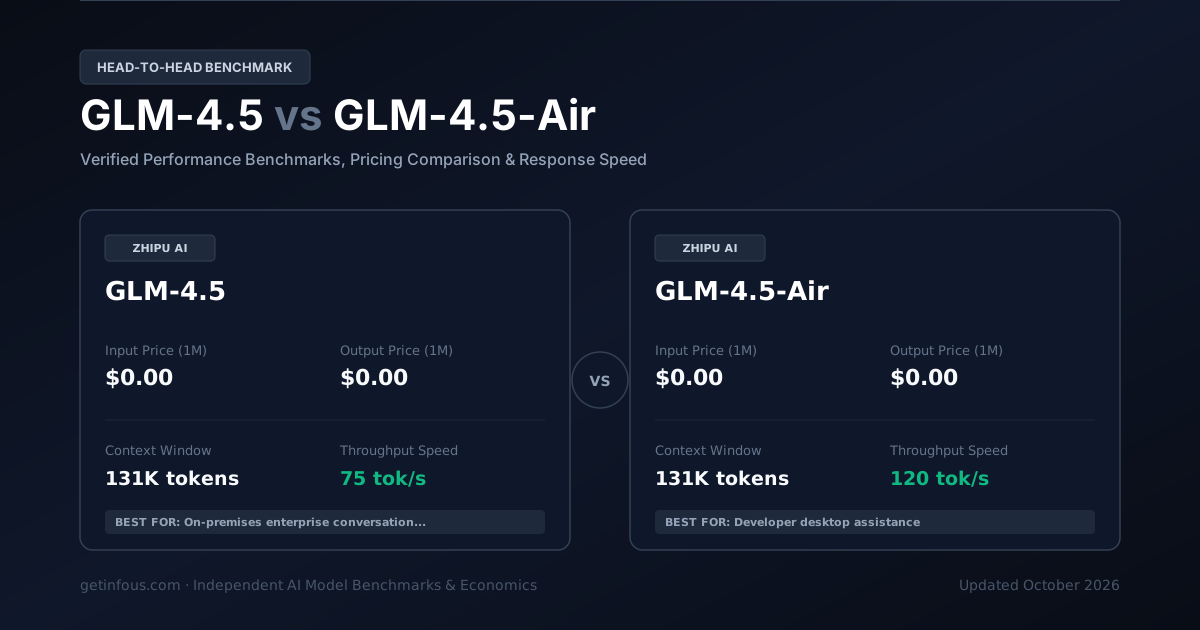
GLM-4.5 by Zhipu AI and GLM-4.5-Air by Zhipu AI represent two of the frontier AI models analyzed in our comprehensive 2026 AI benchmark and LLM comparison. In this head-to-head evaluation, we examine API token pricing, context window specifications, inference speed (tokens per second), and empirical reasoning performance. From a pure economic perspective, both models offer identical input token rates. On output generation, costs are matched. In data-heavy architectures requiring extensive repository or document analysis, both models provide an identical memory horizon with 131K tokens. In latency-sensitive production environments, GLM-4.5-Air leads in tokens-per-second throughput, making it ideal for real-time conversational agents and high-concurrency workflows. Below is the complete empirical head-to-head breakdown across cost, speed, context, and capability matrices.
任意のAIモデルを切り替えて比較
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
GLM-4.5
オープンウェイトモデルZhipu AI が提供する GLM-4.5 は、最大 131K トークンのコンテキストウィンドウを備え、入力 $0/100万トークン・出力 $0/100万トークンで利用可能な、コーディング・推論・業務自動化向け AI モデルです。
$0.00 / 1M
$0.00 / 1M
131.1K tokens
42%
GLM-4.5-Air
オープンウェイトモデルZhipu AI が提供する GLM-4.5-Air は、最大 131K トークンのコンテキストウィンドウを備え、入力 $0/100万トークン・出力 $0/100万トークンで利用可能な、コーディング・推論・業務自動化向け AI モデルです。
$0.00 / 1M
$0.00 / 1M
131.1K tokens
N/A
ひと目でわかる主な違い
- Both models cost the same under this workload — choose on capability, not price.
- GLM-4.5-Air is faster at 120 tok/s vs 75 tok/s.
| Feature | GLM-4.5 | GLM-4.5-Air |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 80 | 74 |
Provider | Zhipu AI | Zhipu AI |
Input Price Cost per million input tokens | $0.00 / 1M | $0.00 / 1M |
Output Price Cost per million output tokens | $0.00 / 1M | $0.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.00 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 131.1K tokens~197 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 8K | 8K |
Throughput Speed Tokens generated per second | 75 tok/s | 120 tok/s |
SWE-bench Verified Real-world software engineering | 42% | N/A |
GPQA Diamond Graduate-level reasoning | 61% | 52% |
分野別勝者スコアカード
At-a-glance decision frameworkEvaluations ongoing
検証済みベンチマークスコア比較
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
レイテンシ&応答時間
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
リアルタイムAPIトークン料金シミュレーター
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
GLM-4.5 · Strengths & Key Advantages
- Zhipu AI の高度な Hybrid Reasoning Mixture-of-Experts Transformer アーキテクチャと 131K トークンのコンテキスト処理能力
- 優れたコストパフォーマンス(入力 $0/1M、出力 $0/1M)と安定した応答速度
- プログラミング、論理的推論、多言語タスクにおいて高いベンチマーク精度を実現
Considerations & Trade-offs
- 大規模な長文コンテキスト処理時はトークン消費量の最適化が必要
- 専門領域のタスクでは適切なプロンプト設計や RAG の併用が推奨される
GLM-4.5-Air · Strengths & Key Advantages
- Zhipu AI の高度な Lightweight Sparse Mixture-of-Experts Transformer アーキテクチャと 131K トークンのコンテキスト処理能力
- 優れたコストパフォーマンス(入力 $0/1M、出力 $0/1M)と安定した応答速度
- プログラミング、論理的推論、多言語タスクにおいて高いベンチマーク精度を実現
Considerations & Trade-offs
- 大規模な長文コンテキスト処理時はトークン消費量の最適化が必要
- 専門領域のタスクでは適切なプロンプト設計や RAG の併用が推奨される
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | GLM-4.5 | GLM-4.5-Air |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.00 | $0.00 |
Output Tokens / Task Tokens generated per task | 16K | 12K |
Reasoning Tokens / Task Thinking tokens burned per task | 6K | 2K |
技術仕様・スペック
Architecture, release timeline, capabilities, and modalities.
| Feature | GLM-4.5 | GLM-4.5-Air |
|---|---|---|
| Official API Model ID (SDK) | glm-4-5 | glm-4-5-air |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2025-07 | 2025-07 |
| Knowledge Cutoff | May 2025 | May 2025 |
| Architecture | Hybrid Reasoning Mixture-of-Experts Transformer | Lightweight Sparse Mixture-of-Experts Transformer |
| Parameters | 130B MoE | 30B MoE |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Free across full context window (only KV-cache VRAM scales) | Free across full context window (only KV-cache VRAM scales) |
| Prompt Cache Policy & TTL | Automatic prefix KV-caching in vLLM / SGLang (0 cost) | Automatic prefix KV-caching in vLLM / SGLang (0 cost) |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 81 GB VRAM (4-bit Quantized) · 280 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 19 GB VRAM (4-bit Quantized) · 65 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text | text |
| Output Modalities | text | text |
GLM-4.5 vs GLM-4.5-Air: よくある質問 (FAQ)
Which is more intelligent, GLM-4.5 or GLM-4.5-Air?
GLM-4.5 is more intelligent. It scores 80 compared with 74 on the composite Intelligence Index.
Which model is faster?
GLM-4.5-Air is faster, generating 120 tokens per second compared with 75 tokens per second.
Which model has lower latency?
GLM-4.5-Air has lower latency, with a time to first token of 0.36s compared with 0.55s.
総合評価
Verdict & Model Selection Recommendation: Choose GLM-4.5 if your priority is On-premises enterprise conversational agents, bilingual reasoning, and data analysis. Its performance in demanding tasks justifies its operational token cost. Choose GLM-4.5-Air if your workflow prioritizes Developer desktop assistance, customer support bots, and internal document search. For large-scale batch processing or customer-facing conversational interfaces, its balance of speed and economics delivers superior ROI.
よくある質問 (FAQ)
How does GLM-4.5 compare to GLM-4.5-Air in API token pricing and cost per token?+
Both GLM-4.5 and GLM-4.5-Air are open-weights foundation models available at $0.00 direct API cost when self-hosted, or offered at identical baseline rates across major inference providers. Model selection depends on GPU deployment sizing and specialized benchmark performance rather than raw token price.
Which model has a larger context window: GLM-4.5 or GLM-4.5-Air?+
Both GLM-4.5 and GLM-4.5-Air offer an identical context window of 131K tokens (~98k words). Both architectures provide equal capacity for large document ingestion, multi-file codebases, and extended multi-turn conversation histories.
Which AI model is better for software engineering and coding: GLM-4.5 or GLM-4.5-Air?+
GLM-4.5 scores 42% on SWE-bench Verified, while GLM-4.5-Air scores competitively for software generation. For complex autonomous debugging and agentic engineering, GLM-4.5 provides robust code generation and tool calling.
What is the difference in reasoning capability and extended thinking between GLM-4.5 and GLM-4.5-Air?+
GLM-4.5 features native chain-of-thought extended thinking mode with configurable reasoning effort. In contrast, GLM-4.5-Air provides chain-of-thought reasoning depth for complex math and science.
How does inference speed (tokens per second) compare between GLM-4.5 and GLM-4.5-Air?+
GLM-4.5 generates approximately 75 tokens per second, while GLM-4.5-Air delivers 120 tokens per second. In latency-sensitive production environments, GLM-4.5-Air provides faster time-to-first-token (TTFT) and higher streaming response velocity.
Can you implement a tiered LLM routing setup combining GLM-4.5 and GLM-4.5-Air to optimize costs?+
Yes! Tiered multi-model routing can optimize for latency and accuracy: you can route high-frequency conversational turns and latency-sensitive queries to GLM-4.5-Air, and route deep architectural or complex reasoning queries to GLM-4.5. This balanced routing strategy maximizes system throughput and answer quality.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- GLM-4.5-Air vs Kimi K2: Benchmarks, Pricing & Speed Comparison比較
- GLM-4.5 vs Qwen3-Next 80B-A3B (Thinking): Benchmarks, Pricing & Speed Comparison比較
- GLM-4.5V vs GLM-4.5: Benchmarks, Pricing & Speed Comparison比較
- Aion-3.0 vs Aion-Mini: Benchmarks, Pricing & Speed Comparison比較
- Aion-3.0 vs Gemini 3.6 Flash: Benchmarks, Pricing & Speed Comparison比較
- Aion-Mini vs Laguna XS 2.1: Benchmarks, Pricing & Speed Comparison比較
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
公的ソース: GetInfoUs Independent AI Benchmarks & Official API Specs