Gemini 2.5 Flash vs GLM-4.5-Flash
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
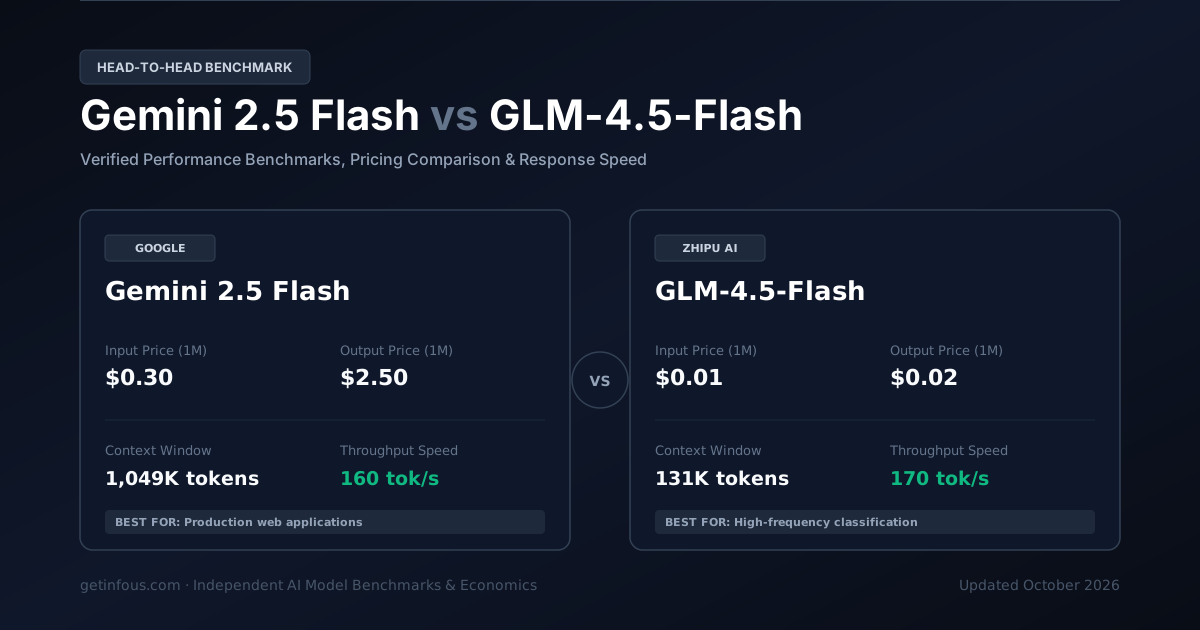
Gemini 2.5 Flash dari Google dan GLM-4.5-Flash dari Zhipu AI adalah dua model AI unggulan. Gemini 2.5 Flash menawarkan jendela konteks 1.05M token dengan harga $0.30/$2.50 per 1 juta token, sedangkan GLM-4.5-Flash menyediakan konteks 131.1K token seharga $0.01/$0.02 per 1 juta token. Berikut perbandingan lengkap benchmark, latensi, dan biayanya.
Ganti & Bandingkan Model Apa Saja
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Gemini 2.5 Flash
Inferensi Super CepatGemini 2.5 Flash dari Google adalah model AI yang dirancang untuk interaksi real-time dengan latensi sangat rendah dan routing bervolume tinggi, menghadirkan jendela konteks 1.0M, kecepatan 160 token/detik, indeks kecerdasan 68/100, serta t
$0.30 / 1M
$2.50 / 1M
1.05M tokens
58.2%
GLM-4.5-Flash
Inferensi Super CepatGLM-4.5-Flash dari Zhipu AI adalah model AI yang dirancang untuk interaksi real-time dengan latensi sangat rendah dan routing bervolume tinggi, menghadirkan jendela konteks 131K, kecepatan 170 token/detik, indeks kecerdasan 72/100, serta ta
$0.01 / 1M
$0.02 / 1M
131.1K tokens
N/A
Perbedaan Utama Sekilas
- GLM-4.5-Flash is 81.5x cheaper for API usage (input + output tokens combined).
- Gemini 2.5 Flash has a larger context window (1M vs 131K tokens).
- GLM-4.5-Flash is faster at 170 tok/s vs 160 tok/s.
| Feature | Gemini 2.5 Flash | GLM-4.5-Flash |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 68 | 72 |
Provider | Zhipu AI | |
Input Price Cost per million input tokens | $0.30 / 1M | $0.01 / 1M |
Output Price Cost per million output tokens | $2.50 / 1M | $0.02 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.36 / 1M | $0.00 / 1M |
Context Window Maximum input + output tokens | 1.05M tokens~1,573 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 66K | 8K |
Throughput Speed Tokens generated per second | 160 tok/s | 170 tok/s |
SWE-bench Verified Real-world software engineering | 58.2% | N/A |
GPQA Diamond Graduate-level reasoning | 75.4% | N/A |
Cached Input Price Prompt caching discount per 1M tokens | $0.07 / 1M | $0.00 / 1M |
Siapa Unggul di Mana?
At-a-glance decision frameworkEvaluations ongoing
Skor Benchmark Terverifikasi
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Tokens emitted per second during active generation streaming.
Latensi & Waktu Respons
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulator Biaya Token Interaktif
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Gemini 2.5 Flash · Strengths & Key Advantages
- Jendela konteks 1.0M dengan kapasitas output maksimum hingga 66K token (SWE-bench Verified 58.2% · GPQA Diamond 75.4%)
- Kecepatan generasi tinggi 160 token/detik dengan latensi token pertama (TTFT) hanya 450 ms
- Skema harga API kompetitif (tarif $0.3/$2.5 per 1M token) dengan dukungan cache prompt dan output JSON terstruktur
Considerations & Trade-offs
- Model cloud proprietari tertutup; bobot model tidak dapat diunduh untuk penggunaan lokal offline
- Pada tugas pembuktian ilmiah tingkat ekstrem, model penalaran berat kelas atas memberikan kedalaman lebih tinggi
GLM-4.5-Flash · Strengths & Key Advantages
- Jendela konteks 131K dengan kapasitas output maksimum hingga 8K token (MMLU-Pro 68% · Arena Elo 1240)
- Kecepatan generasi tinggi 170 token/detik dengan latensi token pertama (TTFT) hanya 220 ms
- Skema harga API kompetitif (tarif $0.01/$0.02 per 1M token) dengan dukungan cache prompt dan output JSON terstruktur
Considerations & Trade-offs
- Model cloud proprietari tertutup; bobot model tidak dapat diunduh untuk penggunaan lokal offline
- Pada tugas pembuktian ilmiah tingkat ekstrem, model penalaran berat kelas atas memberikan kedalaman lebih tinggi
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Gemini 2.5 Flash | GLM-4.5-Flash |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.85 | $0.01 |
Output Tokens / Task Tokens generated per task | 32K | 10K |
Reasoning Tokens / Task Thinking tokens burned per task | 14K | 0K |
Spesifikasi Teknis
Architecture, release timeline, capabilities, and modalities.
| Feature | Gemini 2.5 Flash | GLM-4.5-Flash |
|---|---|---|
| Official API Model ID (SDK) | models/gemini-2-5-flash | glm-4-5-flash |
| API Protocol | Google Gemini API (generateContent) + OpenAI-Compatible SDK | Zhipu AI REST API (OpenAI-Compatible) |
| Release Date | 2025-06 | 2025-07 |
| Knowledge Cutoff | March 2025 | May 2025 |
| Architecture | High-throughput sparse multimodal transformer with thinking mode | Ultra-High-Speed Distilled Transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 4,000,000 – 10,000,000 TPM | 5,000 – 15,000 RPM (Production Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens | Flat rate ($0.01/1M in) across full 131K window |
| Prompt Cache Policy & TTL | Implicit + Explicit Context Caching at $0.075/1M with configurable TTL | Cached input at $0.001/1M tokens |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Built-in Google Search Grounding + Managed Python Code Execution Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Vertex AI Supervised Adapter Tuning & Context Distillation | API Prompt Engineering & RAG Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) · Audio (~25–32 tokens/sec) · Video (~258–300 tokens/sec) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Google DeepMind Frontier Safety Framework Verified | Zhipu AI Production Safety & Alignment Verified |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision, audio, video | text |
| Output Modalities | text | text |
Gemini 2.5 Flash vs GLM-4.5-Flash: Jawaban Cepat (FAQ)
Which is more intelligent, Gemini 2.5 Flash or GLM-4.5-Flash?
GLM-4.5-Flash is more intelligent. It scores 72 compared with 68 on the composite Intelligence Index.
Which model is faster?
GLM-4.5-Flash is faster, generating 170 tokens per second compared with 160 tokens per second.
Which model is cheaper to run?
GLM-4.5-Flash is cheaper at $0.00 per 1M tokens blended, compared with $0.36 (7:2:1 cache:input:output ratio).
Which model has lower latency?
GLM-4.5-Flash has lower latency, with a time to first token of 0.22s compared with 0.45s.
Which model has a larger context window?
Gemini 2.5 Flash has a larger context window, supporting 1.05M tokens compared with 131.1K tokens.
Kesimpulan
Baik Gemini 2.5 Flash (Sangat cocok untuk interaksi real-time dengan latensi sangat rendah dan routing bervolume tinggi, sistem RAG perusahaan, dan integrasi API skala produksi.) maupun GLM-4.5-Flash (Sangat cocok untuk interaksi real-time dengan latensi sangat rendah dan routing bervolume tinggi, sistem RAG perusahaan, dan integrasi API skala produksi.) sangat tangguh: GLM-4.5-Flash unggul dalam penalaran dan pemrograman, GLM-4.5-Flash memberikan kecepatan generasi token lebih tinggi, dan GLM-4.5-Flash lebih hemat biaya untuk penggunaan API skala besar.
Pertanyaan Umum (FAQ)
Mana yang lebih baik untuk coding dan penalaran, Gemini 2.5 Flash atau GLM-4.5-Flash?+
Dalam indeks kecerdasan gabungan dan benchmark coding, GLM-4.5-Flash memimpin. Lihat skor SWE-bench dan GPQA di atas untuk detailnya.
Berapa perbandingan harga API Gemini 2.5 Flash vs GLM-4.5-Flash?+
Gemini 2.5 Flash mengenakan biaya $0.30 / $2.50 per 1M token input/output, sedangkan GLM-4.5-Flash sebesar $0.01 / $0.02. Secara keseluruhan, GLM-4.5-Flash lebih hemat biaya.
Model mana yang memiliki jendela konteks lebih besar dan kecepatan lebih tinggi?+
Gemini 2.5 Flash mendukung konteks 1.05M token dibandingkan 131.1K token pada GLM-4.5-Flash, sementara GLM-4.5-Flash unggul dalam kecepatan output token per detik.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Gemini 2.5 Computer Use vs Gemini 2.5 Flash: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Gemini 2.5 Flash vs Gemini 2.5 Flash-Lite: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- GLM-5-Turbo vs GLM-4.5-Flash: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Aion-3.0 vs Aion-Mini: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Aion-3.0 vs Gemini 3.6 Flash: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Aion-Mini vs Laguna XS 2.1: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Sumber resmi: Dokumentasi API resmi Google & Zhipu AI serta evaluasi benchmark independen (2026).