Claude Sonnet 4.5 vs Claude Haiku 4.5
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
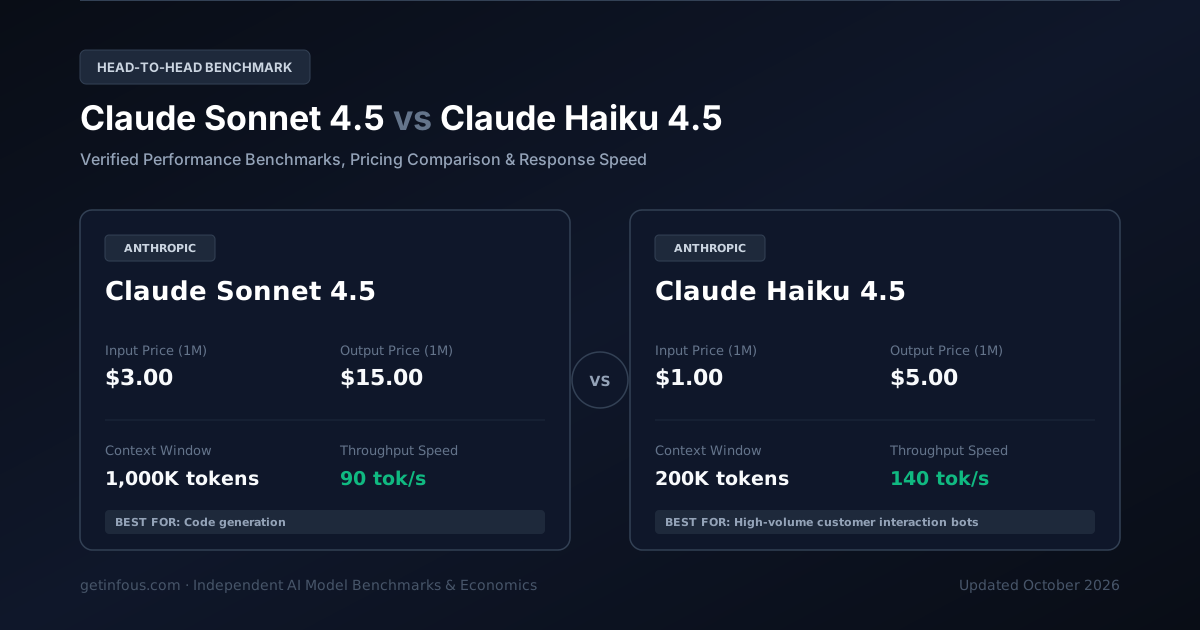
Claude Sonnet 4.5 dari Anthropic dan Claude Haiku 4.5 dari Anthropic adalah dua model AI unggulan. Claude Sonnet 4.5 menawarkan jendela konteks 1M token dengan harga $3.00/$15.00 per 1 juta token, sedangkan Claude Haiku 4.5 menyediakan konteks 200K token seharga $1.00/$5.00 per 1 juta token. Berikut perbandingan lengkap benchmark, latensi, dan biayanya.
Ganti & Bandingkan Model Apa Saja
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Claude Sonnet 4.5
Model Unggulan Garis DepanClaude Sonnet 4.5 dari Anthropic adalah model AI yang dirancang untuk penalaran perusahaan garis depan, pemrograman tingkat lanjut, dan produksi AI, menghadirkan jendela konteks 1M, kecepatan 90 token/detik, indeks kecerdasan 91/100, serta
$3.00 / 1M
$15.00 / 1M
1M tokens
77.8%
Claude Haiku 4.5
Inferensi Super CepatClaude Haiku 4.5 dari Anthropic adalah model AI yang dirancang untuk interaksi real-time dengan latensi sangat rendah dan routing bervolume tinggi, menghadirkan jendela konteks 200K, kecepatan 140 token/detik, indeks kecerdasan 54/100, sert
$1.00 / 1M
$5.00 / 1M
200K tokens
58.2%
Perbedaan Utama Sekilas
- Claude Haiku 4.5 is 3.0x cheaper for API usage (input + output tokens combined).
- Claude Sonnet 4.5 has a larger context window (1M vs 200K tokens).
- Claude Haiku 4.5 is faster at 140 tok/s vs 90 tok/s.
- Claude Sonnet 4.5 leads on SWE-bench coding (77.8% vs 58.2%).
| Feature | Claude Sonnet 4.5 | Claude Haiku 4.5 |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 91 | 54 |
Provider | Anthropic | Anthropic |
Input Price Cost per million input tokens | $3.00 / 1M | $1.00 / 1M |
Output Price Cost per million output tokens | $15.00 / 1M | $5.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $2.31 / 1M | $0.77 / 1M |
Context Window Maximum input + output tokens | 1M tokens~1,500 A4 pages of text | 200K tokens~300 A4 pages of text |
Max Output Tokens Per single request | 64K | 64K |
Throughput Speed Tokens generated per second | 90 tok/s | 140 tok/s |
SWE-bench Verified Real-world software engineering | 77.8% | 58.2% |
GPQA Diamond Graduate-level reasoning | 70.2% | 62.1% |
Cached Input Price Prompt caching discount per 1M tokens | $0.30 / 1M | $0.10 / 1M |
Siapa Unggul di Mana?
At-a-glance decision frameworkSkor Benchmark Terverifikasi
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
Latensi & Waktu Respons
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
Simulator Biaya Token Interaktif
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Claude Sonnet 4.5 · Strengths & Key Advantages
- Jendela konteks 1M dengan kapasitas output maksimum hingga 64K token (SWE-bench Verified 77.8% · GPQA Diamond 70.2%)
- Kecepatan generasi tinggi 90 token/detik dengan latensi token pertama (TTFT) hanya 900 ms
- Skema harga API kompetitif (tarif $3/$15 per 1M token) dengan dukungan cache prompt dan output JSON terstruktur
Considerations & Trade-offs
- Model cloud proprietari tertutup; bobot model tidak dapat diunduh untuk penggunaan lokal offline
- Untuk trafik produksi skala besar, disarankan mengaktifkan fitur Prompt Caching dan Batch API guna menghemat biaya
Claude Haiku 4.5 · Strengths & Key Advantages
- Jendela konteks 200K dengan kapasitas output maksimum hingga 64K token (SWE-bench Verified 58.2% · GPQA Diamond 62.1%)
- Kecepatan generasi tinggi 140 token/detik dengan latensi token pertama (TTFT) hanya 280 ms
- Skema harga API kompetitif (tarif $1/$5 per 1M token) dengan dukungan cache prompt dan output JSON terstruktur
Considerations & Trade-offs
- Model cloud proprietari tertutup; bobot model tidak dapat diunduh untuk penggunaan lokal offline
- Pada tugas pembuktian ilmiah tingkat ekstrem, model penalaran berat kelas atas memberikan kedalaman lebih tinggi
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Claude Sonnet 4.5 | Claude Haiku 4.5 |
|---|---|---|
Cost per Task Estimated USD to finish one task | $2.10 | $0.70 |
Output Tokens / Task Tokens generated per task | 55K | 20K |
Reasoning Tokens / Task Thinking tokens burned per task | 30K | 10K |
Spesifikasi Teknis
Architecture, release timeline, capabilities, and modalities.
| Feature | Claude Sonnet 4.5 | Claude Haiku 4.5 |
|---|---|---|
| Official API Model ID (SDK) | claude-sonnet-4-5-20251101 | claude-haiku-4-5-20251001 |
| API Protocol | Anthropic Messages API + AWS Bedrock + Vertex AI | Anthropic Messages API + AWS Bedrock + Vertex AI |
| Release Date | 2025-11 | 2025-10 |
| Knowledge Cutoff | March 2025 | July 2025 |
| Architecture | Hybrid Reasoning | Lightweight High-Speed Multimodal Transformer |
| Parameters | Confidential | Confidential |
| Enterprise Rate Limits (RPM / TPM) | 4,000 – 10,000 RPM (Tier 4 + Priority Tier) · 4,000,000 – 10,000,000 TPM | 4,000 – 10,000 RPM (Tier 4 + Priority Tier) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens | Standard rate up to 200K tokens; 2x input/output tier above 200K tokens |
| Prompt Cache Policy & TTL | $0.3/1M cached read (90% off); 5-min default & 1-hour extended TTL | $0.1/1M cached read (90% off); 5-min default & 1-hour extended TTL |
| Computer Use / GUI Agent | Supported (Screen coordinate grounding, browser & desktop GUI action loops) | Supported (Screen coordinate grounding, browser & desktop GUI action loops) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Native Web Search Citations + Code Execution Tool + MCP Connectors | Native Web Search Citations + Code Execution Tool + MCP Connectors |
| Official Fine-Tuning Support | Custom Model Tuning via Amazon Bedrock & Prompt Distillation | Custom Model Tuning via Amazon Bedrock & Prompt Distillation |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | Anthropic RSP ASL-2 / ASL-3 Constitutional Safety Evaluated | Anthropic RSP ASL-2 / ASL-3 Constitutional Safety Evaluated |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text, vision | text, vision |
| Output Modalities | text | text |
Claude Sonnet 4.5 vs Claude Haiku 4.5: Jawaban Cepat (FAQ)
Which is more intelligent, Claude Sonnet 4.5 or Claude Haiku 4.5?
Claude Sonnet 4.5 is more intelligent. It scores 91 compared with 54 on the composite Intelligence Index.
Which model is faster?
Claude Haiku 4.5 is faster, generating 140 tokens per second compared with 90 tokens per second.
Which model is cheaper to run?
Claude Haiku 4.5 is cheaper at $0.77 per 1M tokens blended, compared with $2.31 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Claude Haiku 4.5 has lower latency, with a time to first token of 0.28s compared with 0.90s.
Which model has a larger context window?
Claude Sonnet 4.5 has a larger context window, supporting 1M tokens compared with 200K tokens.
Kesimpulan
Baik Claude Sonnet 4.5 (Sangat cocok untuk penalaran perusahaan garis depan, pemrograman tingkat lanjut, dan produksi AI, sistem RAG perusahaan, dan integrasi API skala produksi.) maupun Claude Haiku 4.5 (Sangat cocok untuk interaksi real-time dengan latensi sangat rendah dan routing bervolume tinggi, sistem RAG perusahaan, dan integrasi API skala produksi.) sangat tangguh: Claude Sonnet 4.5 unggul dalam penalaran dan pemrograman, Claude Haiku 4.5 memberikan kecepatan generasi token lebih tinggi, dan Claude Haiku 4.5 lebih hemat biaya untuk penggunaan API skala besar.
Pertanyaan Umum (FAQ)
Mana yang lebih baik untuk coding dan penalaran, Claude Sonnet 4.5 atau Claude Haiku 4.5?+
Dalam indeks kecerdasan gabungan dan benchmark coding, Claude Sonnet 4.5 memimpin. Lihat skor SWE-bench dan GPQA di atas untuk detailnya.
Berapa perbandingan harga API Claude Sonnet 4.5 vs Claude Haiku 4.5?+
Claude Sonnet 4.5 mengenakan biaya $3.00 / $15.00 per 1M token input/output, sedangkan Claude Haiku 4.5 sebesar $1.00 / $5.00. Secara keseluruhan, Claude Haiku 4.5 lebih hemat biaya.
Model mana yang memiliki jendela konteks lebih besar dan kecepatan lebih tinggi?+
Claude Sonnet 4.5 mendukung konteks 1M token dibandingkan 200K token pada Claude Haiku 4.5, sementara Claude Haiku 4.5 unggul dalam kecepatan output token per detik.
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Claude Haiku 4.5 vs GPT-5 Chat: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Gemini 3.1 Pro vs Claude Sonnet 4.5: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- GPT-5 mini vs Claude Haiku 4.5: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- GPT-5 nano vs Claude Haiku 4.5: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Aion-3.0 vs Aion-Mini: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
- Aion-3.0 vs Gemini 3.6 Flash: Perbandingan Benchmark, Harga API & Kecepatan (2026)Bandingkan
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
Sumber resmi: Dokumentasi API resmi Anthropic & Anthropic serta evaluasi benchmark independen (2026).