Nemotron Content Safety Reasoning 4B vs GPT OSS Safeguard 120B
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
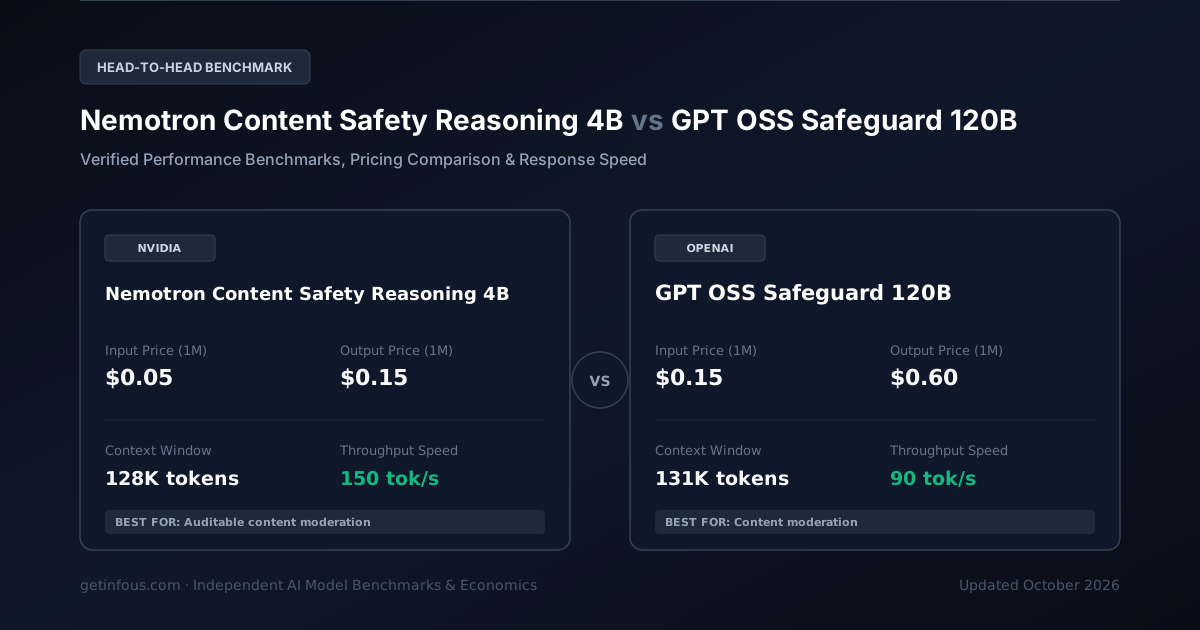
NVIDIA 的 Nemotron Content Safety Reasoning 4B 与 OpenAI 的 GPT OSS Safeguard 120B 是当前备受关注的两款主力 AI 模型。Nemotron Content Safety Reasoning 4B 提供 128K Token 上下文窗口,API 定价为每百万 Token 输入 $0.05 / 输出 $0.15;而 GPT OSS Safeguard 120B 提供 131.1K Token 上下文窗口,定价为每百万 Token 输入 $0.15 / 输出 $0.60。以下为两者的基准测试、延迟与成本全面对比。
切换并对比任意模型
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Nemotron Content Safety Reasoning 4B
开源权重推理大模型NVIDIA 推出的 Nemotron Content Safety Reasoning 4B 是一款通过大规模强化学习训练、支持私有化部署的开源权重推理大模型,具备 128K 上下文窗口、150 Token/秒生成速度与 38/100 综合智能指数(每百万 Token $0.05 输入 / $0.15 输出)。
$0.05 / 1M
$0.15 / 1M
128K tokens
N/A
GPT OSS Safeguard 120B
开源权重基础大模型OpenAI 推出的 GPT OSS Safeguard 120B 是一款支持私有云服务器自托管、微调与完全数据主权的开源权重基础大模型,具备 131K 上下文窗口、90 Token/秒生成速度与 52/100 综合智能指数(每百万 Token $0.15 输入 / $0.6 输出)。
$0.15 / 1M
$0.60 / 1M
131.1K tokens
41%
核心差异一览
- Nemotron Content Safety Reasoning 4B is 3.5x cheaper for API usage (input + output tokens combined).
- GPT OSS Safeguard 120B has a larger context window (131K vs 128K tokens).
- Nemotron Content Safety Reasoning 4B is faster at 150 tok/s vs 90 tok/s.
| Feature | Nemotron Content Safety Reasoning 4B | GPT OSS Safeguard 120B |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 38 | 52 |
Provider | NVIDIA | OpenAI |
Input Price Cost per million input tokens | $0.05 / 1M | $0.15 / 1M |
Output Price Cost per million output tokens | $0.15 / 1M | $0.60 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $0.03 / 1M | $0.10 / 1M |
Context Window Maximum input + output tokens | 128K tokens~192 A4 pages of text | 131.1K tokens~197 A4 pages of text |
Max Output Tokens Per single request | 4K | 33K |
Throughput Speed Tokens generated per second | 150 tok/s | 90 tok/s |
SWE-bench Verified Real-world software engineering | N/A | 41% |
GPQA Diamond Graduate-level reasoning | N/A | 65% |
Cached Input Price Prompt caching discount per 1M tokens | $0.01 / 1M | $0.01 / 1M |
各项指标谁更胜一筹?
At-a-glance decision frameworkEvaluations ongoing
权威基准测试得分对比
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Extremely difficult, closed-ended questions spanning the frontier of human expert knowledge.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
Research-grade coding problems drawn from real scientific and numerical workloads.
Contamination-free competitive programming problems collected continuously over time.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
延迟与响应速度
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
实时 Token 成本模拟器
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Nemotron Content Safety Reasoning 4B · Strengths & Key Advantages
- 提供 128K 上下文窗口与最高 4K 输出容量,核心基准表现优异(Arena Elo 1190)
- 高达 150 Token/秒的生成吞吐量,首字延迟 (TTFT) 仅约 240 毫秒
- 开放模型权重 (4B),支持通过 vLLM、SGLang 或 Ollama 在私有 GPU 集群上本地部署与微调
Considerations & Trade-offs
- 在本地以满血精度运行需要较高的 GPU 显存 (VRAM) 与运维基础设施
- 在超长链路的前沿科研推导任务上,深度略逊于顶配重型旗舰推理模型
GPT OSS Safeguard 120B · Strengths & Key Advantages
- 提供 131K 上下文窗口与最高 33K 输出容量,核心基准表现优异(SWE-bench Verified 41% · GPQA Diamond 65%)
- 高达 90 Token/秒的生成吞吐量,首字延迟 (TTFT) 仅约 520 毫秒
- 开放模型权重 (117B (5.1B MoE)),支持通过 vLLM、SGLang 或 Ollama 在私有 GPU 集群上本地部署与微调
Considerations & Trade-offs
- 在本地以满血精度运行需要较高的 GPU 显存 (VRAM) 与运维基础设施
- 在超长链路的前沿科研推导任务上,深度略逊于顶配重型旗舰推理模型
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Nemotron Content Safety Reasoning 4B | GPT OSS Safeguard 120B |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.02 | $0.13 |
Output Tokens / Task Tokens generated per task | 4K | 40K |
Reasoning Tokens / Task Thinking tokens burned per task | 2K | 20K |
技术规格参数
Architecture, release timeline, capabilities, and modalities.
| Feature | Nemotron Content Safety Reasoning 4B | GPT OSS Safeguard 120B |
|---|---|---|
| Official API Model ID (SDK) | nemotron-content-safety-reasoning-4b | gpt-oss-safeguard-120b |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI Responses API & Chat Completions v1 |
| Release Date | 2026-01 | 2025-10 |
| Knowledge Cutoff | November 2025 | June 2024 |
| Architecture | Reasoning-Augmented Safety Classifier | Sparse MoE safety-classifier model |
| Parameters | 4B | 117B (5.1B active MoE) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Flat rate ($0.05/1M in) across full 128K window | Flat rate ($0.15/1M in) across full 131K window |
| Prompt Cache Policy & TTL | Cached input at $0.01/1M tokens | Automatic prefix caching at $0.015/1M (no extra cache-write fee) |
| Computer Use / GUI Agent | Text-only completion (No GUI action loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Prompt-based JSON extraction only | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Native Web Search tool + Hosted Code Interpreter & File Search RAG |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 2 GB VRAM (4-bit Quantized) · 9 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 73 GB VRAM (4-bit Quantized) · 252 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | OpenAI Preparedness Framework Audited & System Card Published |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text | text |
| Output Modalities | text | text |
Nemotron Content Safety Reasoning 4B vs GPT OSS Safeguard 120B: 常见问题解答 (FAQ)
Which is more intelligent, Nemotron Content Safety Reasoning 4B or GPT OSS Safeguard 120B?
GPT OSS Safeguard 120B is more intelligent. It scores 52 compared with 38 on the composite Intelligence Index.
Which model is faster?
Nemotron Content Safety Reasoning 4B is faster, generating 150 tokens per second compared with 90 tokens per second.
Which model is cheaper to run?
Nemotron Content Safety Reasoning 4B is cheaper at $0.03 per 1M tokens blended, compared with $0.10 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Nemotron Content Safety Reasoning 4B has lower latency, with a time to first token of 0.24s compared with 0.52s.
Which model has a larger context window?
GPT OSS Safeguard 120B has a larger context window, supporting 131.1K tokens compared with 128K tokens.
综合结论
综合来看,Nemotron Content Safety Reasoning 4B(适合:通过大规模强化学习训练、支持私有化部署的开源权重推理任务、企业级 RAG 检索增强生成、自动化智能体工作流与高可靠 API 集成。)与 GPT OSS Safeguard 120B(适合:支持私有云服务器自托管、微调与完全数据主权的开源权重基础任务、企业级 RAG 检索增强生成、自动化智能体工作流与高可靠 API 集成。)各具优势:GPT OSS Safeguard 120B 在综合智能与编程基准测试中表现更强,Nemotron Content Safety Reasoning 4B 拥有更快的 Token 生成速度,而 Nemotron Content Safety Reasoning 4B 则在规模化 API 部署中具备更高的成本效益。
常见问题 (FAQ)
在编程和深度推理方面,Nemotron Content Safety Reasoning 4B 和 GPT OSS Safeguard 120B 哪个更强?+
在综合智能指数与编程基准评测中,GPT OSS Safeguard 120B 表现占优。建议结合上方的 SWE-bench Verified 与 GPQA Diamond 跑分根据具体场景选择。
Nemotron Content Safety Reasoning 4B 与 GPT OSS Safeguard 120B 的 API 价格哪个更便宜?+
Nemotron Content Safety Reasoning 4B 的 API 价格为输入 $0.05 / 输出 $0.15(每百万 Token),GPT OSS Safeguard 120B 为输入 $0.15 / 输出 $0.60。综合混合成本来看,Nemotron Content Safety Reasoning 4B 更具性价比。
哪款模型拥有更大的上下文窗口和更快的响应速度?+
Nemotron Content Safety Reasoning 4B 支持 128K Token 上下文窗口,而 GPT OSS Safeguard 120B 支持 131.1K Token。在流式生成速度方面,Nemotron Content Safety Reasoning 4B 的吞吐表现更快。
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- GPT OSS Safeguard 120B vs Llama 3.1 Nemotron Safety Guard 8B v3:基准测试、API 价格与速度全面对比 (2026)对比
- Nemotron 3.5 Content Safety vs GPT OSS Safeguard 120B:基准测试、API 价格与速度全面对比 (2026)对比
- Nemotron 3 Content Safety vs GPT OSS Safeguard 120B:基准测试、API 价格与速度全面对比 (2026)对比
- Nemotron 3 Content Safety vs Nemotron Content Safety Reasoning 4B:基准测试、API 价格与速度全面对比 (2026)对比
- Nemotron Content Safety Reasoning 4B vs Llama 3.1 Nemotron Safety Guard 8B v3:基准测试、API 价格与速度全面对比 (2026)对比
- Aion-3.0 vs Aion-Mini:基准测试、API 价格与速度全面对比 (2026)对比
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
数据来源: NVIDIA 与 OpenAI 官方 API 文档、模型发布说明及独立基准测试报告 (2026)。