GPT-3 vs GPT-3.5 Turbo
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
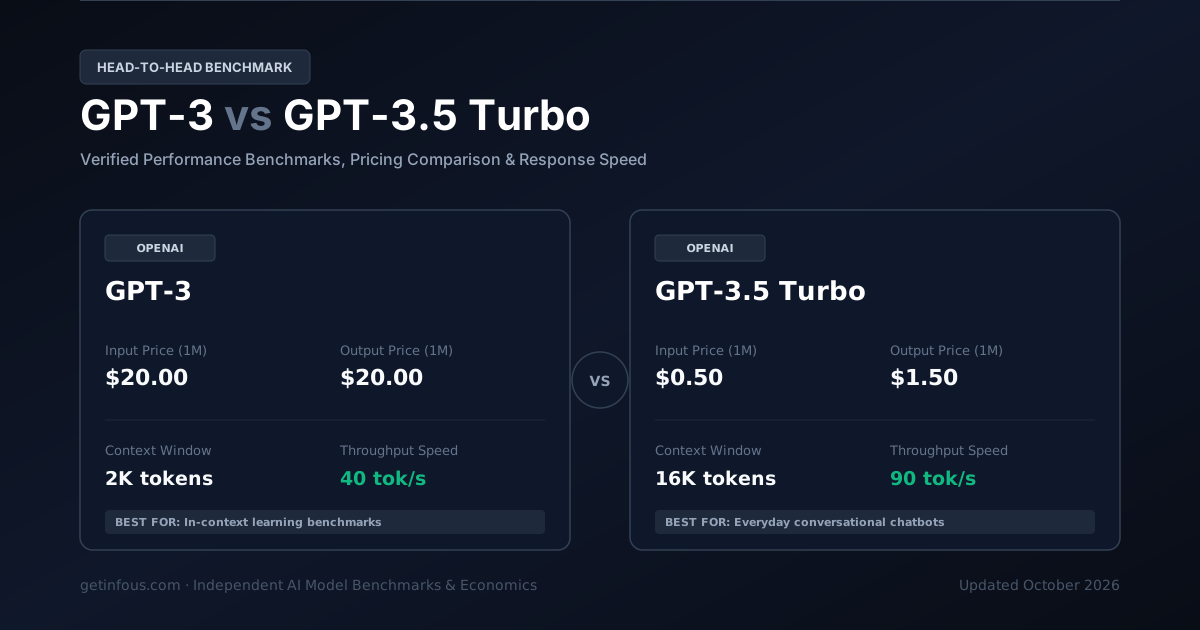
OpenAI 的 GPT-3 与 OpenAI 的 GPT-3.5 Turbo 是当前备受关注的两款主力 AI 模型。GPT-3 提供 2K Token 上下文窗口,API 定价为每百万 Token 输入 $20.00 / 输出 $20.00;而 GPT-3.5 Turbo 提供 16.4K Token 上下文窗口,定价为每百万 Token 输入 $0.50 / 输出 $1.50。以下为两者的基准测试、延迟与成本全面对比。
切换并对比任意模型
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
GPT-3
经典世代基础模型OpenAI 推出的 GPT-3 是一款面向企业级对话与通用文本生成任务的高可靠性经典大模型,具备 2K 上下文窗口、40 Token/秒生成速度与 22/100 综合智能指数(每百万 Token $20 输入 / $20 输出)。
$20.00 / 1M
$20.00 / 1M
2K tokens
N/A
GPT-3.5 Turbo
超高速低延迟推理OpenAI 推出的 GPT-3.5 Turbo 是一款面向实时交互对话、高并发路由与极低延迟生产环境的超高速大模型,具备 16K 上下文窗口、90 Token/秒生成速度与 30/100 综合智能指数(每百万 Token $0.5 输入 / $1.5 输出)。
$0.50 / 1M
$1.50 / 1M
16.4K tokens
12.5%
核心差异一览
- GPT-3.5 Turbo is 22.4x cheaper for API usage (input + output tokens combined).
- GPT-3.5 Turbo has a larger context window (16K vs 2K tokens).
- GPT-3.5 Turbo is faster at 90 tok/s vs 40 tok/s.
| Feature | GPT-3 | GPT-3.5 Turbo |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 22 | 30 |
Provider | OpenAI | OpenAI |
Input Price Cost per million input tokens | $20.00 / 1M | $0.50 / 1M |
Output Price Cost per million output tokens | $20.00 / 1M | $1.50 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $9.50 / 1M | $0.42 / 1M |
Context Window Maximum input + output tokens | 2K tokens~3 A4 pages of text | 16.4K tokens~25 A4 pages of text |
Max Output Tokens Per single request | 2K | 4K |
Throughput Speed Tokens generated per second | 40 tok/s | 90 tok/s |
SWE-bench Verified Real-world software engineering | N/A | 12.5% |
GPQA Diamond Graduate-level reasoning | N/A | 28% |
Cached Input Price Prompt caching discount per 1M tokens | $5.00 / 1M | $0.25 / 1M |
各项指标谁更胜一筹?
At-a-glance decision frameworkEvaluations ongoing
权威基准测试得分对比
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Tokens emitted per second during active generation streaming.
延迟与响应速度
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
实时 Token 成本模拟器
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
GPT-3 · Strengths & Key Advantages
- 提供 2K 上下文窗口与最高 2K 输出容量,核心基准表现优异(MMLU-Pro 43.9% · Arena Elo 980)
- 高达 40 Token/秒的生成吞吐量,首字延迟 (TTFT) 仅约 900 毫秒
- 极具竞争力的 API 定价(每百万 Token $20 输入 / $20 输出),原生支持提示词缓存、函数调用与结构化 JSON 输出
Considerations & Trade-offs
- 闭源专有云端模型,不支持下载权重进行离线本地物理隔离部署
- 在大规模高频调用场景下,建议结合提示词缓存 (Prompt Caching) 与批量 API 以控制成本
GPT-3.5 Turbo · Strengths & Key Advantages
- 提供 16K 上下文窗口与最高 4K 输出容量,核心基准表现优异(SWE-bench Verified 12.5% · GPQA Diamond 28%)
- 高达 90 Token/秒的生成吞吐量,首字延迟 (TTFT) 仅约 450 毫秒
- 极具竞争力的 API 定价(每百万 Token $0.5 输入 / $1.5 输出),原生支持提示词缓存、函数调用与结构化 JSON 输出
Considerations & Trade-offs
- 闭源专有云端模型,不支持下载权重进行离线本地物理隔离部署
- 在超长链路的前沿科研推导任务上,深度略逊于顶配重型旗舰推理模型
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | GPT-3 | GPT-3.5 Turbo |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.20 | $0.20 |
Output Tokens / Task Tokens generated per task | 24K | 24K |
Reasoning Tokens / Task Thinking tokens burned per task | 0K | 0K |
技术规格参数
Architecture, release timeline, capabilities, and modalities.
| Feature | GPT-3 | GPT-3.5 Turbo |
|---|---|---|
| Official API Model ID (SDK) | gpt-3 | gpt-3-5-turbo |
| API Protocol | OpenAI Responses API & Chat Completions v1 | OpenAI Responses API & Chat Completions v1 |
| Release Date | 2020-06 | 2022-11 |
| Knowledge Cutoff | June 2020 | September 2021 |
| Architecture | Autoregressive Transformer (Davinci) | Transformer with RLHF & PPO |
| Parameters | 175B | Confidential (est. 20B MoE / 175B base) |
| Enterprise Rate Limits (RPM / TPM) | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM | 10,000 – 30,000 RPM (Tier 5 Enterprise) · 800,000 – 2,000,000 TPM |
| Long-Context Tier (>128K/200K) | Flat rate ($20/1M in) across full 2K window | Flat rate ($0.5/1M in) across full 16K window |
| Prompt Cache Policy & TTL | Automatic prefix caching at $5/1M (no extra cache-write fee) | Automatic prefix caching at $0.25/1M (no extra cache-write fee) |
| Computer Use / GUI Agent | Text-only completion (No GUI action loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Prompt-based JSON extraction only | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Native Web Search tool + Hosted Code Interpreter & File Search RAG | Native Web Search tool + Hosted Code Interpreter & File Search RAG |
| Official Fine-Tuning Support | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) | Supervised Fine-Tuning (SFT), Direct Preference (DPO) & Reinforcement Fine-Tuning (RFT) |
| Multimodal Token Billing | Text BPE (~4 chars/token) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) | Cloud-Hosted Proprietary (FP8 / BF16 Tensor Core Cluster) · Zero Local VRAM Required (100% Serverless Cloud API) |
| Safety & Frontier Classification | OpenAI Preparedness Framework Audited & System Card Published | OpenAI Preparedness Framework Audited & System Card Published |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier | SOC2 Type II · GDPR · Zero Data Retention (ZDR) & HIPAA BAA Available on Enterprise Tier |
| Input Modalities | text | text |
| Output Modalities | text | text |
GPT-3 vs GPT-3.5 Turbo: 常见问题解答 (FAQ)
Which is more intelligent, GPT-3 or GPT-3.5 Turbo?
GPT-3.5 Turbo is more intelligent. It scores 30 compared with 22 on the composite Intelligence Index.
Which model is faster?
GPT-3.5 Turbo is faster, generating 90 tokens per second compared with 40 tokens per second.
Which model is cheaper to run?
GPT-3.5 Turbo is cheaper at $0.42 per 1M tokens blended, compared with $9.50 (7:2:1 cache:input:output ratio).
Which model has lower latency?
GPT-3.5 Turbo has lower latency, with a time to first token of 0.45s compared with 0.90s.
Which model has a larger context window?
GPT-3.5 Turbo has a larger context window, supporting 16.4K tokens compared with 2K tokens.
综合结论
综合来看,GPT-3(适合:面向企业级对话与通用文本生成任务的高可靠性经典任务、企业级 RAG 检索增强生成、自动化智能体工作流与高可靠 API 集成。)与 GPT-3.5 Turbo(适合:面向实时交互对话、高并发路由与极低延迟生产环境的超高速任务、企业级 RAG 检索增强生成、自动化智能体工作流与高可靠 API 集成。)各具优势:GPT-3.5 Turbo 在综合智能与编程基准测试中表现更强,GPT-3.5 Turbo 拥有更快的 Token 生成速度,而 GPT-3.5 Turbo 则在规模化 API 部署中具备更高的成本效益。
常见问题 (FAQ)
在编程和深度推理方面,GPT-3 和 GPT-3.5 Turbo 哪个更强?+
在综合智能指数与编程基准评测中,GPT-3.5 Turbo 表现占优。建议结合上方的 SWE-bench Verified 与 GPQA Diamond 跑分根据具体场景选择。
GPT-3 与 GPT-3.5 Turbo 的 API 价格哪个更便宜?+
GPT-3 的 API 价格为输入 $20.00 / 输出 $20.00(每百万 Token),GPT-3.5 Turbo 为输入 $0.50 / 输出 $1.50。综合混合成本来看,GPT-3.5 Turbo 更具性价比。
哪款模型拥有更大的上下文窗口和更快的响应速度?+
GPT-3 支持 2K Token 上下文窗口,而 GPT-3.5 Turbo 支持 16.4K Token。在流式生成速度方面,GPT-3.5 Turbo 的吞吐表现更快。
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- GPT-4 vs GPT-3.5 Turbo:基准测试、API 价格与速度全面对比 (2026)对比
- GPT-4 vs GPT-3:基准测试、API 价格与速度全面对比 (2026)对比
- Aion-3.0 vs Aion-Mini:基准测试、API 价格与速度全面对比 (2026)对比
- Aion-3.0 vs Gemini 3.6 Flash:基准测试、API 价格与速度全面对比 (2026)对比
- Aion-Mini vs Laguna XS 2.1:基准测试、API 价格与速度全面对比 (2026)对比
- Aya Expanse 32B vs Llama 3.2 90B Vision:基准测试、API 价格与速度全面对比 (2026)对比
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
数据来源: OpenAI 与 OpenAI 官方 API 文档、模型发布说明及独立基准测试报告 (2026)。