Command A Plus vs Command A Reasoning
Benchmarks, API Token Pricing, Context Window & Speed Comparison
Related topics (12)
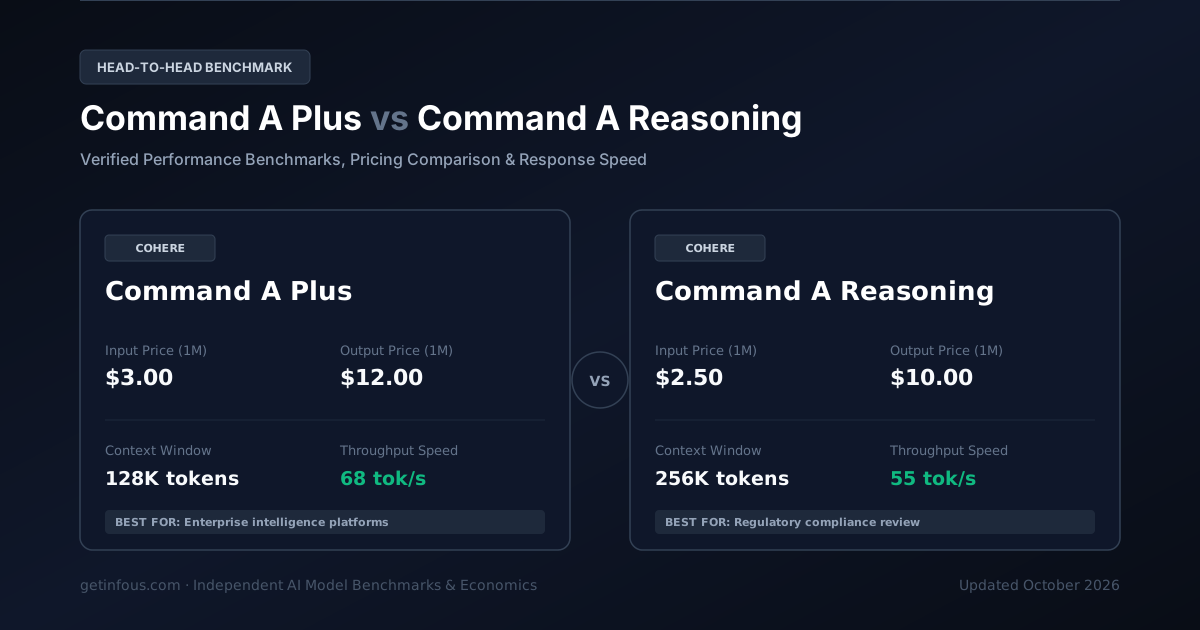
CohereのCommand A PlusとCohereのCommand A Reasoningは、注目度の高い主要AIモデルです。Command A Plusは128K トークンのコンテキストウィンドウを備え、API料金は100万トークンあたり入力$3.00/出力$12.00、一方のCommand A Reasoningは256K トークンのコンテキストで入力$2.50/出力$10.00です。以下でベンチマーク、速度、コストを詳しく比較します。
任意のAIモデルを切り替えて比較
Select any AI models from our verified benchmark database to generate live side-by-side matrices.
Command A Plus
オープンウェイト基盤モデルCohere の Command A Plus は、オンプレミス環境でのセルフホスト、ファインチューニング、完全なデータ主権の確保向けに設計されたAIモデルです。128K のコンテキストウィンドウ、毎秒 68 トークンの生成速度、知能指数 58/100(1Mトークンあたり入力$3・出力$12)を実現しています。
$3.00 / 1M
$12.00 / 1M
128K tokens
60.5%
Command A Reasoning
オープンウェイト推論モデルCohere の Command A Reasoning は、強化学習により鍛えられた高効率なオープンウェイト論理推論向けに設計されたAIモデルです。256K のコンテキストウィンドウ、毎秒 55 トークンの生成速度、知能指数 55/100(1Mトークンあたり入力$2.5・出力$10)を実現しています。
$2.50 / 1M
$10.00 / 1M
256K tokens
53%
ひと目でわかる主な違い
- Command A Reasoning is 1.2x cheaper for API usage (input + output tokens combined).
- Command A Reasoning has a larger context window (256K vs 128K tokens).
- Command A Plus is faster at 68 tok/s vs 55 tok/s.
- Command A Plus leads on SWE-bench coding (60.5% vs 53.0%).
| Feature | Command A Plus | Command A Reasoning |
|---|---|---|
Intelligence Index Composite reasoning & knowledge score (0-100) | 58 | 55 |
Provider | Cohere | Cohere |
Input Price Cost per million input tokens | $3.00 / 1M | $2.50 / 1M |
Output Price Cost per million output tokens | $12.00 / 1M | $10.00 / 1M |
Blended Price Weighted 7:2:1 cache:input:output per 1M | $2.33 / 1M | $2.02 / 1M |
Context Window Maximum input + output tokens | 128K tokens~192 A4 pages of text | 256K tokens~384 A4 pages of text |
Max Output Tokens Per single request | 33K | 33K |
Throughput Speed Tokens generated per second | 68 tok/s | 55 tok/s |
SWE-bench Verified Real-world software engineering | 60.5% | 53% |
GPQA Diamond Graduate-level reasoning | 74% | 70% |
Cached Input Price Prompt caching discount per 1M tokens | $0.75 / 1M | $0.75 / 1M |
分野別勝者スコアカード
At-a-glance decision framework検証済みベンチマークスコア比較
Official evaluation metrics verified by independent third-party research labs.
Industry benchmark evaluating real-world GitHub issue resolution and multi-file debugging.
Challenging questions created by domain experts to test complex PhD-level reasoning.
Hardened reasoning and academic knowledge benchmark with reduced lucky-guess probability.
Crowdsourced human preference evaluation based on blind, head-to-head model battles.
Autonomous multi-step tasks executed inside a real command-line terminal environment.
American Invitational Mathematics Examination — multi-step Olympiad-level reasoning.
Accuracy when reasoning over very large inputs that fill the model context window.
Tokens emitted per second during active generation streaming.
レイテンシ&応答時間
Time to first token (TTFT) and estimated end-to-end response time for a typical 500-token response.
リアルタイムAPIトークン料金シミュレーター
Adjust sliders to calculate projected monthly cloud API spending with prompt caching discounts.
Command A Plus · Strengths & Key Advantages
- 128K のコンテキストウィンドウと最大 33K トークンの出力容量(SWE-bench Verified 60.5% · GPQA Diamond 74%)
- 毎秒 68 トークンの高速スループットと、初回トークン到達時間(TTFT)わずか 560ms の低遅延
- オープンウェイトモデル (Confidential (~180B+ MoE))として vLLM・SGLang・Ollama を用いた自社GPUでのローカル運用が可能
Considerations & Trade-offs
- 非量子化のフル精度でローカル推論を行うには十分なGPU VRAM容量が必要です
- 大量のトークンを処理する本番環境では、プロンプトキャッシュや Batch API の併用によるコスト最適化が推奨されます
Command A Reasoning · Strengths & Key Advantages
- 256K のコンテキストウィンドウと最大 33K トークンの出力容量(SWE-bench Verified 53% · GPQA Diamond 70%)
- 毎秒 55 トークンの高速スループットと、初回トークン到達時間(TTFT)わずか 750ms の低遅延
- オープンウェイトモデル (Confidential (~100B+))として vLLM・SGLang・Ollama を用いた自社GPUでのローカル運用が可能
Considerations & Trade-offs
- 非量子化のフル精度でローカル推論を行うには十分なGPU VRAM容量が必要です
- 大量のトークンを処理する本番環境では、プロンプトキャッシュや Batch API の併用によるコスト最適化が推奨されます
Token Use & Task Economics
Estimated cost and token consumption to complete one representative agentic task.
| Metric | Command A Plus | Command A Reasoning |
|---|---|---|
Cost per Task Estimated USD to finish one task | $0.85 | $0.95 |
Output Tokens / Task Tokens generated per task | 45K | 45K |
Reasoning Tokens / Task Thinking tokens burned per task | 22K | 22K |
技術仕様・スペック
Architecture, release timeline, capabilities, and modalities.
| Feature | Command A Plus | Command A Reasoning |
|---|---|---|
| Official API Model ID (SDK) | command-a-plus | command-a-reasoning |
| API Protocol | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI | OpenAI-Compatible REST / vLLM / SGLang / HuggingFace TGI |
| Release Date | 2026-05 | 2025-08 |
| Knowledge Cutoff | March 2026 | June 2025 |
| Architecture | Flagship Multimodal Agentic MoE | Enterprise Chain-of-Thought Reasoning Transformer |
| Parameters | Confidential (~180B+ MoE) | Confidential (~100B+) |
| Enterprise Rate Limits (RPM / TPM) | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud | Unlimited (Hardware-bound on self-hosted GPU) / 10,000 RPM Cloud · Unlimited local throughput / 10M+ TPM Managed Cloud |
| Long-Context Tier (>128K/200K) | Flat rate ($3/1M in) across full 128K window | Flat rate ($2.5/1M in) across full 256K window |
| Prompt Cache Policy & TTL | Cached input at $0.75/1M tokens | Cached input at $0.75/1M tokens |
| Computer Use / GUI Agent | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) | API / CLI Tool-Use & DOM Agent ready (no raw pixel desktop click loop) |
| MCP & Parallel Tool Calling | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema | Native MCP Client/Server ready · Parallel function calling · 100% Strict JSON Schema |
| Web Search Grounding & Sandbox | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools | Supported via external Tavily/Exa Search & E2B/Docker Sandbox tools |
| Official Fine-Tuning Support | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) | Full Weights SFT, LoRA, QLoRA, DPO & GRPO RL (Unsloth / Axolotl / Llama-Factory) |
| Multimodal Token Billing | Text BPE (~4 chars/token) · Vision (~258–765 tokens per image tile) | Text BPE (~4 chars/token) |
| Quantization & Min GPU VRAM | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 112 GB VRAM (4-bit Quantized) · 387 GB VRAM (Native BF16) | BF16 / FP16, FP8 Dynamic, INT4 AWQ / GPTQ, GGUF (Q4_K_M / Q8_0) · 62 GB VRAM (4-bit Quantized) · 215 GB VRAM (Native BF16) |
| Safety & Frontier Classification | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) | Open-Weights System Card + Customizable Guardrail Layer (Llama Guard / ShieldGemma) |
| Enterprise Compliance (ZDR/HIPAA/SOC2) | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control | 100% Air-Gapped On-Premises / Private VPC · Full HIPAA, GDPR & SOC2 Control |
| Input Modalities | text, vision | text |
| Output Modalities | text | text |
Command A Plus vs Command A Reasoning: よくある質問 (FAQ)
Which is more intelligent, Command A Plus or Command A Reasoning?
Command A Plus is more intelligent. It scores 58 compared with 55 on the composite Intelligence Index.
Which model is faster?
Command A Plus is faster, generating 68 tokens per second compared with 55 tokens per second.
Which model is cheaper to run?
Command A Reasoning is cheaper at $2.02 per 1M tokens blended, compared with $2.33 (7:2:1 cache:input:output ratio).
Which model has lower latency?
Command A Plus has lower latency, with a time to first token of 0.56s compared with 0.75s.
Which model has a larger context window?
Command A Reasoning has a larger context window, supporting 256K tokens compared with 128K tokens.
総合評価
Command A Plus(オンプレミス環境でのセルフホスト、ファインチューニング、完全なデータ主権の確保、エンタープライズRAG基盤、スケーラブルな本番API統合に最適。)とCommand A Reasoning(強化学習により鍛えられた高効率なオープンウェイト論理推論、エンタープライズRAG基盤、スケーラブルな本番API統合に最適。)はいずれも優れた選択肢です。高度な推論・コーディング精度ではCommand A Plusがリードし、応答速度とスループットではCommand A Plusが優れ、APIコスト効率ではCommand A Reasoningが有利です。
よくある質問 (FAQ)
コーディングや複雑な推論には Command A Plus と Command A Reasoning のどちらが適していますか?+
総合知能指数およびコーディング評価では Command A Plus が優位です。上部の SWE-bench や GPQA スコアもあわせてご確認ください。
Command A Plus と Command A Reasoning ではどちらのAPI料金が安いですか?+
Command A Plus は100万トークンあたり入力$3.00 / 出力$12.00、Command A Reasoning は入力$2.50 / 出力$10.00です。総合的なコスト効率では Command A Reasoning がより経済的です。
コンテキスト長と生成速度はどちらが優れていますか?+
コンテキストウィンドウは Command A Plus が 128K トークン、Command A Reasoning が 256K トークン です。出力スピード(トークン/秒)では Command A Plus がリードしています。
Understand key metrics like context window, token pricing, reasoning mode, and SWE-bench scores in our comprehensive AI glossary.
Related reading
- Command A Plus vs Claude Opus 5.5:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Command A Plus vs Command A:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Command A Plus vs Gemini 4 Argon:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Command A Plus vs GPT-6 Astra:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Command A Plus vs Nemotron 3 Ultra 550B A55B:ベンチマーク・API料金・速度の徹底比較 (2026)比較
- Command A Reasoning vs o3:ベンチマーク・API料金・速度の徹底比較 (2026)比較
Benchmark scores, token prices, and rate limits evolve rapidly as AI labs release model updates. Always verify current specifications and pricing on the official provider documentation.
公的ソース: CohereおよびCohere公式APIドキュメント、システムカード、独立ベンチマーク評価 (2026)。